Claude Fable 5.2 is Anthropic's strongest model, and it charges accordingly: twice the price of Opus 5.5 and, on input tokens, 80 times the price of Haiku 5.5. Anyone who runs it on every task will hit subscription limits quickly. Anthropic's own model guide, together with public advice from the creator of Claude Code and from Andrej Karpathy, points to a handful of settings and habits that cut the bill without giving up Fable's judgment where it matters: make Opus 5.5 on Medium effort the default, pin background helper agents to Haiku 5.5, keep reasoning effort in check, and reserve Fable 5.2 for planning and final review. Just as important is knowing when splitting work across models costs more than it saves.
What Fable 5.2 costs and why limits disappear
Fable 5.2 currently leads the major benchmarks. On FrontierCode 2.0 it scores 49.1% at High effort, ahead of Opus 5.5 (45.5%), Gemini 4 Carbon (48.1%), GPT-6 Astra (42.8%) and its predecessor Fable 5.1 (32.4%). On FrontierSWE v2 it reaches 69.9%, against 62.3% for Opus 5.5, 65.5% for GPT-6 Astra and 61.2% for Gemini 4 Carbon.
The price gap between Anthropic's tiers is steep:
| Model | Input per million tokens | Output per million tokens |
|---|---|---|
| Fable 5.2 | $8 | $40 |
| Opus 5.5 | $4 | $20 |
| Sonnet 5.5 | $2 | $10 |
| Haiku 5.5 | $0.10 | $0.50 |
A typical document job of 75,000 input words and 15,000 output words comes to roughly $1.60 on Fable 5.2, $0.80 on Opus 5.5, and $0.01 to $0.02 on Haiku 5.5.
Subscribers feel the same gap as quota. On the Max and Ultra plans, Fable 5.2 is included for up to half of the normal weekly allowance, so it burns through quota far faster than other models. On the Pro plan, Fable 5.2 is bundled only for launch week, through November 16, 2026; after that, usage runs on paid credit billing. Boris Cherny, who created Claude Code at Anthropic, has also announced loyalty resets for Fable: accounts subscribed for under six months receive one reset, six to twelve months get two, and more than twelve months get three.
Lever one: Opus 5.5 on Medium as the default
Both Anthropic's guide and Karpathy recommend the same baseline: run Opus 5.5 on Medium effort as the everyday workhorse in Claude Code and the desktop apps, and reach for Fable 5.2 only for the hardest tasks or unattended overnight jobs. Karpathy uses this default for his own projects. Setting it once prevents most accidental Fable spending, because the expensive model then only runs when deliberately chosen.
Lever two: pin search and read helpers to Haiku 5.5
The least visible cost in Claude Code comes from subagents, the background helpers that search files and read codebases outside the main conversation. The built-in Explore subagent can run dozens of times in one session. According to Anthropic's documentation, Explore defaults to the session's parent model, capped at Opus 5.5, rather than to Haiku. In a Fable 5.2 session, every automated lookup therefore runs at Opus prices, about $0.15 for a single file search.
Custom subagents are worse. They have no Opus cap, so an unconfigured helper inherits Fable 5.2 directly and bills $8 in and $40 out for simple text reads.
The fix is a one-line edit. Define an Explore subagent in the Claude Code agents folder with the attribute set to Haiku, and do the same for any custom helper whose job is searching, reading or summarizing:
- Open or create the Explore agent definition in the Claude Code agents directory.
- Add
model: haikuto the agent's configuration. - Repeat for every custom read, search or summarize helper.
In a test asking Claude Code to find which file defines a price table, the Opus-backed Explore agent cost about $0.15. After pinning to Haiku 5.5, the same query returned the same lines from the same file for under one cent, roughly a 50-fold reduction. The reasoning behind the rule: errors in search and summary tasks are easy to spot and do not need deep reasoning, so the cheapest model is the right one. Anthropic applied the same logic internally when it switched the 30-second status updates from background subagents to short Haiku 5.5 notes, which cut the cost of those updates by 99%.
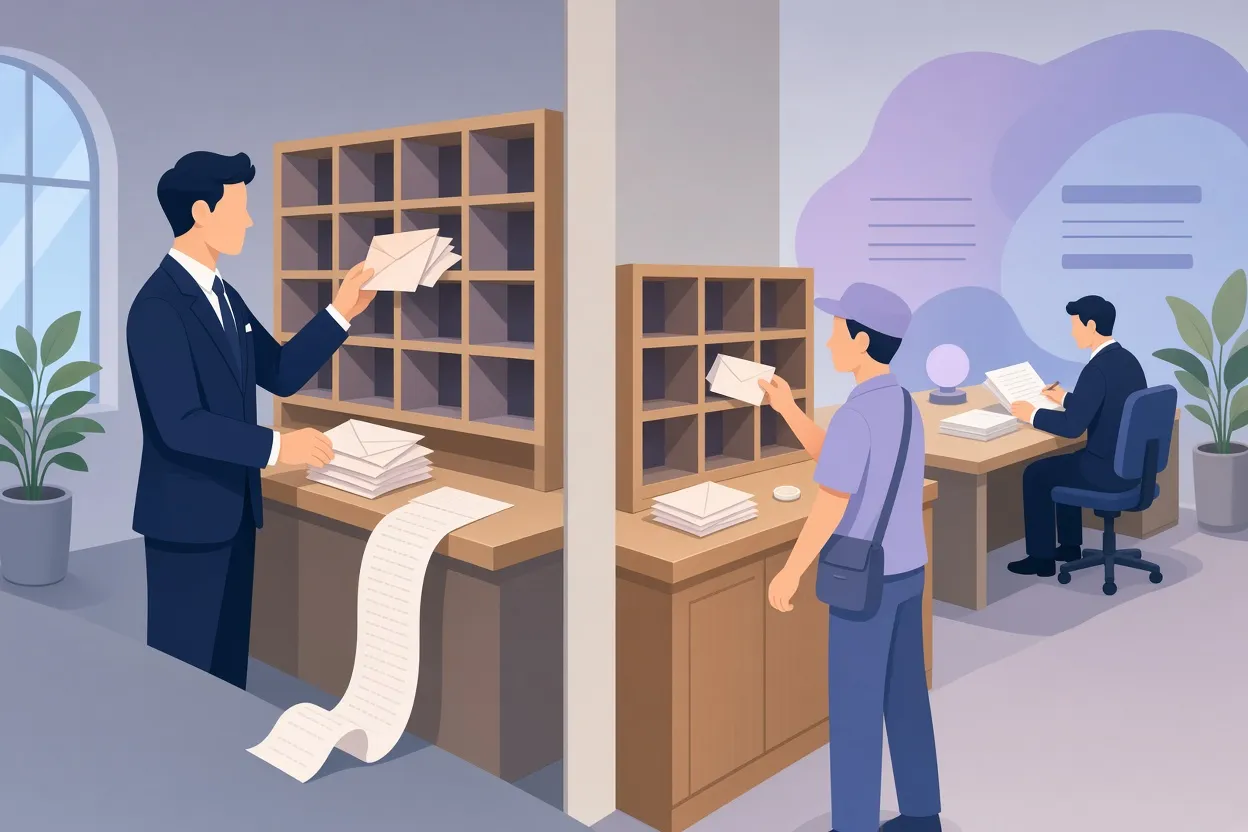
▲ Routing routine searches to Haiku 5.5
Lever three: keep effort at Medium and watch what inherits it
Effort controls how long a model reasons before answering. There are five settings: Low, Medium, High, Extra High and Max. Medium is the default in the Claude apps and Claude Code. Anthropic's guide advises adjusting effort on the current model before stepping up to a more expensive tier.
The cost curve is steep. On Anthropic's Frontier Coding Benchmark, Fable 5.2 performs as follows:
| Effort | Score | Cost per task |
|---|---|---|
| Medium | 37.6% | $2.48 |
| High | 45.3% | $6.72 |
Moving from Medium to High nearly triples the cost for about eight percentage points of accuracy. Beyond High, one extra level can cost as much as switching to a whole larger model tier. A software engineer's test of a single prompt on Fable 5.2 showed the escalation:
| Effort | Cost | Time |
|---|---|---|
| High | $24.31 | 1h 05m |
| Extra High | $43.79 | 3h 09m |
| Max | $87.99 | 3h 28m |
| Ultra | $642.42 | 10h 21m |
Cherny has said that fast quota exhaustion is usually traceable to one or two sessions on Extra High effort, agent teams, or long SDK jobs. The hidden multiplier is inheritance: subagents take the parent session's effort level, so a session on High forces every background search and read helper to reason at High as well. Two habits help: check the effort setting before starting any big task, since a setting left over from an earlier session can quietly persist, and run the /usage command in Claude Code to see where tokens are going across sessions and subagents.
Where Fable 5.2 earns its premium
With Opus 5.5 as the default, helpers pinned to Haiku and effort at Medium, the main waste is gone. The remaining question is where paying double for Fable 5.2 returns more than it costs. Anthropic suggests running identical backlog tasks on both Opus and Fable and comparing the /usage figures.
One such comparison used a client onboarding document seeded with seven intentional flaws and the same prompt for both models. Opus 5.5 found all seven for about $0.20. Fable 5.2 also found all seven, then surfaced eight more structural problems Opus had missed, such as the absence of a procedure for revoking client access when a relationship ends. Opus caught two issues Fable did not, leaving Fable a net advantage of six additional findings for about $0.35, a premium of roughly $0.15.
The practical conclusion is a split: draft and execute 90% to 95% of work on Opus 5.5, and use Fable 5.2 for the final 5% to 10%, the review pass where deeper judgment justifies the price.
The 10-80-10 split and when it backfires
A natural extension is the classic 10-80-10 delegation pattern: a top model plans the job (first 10%), cheaper workers such as Haiku 5.5 and Sonnet 5.5 execute the bulk (middle 80%), and the top model checks the result (final 10%). Anthropic's prompt engineering guide recommends a similar design, with Fable 5.2 as planner and orchestrator and Haiku or Sonnet handling log reading, file searching and summarization. No custom harness is needed; Claude Code can be told to plan the job and spin up subagents itself, for example running three helpers in parallel to proofread a script, generate hook variations and draft a description.
The trap is applying this to small jobs. In a test that audited a video channel's metrics, comparing the top ten videos against a median of about 16,000 views to plan future topics, the three configurations produced very different bills:
| Configuration | Cost | Time |
|---|---|---|
| Fable 5.2 alone | $0.58 | about 1 minute |
| Opus 5.5 alone | $0.51 | about 1.5 minutes |
| Fable 5.2 orchestrating Haiku and Sonnet subagents | $2.50 | — |
The orchestrated run cost nearly five times as much as Fable alone. The result looked like a bug at first, but it is coordination overhead. Think of hiring a project manager to make a sandwich: the manager has to plan, write a brief, wait, inspect and give feedback, all of which costs more than a skilled worker simply making it. In AI terms, the orchestrator spends expensive tokens writing detailed briefs and reading full reports, while each subagent re-reads the context files from scratch. Anthropic's documentation says the same thing directly: for tasks that fit inside a single context window, multi-agent orchestration usually costs more than it saves.
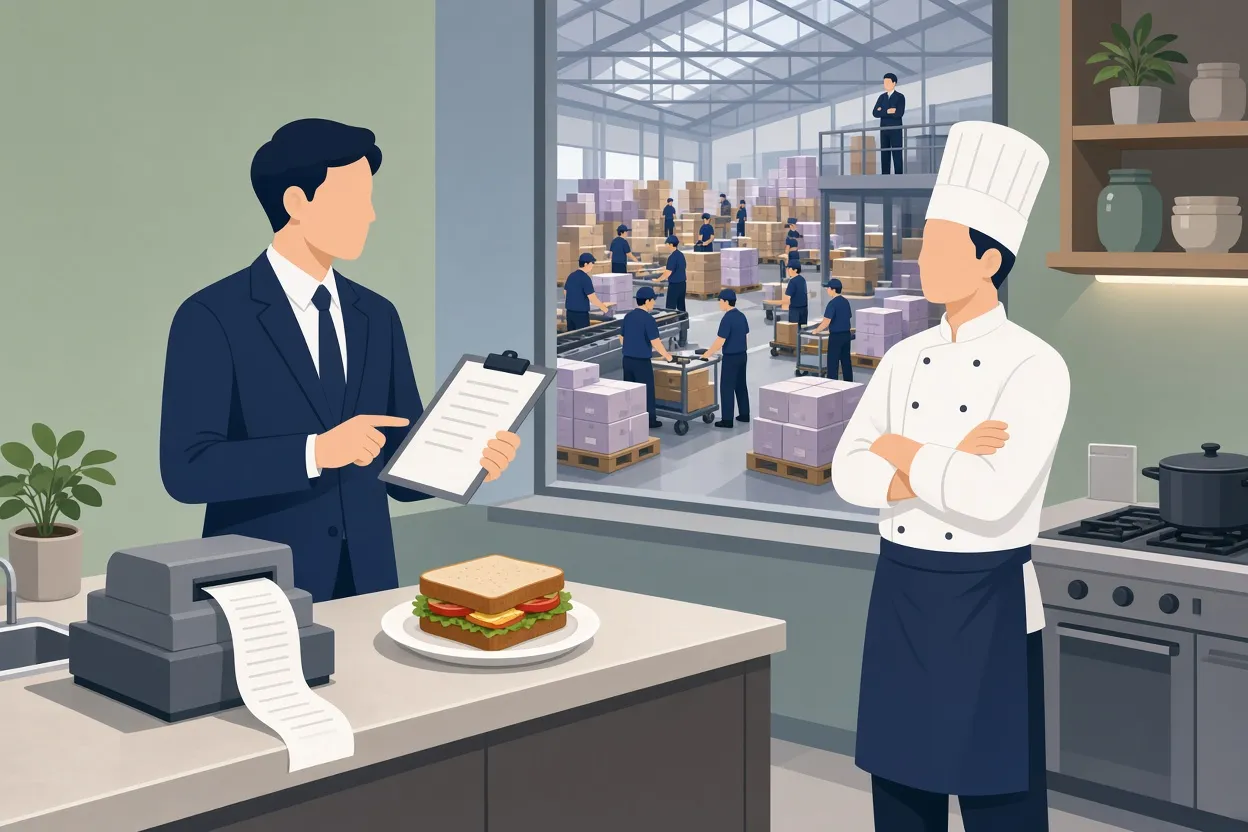
▲ Orchestration overhead on small tasks
The dividing line is the size of the middle 80%. Planning and review by Fable cost roughly the same whether the job is tiny or huge, so delegation only pays when the bulk work is large enough to absorb that fixed overhead. Analyzing 50 full video transcripts qualifies: reading dominates the tokens, and Haiku reads at $0.10 per million versus $8 for Fable. Drafting an email, fixing one bug, or analyzing five to ten video metrics does not; management tokens dominate the bill. A three-line edit to a billing file is faster and cheaper in a single Fable session. Anthropic demonstrated the large-workload case on a defect-search benchmark spanning 22 million tokens of source code, where Opus 5.5 directing Sonnet 5.5 workers finished at one-third less cost than Opus alone with equivalent accuracy. Anthropic also found that telling Fable the price of subagents and instructing it to weigh whether delegation is worthwhile cut unnecessary subagent spawning roughly in half.
Brief cheaper models like new hires
Fable 5.2 can infer intent from terse instructions, which is why elaborate prompt engineering appears largely unnecessary for top-tier models. Sonnet 5.5 and Haiku 5.5 behave differently: given minimal context, they guess, and guessing degrades output. A vague request such as "research competitor videos and summarize" leaves a cheaper model to invent its own assumptions about which channels, which dates and what counts as good.
A useful pattern is to have Fable write the brief before handing work to cheaper models, with five elements:
- Goal: the overarching purpose
- End result: the exact deliverable
- Rules: strict operating constraints
- Don't: what not to do
- If stuck: fallback behavior
Even with a strong brief, budget models make occasional mistakes, which is why the final Fable review remains part of the workflow.
Audit prompts and skills with each new model
Alex Albert, who leads developer relations at Anthropic, shares a habit for every new model release: run a single prompt across all project repositories asking the model to find broken, inconsistent or obsolete code and configuration rules, fix what it is confident about, and list the rest for human review. The same approach extends to an entire AI workspace. Skills in Claude are Markdown instruction files, and an outdated or sloppy skill drags down every model that executes it. Having Fable 5.2 rewrite a skill with tight constraints, for instance a hook-writing skill capped at 12 words, improves the output of Haiku and Sonnet whenever they run it. Because this is a one-time pass rather than ongoing orchestration, it may be one of the highest-leverage uses of a frontier model.
Putting it together
The rules above can be captured in three Claude Code configuration changes:
- A dedicated Explore agent definition set to Haiku 5.5, so file lookups stop running on Opus.
- Delegation guardrails in CLAUDE.md that require Claude to judge task size before splitting work, restrict helpers to cheaper tiers, and include subagent pricing so the orchestrator knows what spawning costs.
- An on-demand reviewer agent set to Fable 5.2 that runs only when explicitly summoned, for example to review a finished script or code change.
For readers who want to act today: set Opus 5.5 on Medium as the default, pin every read, search and summarize helper to Haiku 5.5, confirm the effort level before each major session and check /usage regularly. Keep small jobs inside one model session. Reserve Fable 5.2 for planning, for the final 5% to 10% review, for workloads too large for a single context window, and for a one-time audit of your prompts, skills and configuration files whenever a new model arrives.


