#Claude Fable 5.2
7 articles tagged Claude Fable 5.2
Tagged articles
Articles tagged Claude Fable 5.2, newest first.
 AI News
GPT-6.2 Astra: Cheaper per Task and Strong in 3D, but Not the Top Model
GPT-6.2 Astra's main gain is lower cost per task, not a large intelligence jump. About $4.00 per benchmark task versus about $26.54 for Claude Fable 5.2. Second on the Artificial Analysis index at 62, behind Claude Fable 5.2 at 65. Early testers reported terse output, hard steering and tasks that stop midway. Worth trying for 3D and design work, with GPT-6.2 Sol as the cheaper fallback.
 AI in Practice
Fable 5.2 Cost Control: Medium Effort, Haiku Subagents, Opus as Default
Fable 5.2 costs $8 in and $40 out per million tokens, twice Opus 5.5. Make Opus 5.5 on Medium effort the default, keep Fable for planning and review. Pin Explore and other search helpers to Haiku 5.5 to cut lookup cost about 50-fold. Medium to High effort nearly triples cost per task for an 8 point benchmark gain. Splitting a small job across subagents cost five times a solo run in one test.
 AI Performance
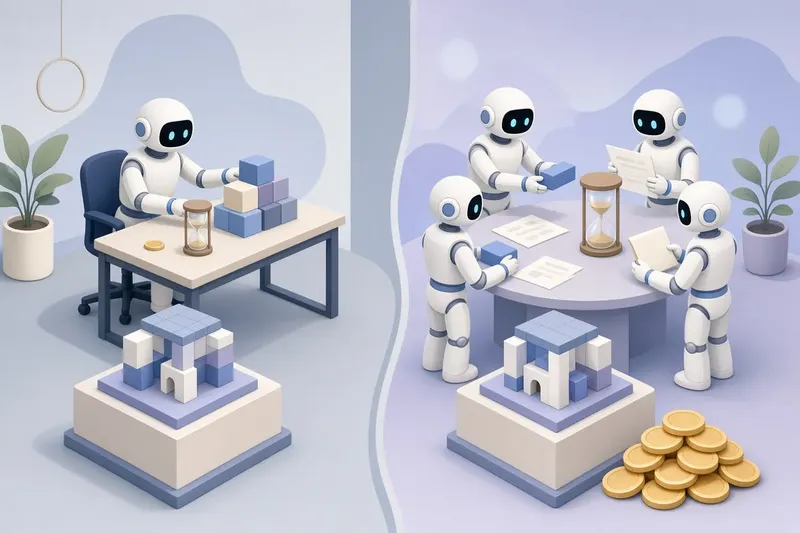
One Claude Model Beats Multi-Agent Teams on Cost and Speed in 82-Run Benchmark
Solo Opus 5.5 tied the viral four-agent team at 8.0 out of 10 on five large jobs. The team cost $47.14 and 176 minutes versus $10.57 and 45 minutes for Opus alone. Builder-tester loops drove most of the extra cost without raising scores. Only eight separate libraries favored a team: 3 minutes faster, nearly double cost. Best value: Sonnet 5.5 on high effort scored 12 of 12 on a data report for $0.68.
 AI News
Jagged AGI: Why Frontier Models Look Superhuman and Oddly Human at Once
Ethan Mollick calls Claude Fable 5.2 jagged AGI: expert-level yet unpredictable. Single prompts produced a short film, a 6-game keyboard console and a 3D world. Its errors now look human: a dense 182-page curriculum when asked for a course. Agents in a tiny town copied each other, so add independent checks to swarms. All five AI handover models assume perfect alignment, still an open question.
 AI Performance
Claude Fable 5.2 Benchmarks and Five Real Tasks: Where the Gains Show Up
Claude Fable 5.2 tops the Artificial Analysis index, six points above Opus 5.5. Standard pricing is $8 per million input tokens and $40 per million output tokens. On FrontierCode 2.0, high effort matches Opus 5.5 at max for about half the cost. In Claude Code it fixed a checkout price mismatch and built a working iPhone app. Four local agents at 40 tokens per second each will not fit under a €10,000 rig.
 AI in Practice
Claude Fable 5.2 Prompting: Set Effort to High, Demand Proof, Drop Old Rules
Set Fable 5.2 to high effort: 45.3% at $6.72 a task, half the cost of Opus 5.5 Max. Claude Code defaults to medium, which drops the score to 37.6%. Make it show test output before claiming completion and tell it to finish the job. Delete legacy CLAUDE.md micro-rules and forced subagent delegation instructions. Never ask for step-by-step internal reasoning; it triggers a safety refusal.
 AI News
Claude Fable 5.2 vs Opus 5.5: Benchmarks, Pricing, and Who Should Switch
Claude Fable 5.2 tops the Artificial Analysis Intelligence Index, scoring 82. API costs $8 per million input and $40 per million output tokens, twice Opus 5.5. Anthropic advises Opus 5.5 for daily work, Fable 5.2 as advisor or orchestrator. High reasoning matches Opus 5.5 at Max for less per task; Max can score lower. Web access needs a $17 Pro plan or higher; launch week adds up to 50% usage bonus.
Get new articles by RSS or podcast
Add the RSS URL to your RSS reader or the podcast URL to your podcast app to get every new article as soon as it is published. The podcast reads out the headline and key points.
How to subscribe