A controlled benchmark of 82 sealed test runs across nine coding and data jobs found that the widely shared "team" setup for Claude Code, in which Claude Fable 5.2 directs the work, Claude Opus 5.5 writes the code, Claude Sonnet 5.5 tests it and Claude Haiku 5.5 scouts the codebase, produced the same quality as a single Opus 5.5 session while costing 3.5 to 4.5 times more and taking up to six times longer. Only one of the nine tasks, a set of eight unrelated code libraries, favored a team, and even then the time saved came at nearly double the price.
Why the team idea took off
Shortly after Fable 5.2 launched, a wave of posts on X recommended that Claude Code users stop relying on one model and instead build a tiered crew: the most capable model as the planning lead, Opus 5.5 as the builder, and Sonnet 5.5 or Haiku 5.5 as testers and scouts. The pitch was that the expensive model would spend its tokens only on architectural reasoning, while cheaper sub-agents handled the mechanical work and test suites. The claim was better output and large token savings at the same time.
On paper the division of labor looks sensible. The benchmark set out to check whether it holds up when the bill arrives.
How the comparison was run
Every run was designed to be as isolated and as blind as possible:
- Each run started in a fresh Docker sandbox (a disposable, isolated container) with an empty Claude configuration, a randomized directory name and no git history.
- Every setup received the identical SPEC.md specification file and the same prompt text, and was told to work autonomously with Node 26, Python 3 and Playwright Chromium (a browser that can be driven by scripts without a visible window) installed.
- Functionality was checked by hidden verification suites the models never saw, including headless browser scripts and automated bots that played the games.
- Quality was scored blind by two separate AI judges, Opus 5.5 and Sonnet 5.5, which rated five aspects of each build from 1 to 10 without knowing which model or team had produced it.
- Fable 5.2 was also given an autonomous "lab loop" in which it invented and evaluated new agent architectures to see whether any could beat the leaders.
Round 1: a browser game and two small edits
The first task was a complete top-down arena survival game with three enemy types, wave scaling, an upgrade shop and high scores saved in local storage. Opus 5.5 running alone at its default medium effort setting (effort controls how much reasoning the model spends per response) was compared with the four-agent team over three runs each.
| Setup | Quality (out of 10) | Cost per run | Time per run |
|---|---|---|---|
| Opus 5.5 alone, medium effort | 7.2 | $1.64 | 10 minutes |
| Viral four-agent team | 7.1 | $5.75 | 61 minutes |
One team run was still going after 88 minutes and had to be stopped manually; the unfinished game failed six hidden checks.
Two follow-up tasks worked on an existing codebase: adding a pause menu and a boss fight, and fixing six vaguely described bugs. Here a solo Sonnet 5.5 was the comparison point.
| Task | Sonnet 5.5 alone | Viral team |
|---|---|---|
| Add pause menu and boss fight | 6 minutes, $0.77 | 31 minutes, $4.06 |
| Fix six reported bugs | 1 minute, $0.18 | 52 minutes, $2.61 |
Small jobs on an existing codebase appear to suffer the most from coordination overhead.
Round 2: five larger jobs
To answer the objection that the first round was too small for a team to shine, the second round used five substantial projects: a full-stack help-desk ticket application with a REST API, screens, tests and docs; eight independent JavaScript utility libraries (csv, cron, diff, expr, semver, lru, template and glob); a nine-page e-commerce site for a bicycle shop; a code-generated animated explainer video about compound interest; and a messy data-reporting job that parsed disorganized CSV exports into an executive report. A second team design, with Fable 5.2 as architect and four Opus 5.5 builders working at once, was added to the field.
Every model and every team passed all 25 hidden functional checks across the five jobs. Quality then split evenly, and cost and time did not.
| Setup | Average quality | Total cost, five jobs | Total time |
|---|---|---|---|
| Opus 5.5 alone | 8.0 | $10.57 | 45 minutes |
| Viral four-agent team | 8.0 | $47.14 | 176 minutes |
The explainer video was the sharpest example. Opus 5.5 alone produced it in 11 minutes for $1.81 and scored 7.8. The team spent 78 minutes and $21.73 and scored 7.6.
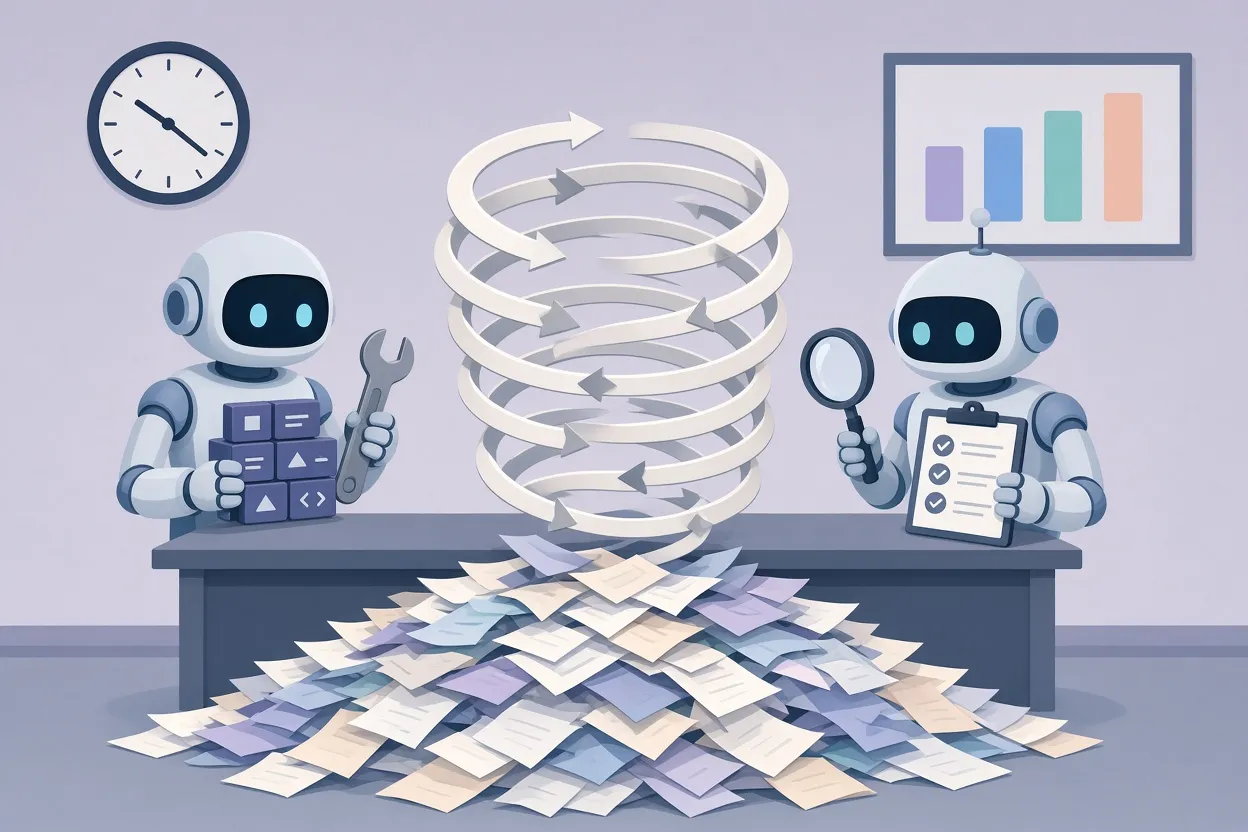
▲ Builder-tester loop that adds cost, not quality
Where the money went
Token accounting across the agents pointed to one main culprit: the loop between the Opus builder and the Sonnet tester. The tester kept flagging minor issues, the builder kept regenerating large blocks of code in response, and the cycle repeated for dozens of laps without moving the hidden-check results or the quality score.
The data suggests why the loop adds so little. Current models already check their own work as they generate it. In 21 solo runs at various effort levels, 19 passed all 67 hidden checks for the game with no tester agent involved. A dedicated tester therefore mostly pays to rediscover what the builder would have caught anyway.
A second structural limit also appears in the results. Because Fable 5.2 acted only as an overseer and never wrote code in the viral configuration, the final quality could not rise above what the Opus builder could produce on its own. A team organized this way inherits the builder's ceiling and adds the coordinator's cost.
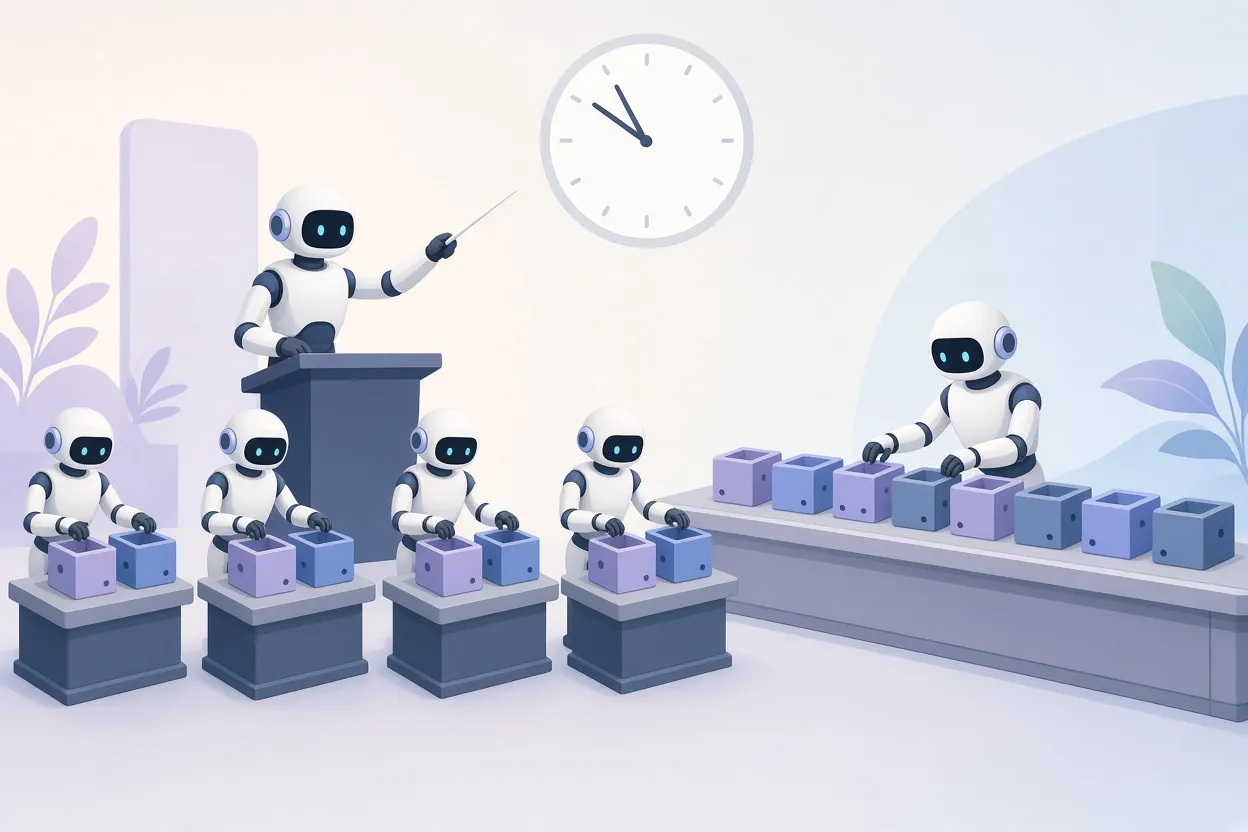
▲ Parallel builders on independent modules
The one task a team won
The eight-library job was the exception. The modules had no dependencies on one another, so Fable 5.2 split them into pairs and handed two to each of four Opus 5.5 builders running at the same time.
| Setup | Time | Cost | Quality |
|---|---|---|---|
| Parallel team, four Opus builders | 6 minutes | $4.01 | 8.5 |
| Opus 5.5 alone | 9 minutes | $2.27 | 8.6 |
Three minutes saved, at a cost premium of about 77 percent and no quality gain. When the same parallel team tackled the full-stack app by splitting backend, UI screens, tests and documentation, the advantage vanished. Fable spent roughly three minutes planning and another three stitching the pieces together, so the team needed 18 minutes and $8.30 against 12 minutes and $3.87 for a solo Opus building the app as one unit. Parallelism helps only when the parts truly do not touch.
Fable's own dream team
Before the main benchmark, Fable 5.2 was asked to design its ideal team for quality and token efficiency. It chose a five-model lineup: itself as lead, Sonnet 5.5 as builder, Opus 5.5 as reviewer, Sonnet 5.5 as tester and Haiku 5.5 as scout.
In practice it bypassed its own plan. Across every run, Fable wrote all of the implementation code itself, never called the tester or the scout, and invoked the Opus reviewer only once at the end. That review added about $1.00 and did not improve the game score, which came in at 7.0 against 7.3 for Fable working alone. In its own post-run analysis file, Fable concluded that its original team hypothesis had been wrong.
Standout values and the hardest problems
The benchmark also produced several findings about which single model fits which job.
- Sonnet 5.5 on high effort was the best value in the study. On the data-reporting task it answered 12 of 12 questions correctly for $0.68. It also handled the feature addition ($0.77) and the bug fixes ($0.18) quickly and cheaply, making it the natural choice for edits to existing code.
- Lowering Opus 5.5 to low effort to save money backfired: the game score fell by 1.6 points while the saving was only $1.05.
- On the most demanding algorithmic challenge, a 2D rigid-body physics engine with collisions and friction, Fable 5.2 alone scored highest at 8.2 for $10.21, edging out Opus 5.5 at 7.9 for $9.51.
- For hard engineering on a tight budget, a "budget team" of Opus 5.5 leading, Sonnet 5.5 building and Haiku 5.5 testing reached 7.4 on the physics engine for $3.00, less than a third of the solo Opus cost.
What the benchmark did not cover
The results come with limits. Quality was judged entirely by AI models, so visual polish, UI feel and generic-looking output were never graded by a person. Round 2 ran each of the five jobs once per setup rather than three times, because of the token expense, although the pattern matched Round 1. And every task finished in under an hour for a solo model. Multi-day or enterprise-scale work that spans several context windows was not tested, and team architectures may still earn their keep there.
How to choose a configuration
For ordinary software work, the measured answer is that one capable model is faster, cheaper and no worse than a team. A simple decision path follows from the numbers:
- Start new builds, websites and code-driven motion graphics with Opus 5.5 on medium effort, and do not drop it to low effort.
- Switch to Sonnet 5.5 on high effort for small edits, bug fixes and data analysis.
- Reserve Fable 5.2 alone for the hardest mathematical, physics or algorithmic problems, or use the Opus-Sonnet-Haiku budget team when such work must be done cheaply.
- Use parallel builders only when a job consists of strictly independent modules and finishing a few minutes sooner is worth roughly double the token bill.
- Avoid dedicated tester sub-agents in automated workflows; the models already self-check, and the loop tends to burn tokens without raising quality.
The broader lesson is to measure before adopting a workflow that sounds efficient. The team setup was logically appealing and widely endorsed, and it still lost on every axis except one narrow case.


