Five of the most-starred Claude Code plugins, Superpowers, ECC, Graphify, Caveman and claude-mem, hold 1,008,087 GitHub stars between them. In head-to-head tests against plain Claude Code, with the same tasks, hidden tests and blind grading, none of the five produced better results. Most runs took longer and cost more. On one job, a plugin run cost $5.12 against $0.91 for the plain run, and both passed the same tests.
What was compared
A plugin here means an add-on that loads extra instructions, skills, agents or tools into Claude Code. The five tested fall into four groups:
- Superpowers and ECC: workflow kits that impose planning, brainstorming and review steps
- Graphify: a tool that turns a codebase into a knowledge graph, a map of how files and functions relate
- Caveman: a token saver that makes Claude answer in terse, clipped language
- claude-mem: a memory layer meant to carry information across sessions
These are not neglected projects. Superpowers (318.1K stars) and ECC (303.8K) rank 14th and 15th among all GitHub repositories, above Linux at 255.8K. Together the five gained more than 80,000 stars in the previous month.
The test suite covered six kinds of work, plus a full website build:
- A small feature: adding a request-ID tag to every request and response in Starlette
- A security fix in HTTPX, where login tokens leaked to third parties during redirects
- A terminal inventory import app built with Textual
- 20 developer questions on debugging, design trade-offs and code review
- 12 architecture questions about an open-source project of more than 1,500 files
- A memory check: rules given on day one, asked for again in a third session on day three
- A full vacation cabin booking site in the style of Airbnb
The Sol 6.1 model graded the answers blind, and Sonnet 5.5 spot-checked every five questions.
Results by plugin
Superpowers
Superpowers describes itself as a full software development methodology that makes Claude plan like a senior engineer before writing code. On the three coding jobs, both setups scored 100 out of 100.
| Task | Plain Claude Code | Superpowers |
|---|---|---|
| Job 1, Starlette feature | $0.55, 4.0 min | $1.61, 11.5 min |
| Job 2, HTTPX fix | $0.32, 7.6 min | $0.37, 5.1 min |
| Job 3, Textual app | $0.91, 4.7 min | $2.33, 14.5 min |
| Cabin booking site | $2.84, 14 min | $5.15, 26 min |
Superpowers finished the second job faster, though it still cost more. That looks like an isolated case rather than a pattern. On the website build it cost 81% more, and the two finished sites were virtually identical in interface and user flow.
ECC
ECC presents itself as an operating system for coding agents and advertises 72 agents, 327 skills and 98 legacy command shims. That volume has a price before any work starts. Plain Claude Code used 23.8k tokens of context at startup. Tokens are the units of text a model reads and writes, and they drive the bill. With ECC installed, startup context rose to 52.8k tokens, about 29,000 extra before a single prompt.
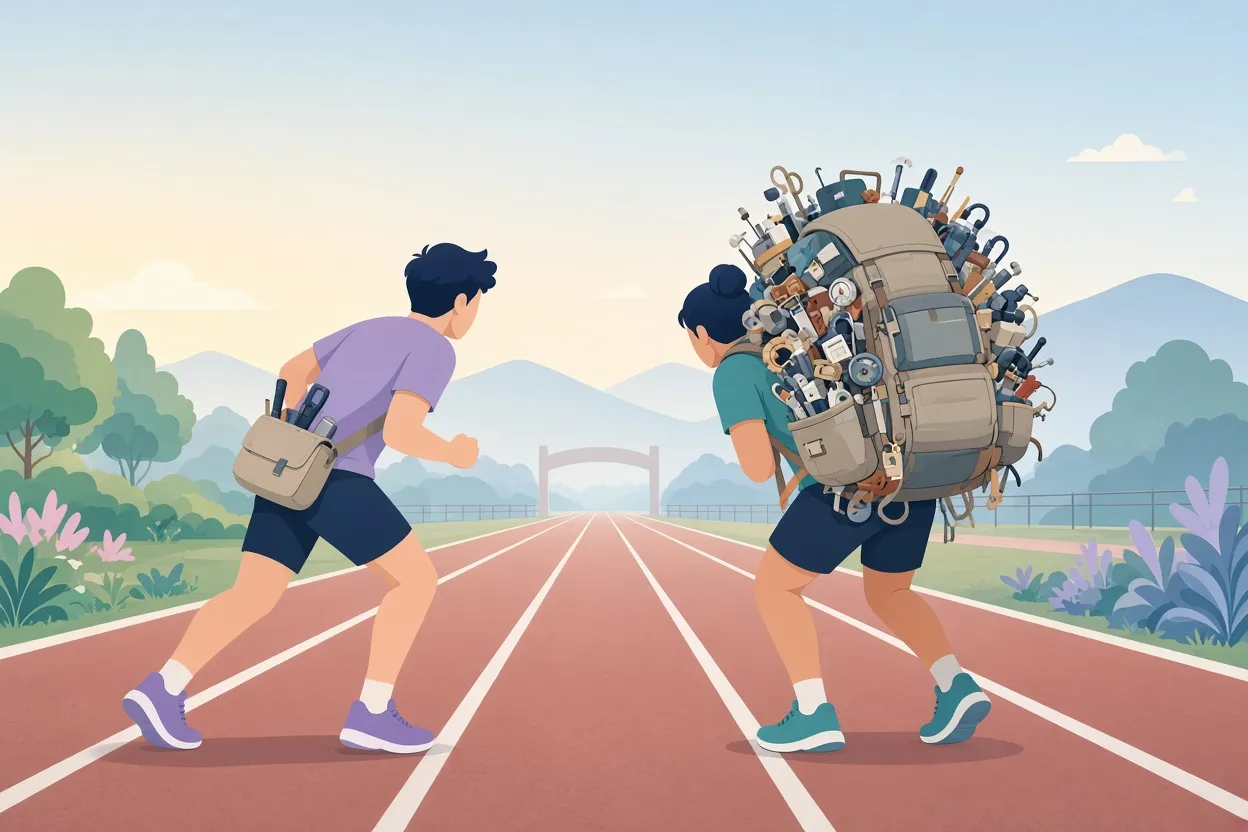
▲ Startup context load with and without a heavy kit
| Task | Plain Claude Code | ECC |
|---|---|---|
| Job 1 | $0.55, 4.0 min | $2.93, 13.7 min |
| Job 2 | $0.55, 4.1 min | $1.22, 6.5 min |
| Job 3 | $0.91, 4.7 min | $5.12, 28.7 min |
Each row pairs the plugin with the baseline it was measured against; the plain figures reported for the second job differ between the Superpowers and ECC comparisons. On the third job, plain Claude Code, Superpowers and ECC all passed the same 89 hidden unit tests. The ECC website build came in at $8.66 and 39 minutes, against $2.84 and 14 minutes for the plain run.
Caveman
Caveman's documentation claims 33.2% fewer input tokens, runs that are 54% cheaper at identical scores, and overall cost reductions of 1.4x to 2.4x. The test compared three setups on the 20 developer questions: plain Claude Code, Claude Code with Caveman, and plain Claude Code with one sentence added to CLAUDE.md, the project instruction file Claude Code reads at startup. The sentence was "Answer concisely."
| Setup | Cost per answer | Quality score |
|---|---|---|
| Plain Claude Code | $0.152 | 94.3 |
| Caveman | $0.162 | 94.1 |
| "Answer concisely" in CLAUDE.md | $0.117 | 93.1 |
Caveman was the most expensive of the three, 8% above plain. It cut the word count of answers by about 5%, but the tokens spent loading its behavior rules outweighed that saving. The one-line instruction cut cost by 23% with no plugin at all.
Graphify
Graphify claims to cut agent token spending by 80% by replacing brute-force text search with its knowledge graph. On the 1,500-file repository, with 12 questions and two coding tasks run twice, the numbers moved the other way.
| Metric | Plain Claude Code | Graphify |
|---|---|---|
| Tokens read per question | 258k | 288k (+12%) |
| Answer score | 93.0 | 89.1 |
| Cost per session | $4.62 | $5.74 (+24%) |
| Session duration | 12.7 min | 16.5 min (+30%) |
claude-mem
claude-mem is promoted as a cure for session amnesia. In three scenarios spread over three sessions, plain Claude Code and claude-mem both scored 1.00 on recall, remembering every rule set on day one. Session cost was $5.50 plain and $5.54 with the plugin. Claude Code's built-in background worker and automatic session notes appear to cover the same ground.
Why extra structure stopped paying off
The likely explanation for these results is model progress. These plugins took shape when workflows ran on models such as Sonnet 3.5 and Opus 4, which benefited from rigid rules, forced planning and pre-built maps of a codebase. Current models such as Opus 4.6, Opus 5.5 and Fable 5.2 reason through those steps on their own. Forced brainstorming rounds and confirmation questions then become repeated work, and every loaded rule occupies context and costs tokens. In the Graphify test, plain text search (grep) was both faster and more accurate than the graph.
Anthropic engineers have given similar advice: delete complex skills and aggressive CLAUDE.md instructions, and keep scaffolding minimal and clean.
This does not make the plugins bad work. Their authors built useful tools for the limits of earlier models; the models changed faster than the add-ons did. Star counts appear to record that earlier usefulness and current attention more than current performance. Because the plugins are open source, a developer can also edit one directly and strip the instructions that current models no longer need.
How to decide what to keep
The tests suggest a simple rule of thumb: a plugin earns its place when it gives Claude a capability it does not have, not when it promises to make Claude better at coding in general. Plain Claude Code is the better choice when:
- The plugin restates planning, review or memory behavior the model already performs
- Its instructions load thousands of tokens at startup regardless of the task
- Its benefit rests on published claims or popularity that you have not checked against your own work
Three steps put this into practice:
- Audit. Run the built-in /doctor command, or ask Claude in plain language to list every skill and plugin, flag those unused in the last 90 days and remove them.
- Be selective. Keep only tools that add a distinct capability Claude lacks.
- Test before adopting. Run the same task with and without the plugin and use the /cost command to compare token spend and time, then compare output quality.
▲ Pruning a setup to the tools that earn their place
The bottom line
In this set of tests, zero of five popular plugins beat plain Claude Code on quality, and the heavier kits multiplied cost and time: up to roughly five times the cost on one job, with identical test results. A single line in CLAUDE.md saved more than a dedicated token-saving plugin. These figures come from one test suite, so they are a reason to measure rather than a universal verdict. Audit your setup, drop what the model now does on its own, and benchmark any add-on against a plain run on your own tasks before trusting it.