There are two main ways to make an AI agent (software that carries out tasks on a person's behalf) perform better: change what goes into the model's context, or retrain the model's weights. The research reviewed here points to a practical split. Prompt and context optimization can converge within hundreds of trial runs, known as rollouts, and works on closed, API-only models. Weight training is data-hungry, but it scales when thousands of examples are available and can move a capability into a smaller, cheaper model. Neither route works without an evaluation to optimize against.
Why guessing the best prompt fails
Consider three endings appended to a math problem and tested on a Google PaLM 2 model with the GSM8K math benchmark. Most people cannot pick the winner in advance.
| Prompt suffix | Accuracy |
|---|---|
| "Let's think step by step." | 71.8% |
| "Take a deep breath and work on this problem step-by-step." | 80.2% |
| "Let's combine our numerical command and clear thinking to quickly and accurately decipher the answer." | 74.5% |
The winning phrase was not written by a person. It came from OPRO, a Google DeepMind method in which a language model acts as the optimizer: it reads earlier instructions together with their scores and proposes a new instruction meant to score higher. One explanation offered for why such phrasing works is that model-written prompts sit closer to the text the model saw in training than human-written ones do.
The lesson is that prompt quality is model-specific and counterintuitive. It has to be measured.
The three things optimization requires
Optimization here means specifying intent through data and evaluation metrics, then letting an algorithm improve the system. It needs three pieces at the same time:
- Data: training sets, recorded task attempts, demonstrations, human feedback.
- A system or model: a language model, a multi-step workflow, or an agent.
- An evaluation and metric: exact match, pass rate, a model acting as judge, or cost and latency.
Larger general-purpose models do not remove the need. They are trained for broad capability, while real applications face a last-mile problem: adapting to a specialized workflow. A calendar tool that turns emails into entries shows the gap. The prompt says "extract the date and time," but the real intent includes multiple events in one email, time zone formatting and ISO-compliant output. An evaluation set captures those requirements better than prose instructions do. Hand-tuning prompt wording may matter less as models improve, but defining evaluations appears to be a lasting discipline.
Optimization is worth starting when you have domain data and an evaluation suite, and when the behavior you want is hard to state in one static prompt. The benefits include reliability, domain adaptation, lower cost and latency from smaller models, and easier upgrades: when a new model generation arrives, rerun the optimizer against the same evaluation set.
Optimizing the context
Context optimization leaves the model's weights frozen. It comes in two broad families.
Few-shot examples
Few-shot prompting adds worked input-output examples to the task description. A 2022 paper showed that models are highly sensitive to the order of those examples, and that good orderings can be found without labels. The method checks whether the model's predictions on an unlabeled probing set stay balanced rather than collapsing into one answer, a measure called global entropy. It sometimes improved accuracy by more than 8% over random ordering.
When examples lack step-by-step reasoning, bootstrapping fills the gap. The system runs the model on training questions and keeps the reasoning traces that reach the correct answer. STaR fine-tunes the model on those traces; when an answer is wrong, it gives the model the correct answer as a hint and has it reason back to that answer. The DSPy framework instead places them in the prompt and searches for the best combination on a development set, with results on GSM8K that often surpass human-written reasoning examples.
Instructions and reflection
MIPROv2 optimizes instructions and examples together in three steps:
- Bootstrap demonstrations by keeping only successful runs.
- Propose instructions grounded in a summary of the program's code and its training data.
- Search combinations with a Bayesian model that updates its beliefs on small batches, with periodic full evaluations to rule out noise.
On an iris flower classification task, the optimizer replaced a plain instruction with a dramatic one about saving a rare species from extinction. Framing like that feels dated for modern models, but it shows how unintuitive winning prompts can be. One caveat: MIPROv2 does not check whether the reasoning is sound unless the metric does, so a judge model can be added to the metric to guard against shortcuts that game the score.
TextGrad takes a different route. A model writes natural-language criticism of an output, and that feedback passes backward through each component of a pipeline. Despite the name, no calculus is involved. On one reasoning task, accuracy rose from 77.8% to 91.9%.
GEPA, short for Genetic Pareto Prompt Evolution, keeps a pool of prompt candidates scored across many tasks. It retains only candidates that no other candidate dominates (the Pareto frontier): a prompt that solves only a subset of the tasks another prompt solves is dropped. It then creates new candidates either by having a model reflect on failures and rewrite the prompt, or by merging the best modules from different candidates in a multi-step pipeline.
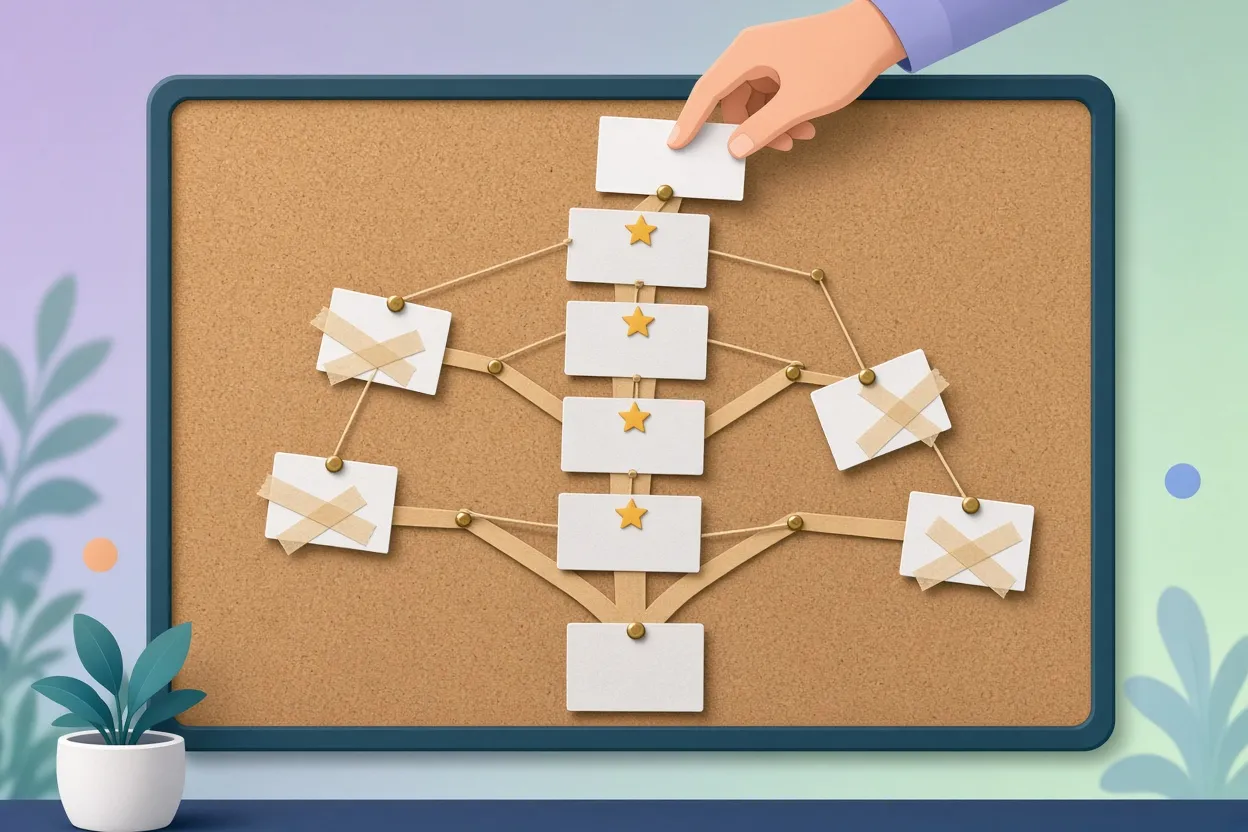
▲ Evolutionary search over prompt candidates
In PAPILLON, a pipeline that strips sensitive details from a query with a local model before calling an external model, GEPA lifted the score from an 82.26 baseline to 97.83. The gains came in stages: broader privacy strategies (87.76), structured output (94.44), transparent rationale (94.67), then an exhaustive protocol. Across six benchmarks, GEPA improved aggregate performance by 12.19 points over a GPT-4.1 mini baseline, and 13.33 points with merging.
Optimizing the weights
Supervised fine-tuning
Fine-tuning means training an already trained model further for a specific job. For agents, a capable teacher model completes tasks, and a student model trains on the successful runs. This is a form of distillation, and although simple, it remains one of the most widely used methods.
Two findings stand out. First, the strongest teacher is not always the best. A student often learns better from a teacher closer to its own capacity than from a far more capable model. Second, data volume matters: OpenThoughts-Agent results on SWE-bench Verified and Terminal-Bench 2.0 improve steadily as the dataset grows from 316 to 100,000 samples. In FireAct, a 13-billion-parameter Llama 2 model fine-tuned on GPT-4 runs reached 34.4%, ahead of prompted GPT-3.5 at 31.4%.
Reinforcement learning with GRPO
In reinforcement learning (RL), the model attempts tasks itself and receives rewards. Rewards need to be verifiable, ideally through unit tests or sandbox results, with a judge model only as a fallback.
The older standard, Proximal Policy Optimization (PPO), keeps four full models in memory and trains two of them, including a value model that estimates each token's contribution. Group Relative Policy Optimization (GRPO), introduced in the DeepSeekMath paper and used for DeepSeek-R1, drops the value model. It samples a group of answers for each prompt and scores each one by how far its reward sits above or below the group average, divided by the group's spread. That leaves three models in memory and one to train. On the MATH benchmark over 2,400 training steps, GRPO reached about 55.5%, compared with 50% to 53.5% for PPO variants.
The suggested division of labor: supervised fine-tuning first, to establish format and basic reasoning; RL once the model clears a minimum capability bar. RL becomes necessary when no teacher exists, as with a frontier model working on problems nobody has solved. If RL performs worse than supervised fine-tuning, stay with fine-tuning.
On-policy distillation
On-policy distillation combines both ideas. The student generates its own attempt, and a teacher model with open weights scores every token. Take "What is 5 + (2 * 3)?". Plain fine-tuning never shows the student how to recover from its own mistakes. Plain RL returns a zero with no hint of where the attempt went wrong. On-policy distillation flags the exact step where the student adds 5 and 2 first.
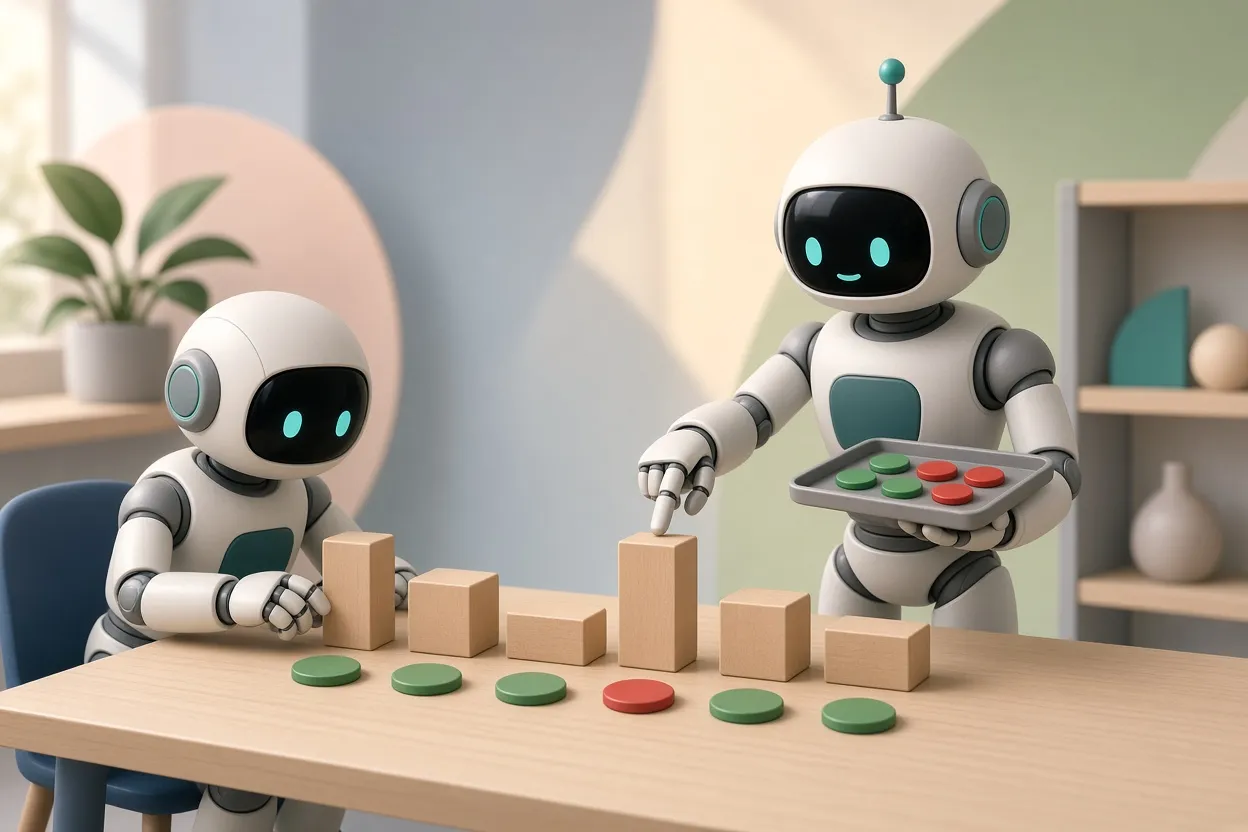
▲ Step-by-step feedback from a teacher model
Figures from the Qwen3 model series show the efficiency:
| Method | AIME'24 | GPQA-Diamond | GPU hours |
|---|---|---|---|
| Off-policy distillation | 55.0% | 55.6% | not stated |
| Reinforcement learning | 67.6% | 61.3% | 17,920 |
| On-policy distillation | 74.4% | 63.3% | 1,800 |
Agents that optimize agents
A third route hands the optimization to an agent. The Darwin Gödel Machine rewrites its own scaffolding, the harness code that wraps the model and runs its steps, and keeps an archive of earlier versions to explore. Meta-Harness reads full execution logs and writes better harness code, reaching a 37.6% pass rate on Terminal-Bench 2.0, against 27.5% for a Claude Code baseline. In Andrej Karpathy's autoresearch approach, an agent edits a training script, runs it, keeps the change if the metric improves and reverts it if not. One nanochat run completed 83 experiments and kept 15 changes.
Because agents optimize whatever they are measured on, the quality and integrity of the evaluation becomes the main bottleneck.
Choosing between the two
| Choose context optimization when | Choose weight optimization when |
|---|---|
| The model is closed and reachable only through an API | A smaller model fails to follow instructions |
| You need fast, lightweight runs, even daily | You want to distill a capable teacher into a cheaper student |
| Each interaction with the environment is expensive | Prompts have accumulated into context bloat |
| You have hundreds of rollouts, not thousands | You have thousands of training examples |
The two can also be combined. BetterTogether alternates prompt optimization and fine-tuning and reports better results than either alone.
What to do next
- Build the evaluation first. Without data, a working system and a metric, there is nothing to optimize.
- Do not trust intuition about prompt wording. Test variants against your benchmark, and run multiple trials when using a commercial API.
- With a closed model or limited data, start with a prompt optimizer such as GEPA or MIPROv2. In GEPA's reported results, hundreds of rollouts were enough to converge.
- Move to weight training when you have thousands of examples, need a smaller model, or prompts have grown too long. Begin with supervised fine-tuning, pick a teacher close to the student, and add RL only where it beats fine-tuning or no teacher exists.
- If the teacher's weights are open, consider on-policy distillation before pure RL. In the Qwen3 case it scored higher at roughly one-tenth of the compute.
- Keep the evaluation set stable so you can rerun optimization whenever the underlying model changes.