Anthropic has added an experimental feature called Code Mode to Claude Code that changes how the coding agent uses its tools. Instead of calling tools one at a time and reading every result, Claude writes JavaScript that calls several tools in one step, processes the results in code, and hands only the filtered output back to the model. In one eight-run test, the same model used 53% of its normal input tokens, the units of text a model reads and is billed for, and ran at about 71% of its normal cost. The feature is off by default, and Anthropic notes that its syntax and default behavior may change.
Why one-at-a-time tool calls get expensive
A harness is the software around a model that connects it to tools and an execution environment. A traditional harness runs a loop: the model reads a file, edits it, runs a bash command, fetches a web page, and repeats until it decides the job is done. Each result goes into the context window, the working memory the model reads on every turn.
That loop works well for simple jobs. It gets inefficient on complex, multi-step work, especially when the agent connects to many tools or to MCP servers that each expose dozens of functions. MCP, the Model Context Protocol, is a standard way to connect a model to outside services.
Consider an agent that pulls records from Stripe, then metrics from Cloudflare, then passes both to a third tool. Each intermediate payload lands in the context window, and the model rereads the whole growing transcript on every later turn. Prompt caching, which bills repeated input at 10% of the standard rate, softens the cost. Even so, large raw payloads still add spending that serves no purpose, and they degrade the quality of the model's reasoning.
The alternative is to let the model write logic that routes one tool's output straight into the next tool's input, so intermediate data never enters the context window. The model stops acting as a turn-by-turn router and starts acting as a programmer that orchestrates tools.
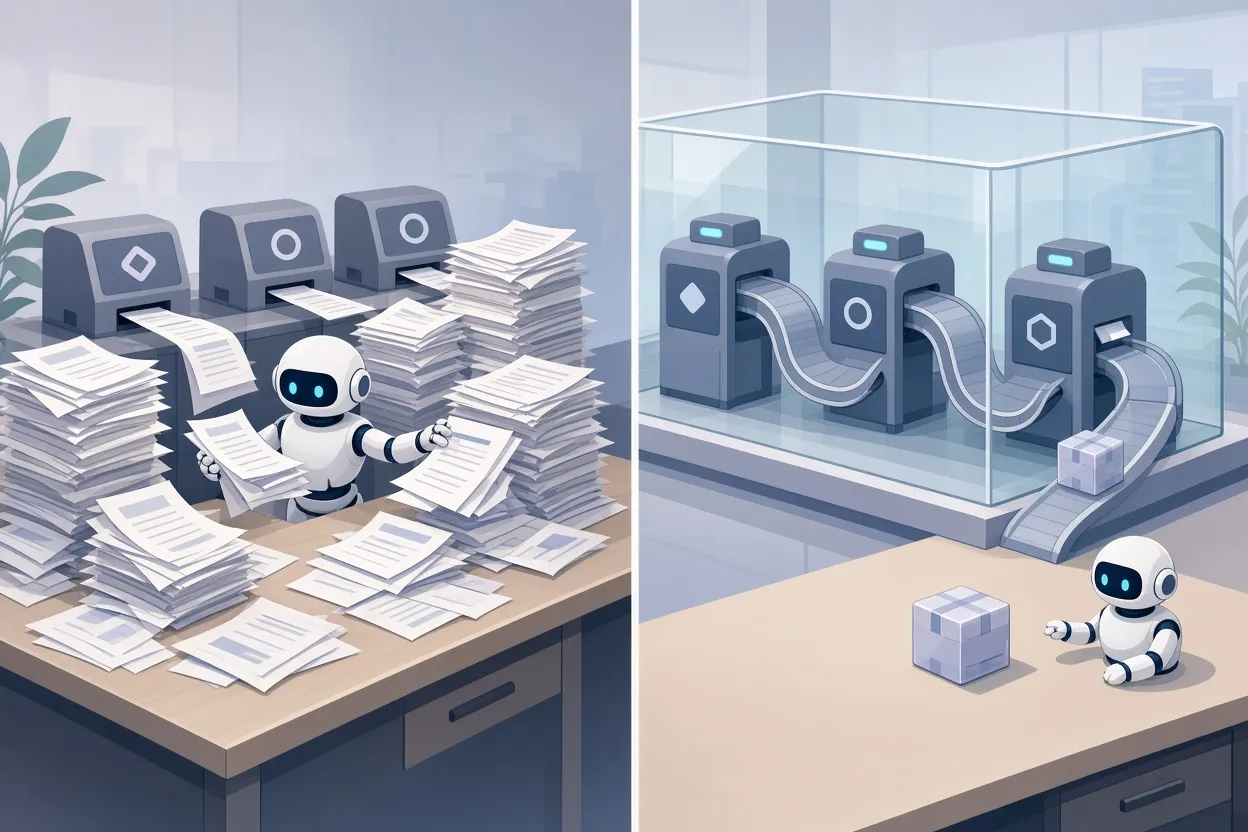
▲ Raw tool output versus filtered results
From single MCP servers to the whole harness
The idea is more than a year old. Cloudflare popularized it in a post arguing that developers had been using MCP inefficiently by exposing huge tool schemas directly to the model. Its own API covers about 2,600 tools. Rather than load all of those definitions, Cloudflare reduced its interface to two tools: search, which lets Claude look up the endpoints it needs, and execute, which runs TypeScript that Claude composes inside a secure server-side sandbox.
| Approach | Tools exposed | Tokens for tool definitions |
|---|---|---|
| Full schemas | About 2,600 | 1,170,523 |
| search and execute | 2 | 1,069 |
That is a 99.8% reduction. Datadog adopted a similar pattern, replacing many specialized MCP endpoints with code execution tools that run queries in a sandbox.
Server-side code mode has a limit: it only fixes tool bloat inside one provider's MCP server. Chaining Stripe, PostHog and Supabase in a single script needs an execution layer on the client side. Before Claude Code offered one, developers used MCP gateways such as Executor.sh, which presents itself as one MCP server with unified search and execute tools and runs scripts against every connected API in one runtime. One self-hosted Executor.sh instance, for example, manages 33 MCP integrations grouped into permission packages for support, engineering and finance teams.
Code Mode extends the pattern past MCP to Claude Code's own tools: file read, file write, edit and bash. Variants of the approach also appear in Codex, OpenCode, Pi and Prime Agent. It fits a broader pattern, sometimes summed up as "the model swallows the harness," in which the model takes over work that external harness code used to do.
How Code Mode works inside Claude Code
With Code Mode on, Claude Code operates through two tools, repl and poll.
A JavaScript session that keeps its state
REPL stands for read-evaluate-print loop. Here it is a JavaScript console that stays active for the entire Claude Code session. Bash commands, file reads, edits, web fetches and MCP functions all appear inside it as callable JavaScript functions.
Because the process keeps running, a variable defined in one call is still in memory for the next. Claude can store a dataset once, then filter or transform it later without downloading or parsing it again. Server-side environments such as Cloudflare Workers or Executor.sh discard state between calls, so they cannot reuse variables this way.
Filtering before the model reads anything
Inside a single script, Claude can loop over hundreds of files, run calls in parallel with Promise.all, total rows with reduce, remove duplicates with Set, and filter rows. All of that happens before any result returns to the context window, which saves context space and removes extra round trips to the model.
This also helps with poorly designed MCP servers that return far too much data. Claude can assign the bulky output to a variable, preview a few items, and then run targeted code against the rest.
A bash script cannot do the same job, because bash has no direct access to harness-level tools, subagents (helper agents the main agent starts for a subtask) or MCP servers. Code Mode gives code control over all three.
Long jobs in the background
The poll tool handles scripts that run long loops. Those scripts detach and continue in the background while Claude checks periodically whether they have finished.
An example
Suppose the request is to combine Stripe data with PostHog data and produce an HTML file showing the customers with the highest lifetime value and where they came from. In Code Mode, Claude writes one asynchronous script with a loop that pages through Stripe charges, joins them against PostHog analytics, and writes the HTML dashboard. The raw customer and charge objects never enter the conversation.
What the measurements show
An automated agent that tracks Claude Code releases documented a test in which a Claude Sonnet model worked on real open-source issues with and without Code Mode on Claude Code 2.1.318, the release where the feature appeared. Across eight paired runs:
| Measure | Code Mode as a share of normal mode |
|---|---|
| Input tokens | 53% |
| Output tokens | 61% |
| Total cost | About 71% |
Two outside projects point in the same direction.
- Browser Use 1.0.0 deleted 90% of its predefined state and action library and replaced it with a Python REPL that drives the raw Chrome DevTools Protocol. The project reported up to 50% better benchmark performance, 2x to 5x lower cost and 2x to 3x faster runs than rigid schema-based agents.
- A project called Unharnessed gave Opus 5.5 a simple Python REPL on Terminal-Bench 4.0 and reached 71.2% accuracy at $12.19 per task. Claude Code scored 64.85% at $14.30 per task.
Three MIT researchers offer a frame for these results in an essay titled "The Mismanaged Geniuses Hypothesis." They argue that current frontier models are already capable enough but are held back by rigid harnesses, and that software needs to learn to manage those models through flexible task decomposition rather than only waiting for the next generation. Code Mode appears to apply that principle: it gives the model room to move data and run workflows without filling its context early.
Where this may be heading
Claude Code 2.1.318 also contains three hidden, unreleased functions: spawnContext, listContexts and releaseContext. They suggest subagents are being restructured as isolated contexts that code can start, combine and end. Because they are unreleased, they may change.
One use is forking. Asked to make code faster, Claude Code could fork its conversation five to ten times, try a different optimization strategy in each fork in parallel, and return only the top three results to the main conversation. Subagents started this way keep a two-way channel with the coordinating agent, unlike rigid workflows in which child processes cannot talk back.
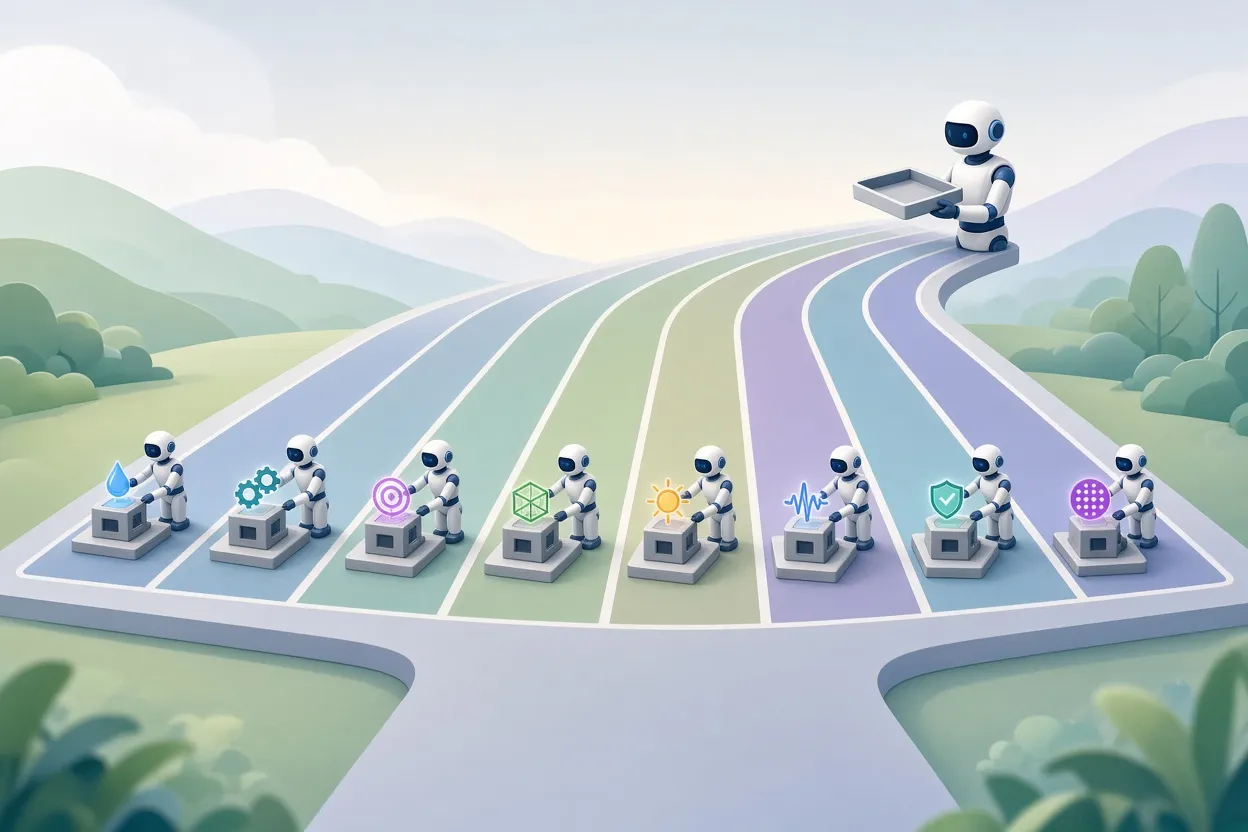
▲ Parallel context forks with top results kept
This lines up with research on Recursive Language Models, or RLMs, from MIT CSAIL. An RLM needs three things: a REPL that persists across calls, the ability to dispatch subagents from inside that REPL, and a prompt treated as an external variable rather than as raw context.
The third piece changes how large inputs work. Pasting a 2-million-token input normally saturates the context window. An RLM stores that input in a variable, and the model writes code to slice it and hand portions to subagents, for example splitting a codebase across 20 of them.
The same idea can apply to conversation history. A model could replace verbose tool transcripts with short summaries or cut irrelevant logs. Current compaction methods are imperfect and can lose important nuance, so slicing history with code may be the better option. There is a cost catch: editing earlier messages can invalidate the prompt cache. A Meta research paper on Context Language Models examines prefix and suffix caching to avoid that breakage. Anthropic's API offers context editing that prunes tool results and thinking blocks, but if the tokens saved are smaller than the penalty for breaking the cache, total cost can go up.
As a forecast rather than a confirmed plan, possible 2027 models such as Opus 6 or Opus 7 may be post-trained directly on REPL-driven context and subagent management. RLMs will likely reach their full potential only with that kind of training.
How to turn it on
- Start Claude Code with the environment variable set:
CLAUDE_CODE_EXPERIMENTAL_CODE_MODE=1 claude. The variable can also go in settings.json. - If Claude Code reports that Code Mode is unavailable because of an installed mod, disable any hook or mod that checks individual tool calls, such as one that redacts transcripts, and restart the session. These hooks conflict because individual tool calls no longer emit the usual harness events.
- Ask Claude which tools it has. It should list repl and poll.
- Press Ctrl+O to expand the log and read the JavaScript Claude wrote and ran.
Key points and next steps
Code Mode moves tool orchestration out of the conversation and into code. The context window gets filtered results, and in one Claude Code test the same model used about half the input tokens at roughly 71% of the cost. That figure comes from eight paired runs, so treat it as an early signal, not a guarantee.
Whether to enable it now depends on the work. It looks most useful for jobs that chain several tools or MCP servers and return large payloads, where intermediate data would otherwise pile up in context. It is a weaker fit, for now, for setups that depend on hooks inspecting each tool call, since those must be disabled until they are updated.
For those who try it:
- Let Claude keep intermediate datasets in variables instead of fetching them again.
- Have it wrap multi-step data work in one script rather than many separate calls.
- For verbose MCP servers, have it capture output in a variable and preview a small slice first.
- Use background polling for loops over large datasets so long runs do not time out.
- Inspect the generated code with Ctrl+O, and expect the feature's behavior to change while it remains experimental.