Most companies now build agents on the same handful of foundation models and the same kinds of enterprise data, so neither the model nor the raw data creates a lasting advantage. An Oracle engineer argues that the advantage has moved to a different layer: the intelligence plane, which determines what an agent knows, what it remembers, what it is allowed to see, and how it gets better over time. The argument comes with a reference architecture, a benchmark comparison in which a governed agent reached 97% accuracy against 33% for a naive one, and four concrete steps teams can take today.
The layers most teams already have
Two concepts have become common in agent engineering over the past couple of years, and the intelligence plane builds on both.
The first is agent memory: the mechanism an agent uses to retain, reuse, refine and recall information across conversation turns, sessions and agents. A compact way to remember this is "the 4 Rs." The taxonomy splits into short-term memory, which lives within a single session (the working context window plus a semantic cache for repeated queries), and long-term memory, which persists across sessions. Long-term memory borrows terms from cognitive science: semantic memory for facts and knowledge (entity memory, knowledge bases, persona memory), episodic memory for past events (conversation histories and summaries), and procedural memory for how to act (toolboxes and workflow definitions).
The second is the control plane: a centralized governance layer that decides what agents may do. It validates agent identity, manages which calls are allowed, monitors compute and financial spend, holds policies and guardrails, offers lifecycle management with kill switches, and records audit logs. The name comes from networking, where the control plane decides where traffic goes while the data plane moves the packets. In an enterprise, research agents, trading assistants and ops agents all route through this layer on their way to external tools such as APIs and MCP servers (Model Context Protocol, a standard for connecting agents to tools), to large and small language models, and to enterprise tables and documents.
A related idea is the software factory: a production line in which agents plan, build and test software, each owning a task with its own tools, memory and validation checks, while human engineers set the work queue and sign off at a review gate before anything reaches production. The term dates to 1968, when Bob Bemer at General Electric proposed turning programming into a measurable, repeatable manufacturing process. The argument here is that multi-agent automation finally makes that vision practical.
All of this answers one question: is the agent allowed to act? None of it answers a different question: does the agent actually understand the business?
A lesson from 1942: same messages, different conclusions
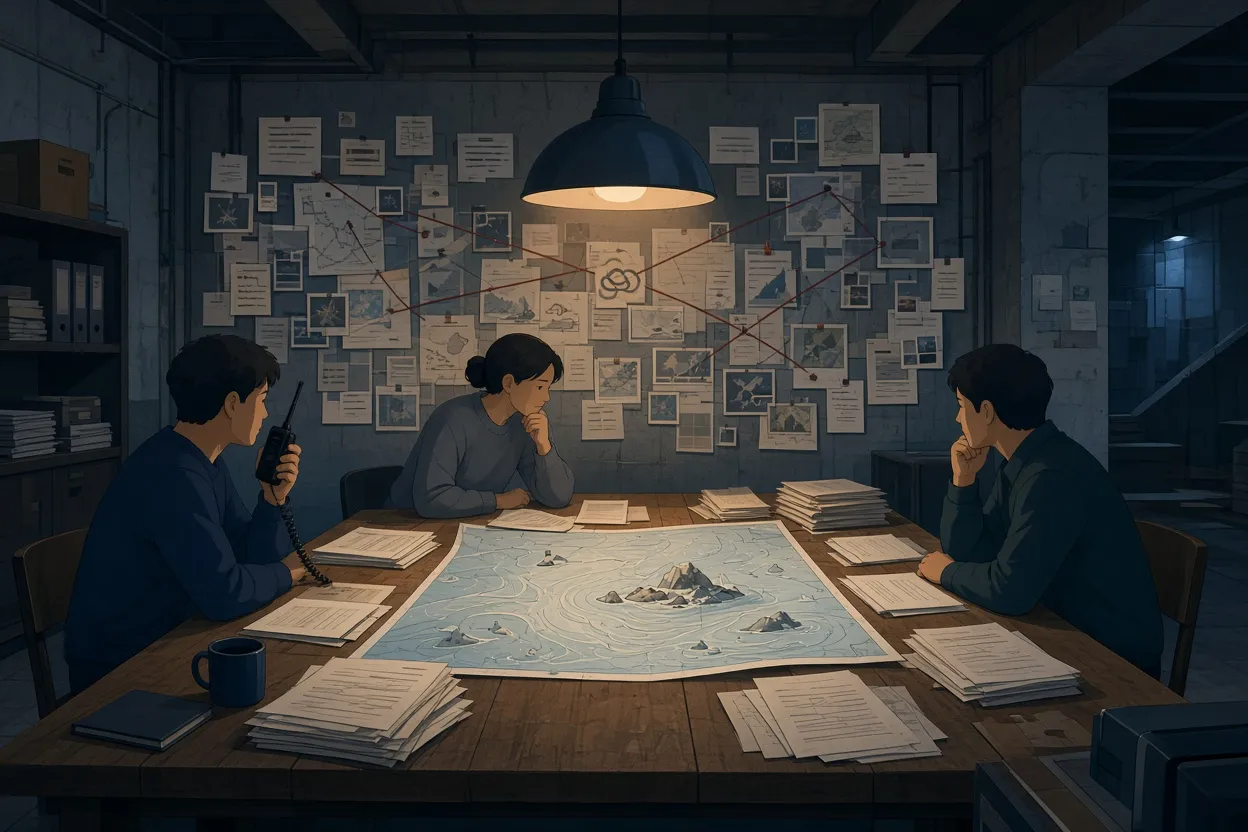
▲ Accumulated context behind the Midway deduction
To separate control from intelligence, consider an example from naval history. In May 1942, American cryptanalysts intercepted Imperial Japanese Navy communications and tried to determine the next major target. Two teams examined the same intercepted messages: OP-20-G in Washington, D.C., and Station HYPO in Pearl Harbor.
Station HYPO worked out of a basement, where analysts had spent months compiling fragmented, handwritten message logs on paper. That accumulated context let them connect the recurring designator "AF" to Midway Island. To confirm it, they had Midway personnel send an unencrypted radio message reporting a broken water distillation plant. Soon afterward, an intercepted Japanese dispatch reported that "AF" was short of fresh water. Station HYPO predicted an assault on Midway for June 4, and Admiral Nimitz positioned the US carriers accordingly. Washington, working with a more centralized, bureaucratic process, concluded that the target lay elsewhere in the South Pacific, the Aleutians or the US West Coast in mid-June.
The parallel to AI is direct. Both teams had the same inputs. The difference was how one team structured, retained and tested its institutional knowledge over time. Having access to the same models and the same data does not make an organization intelligent; raw information is not intelligence.
What the intelligence plane adds
Picture the agent stack as nine layers: infrastructure, memory core, security and governance, tooling, memory managers, reasoning, orchestration, gateway and application. The control plane cuts horizontally across the governance, orchestration and tooling layers. The intelligence plane cuts vertically through all nine, and it governs four things:
- Knowledge: domain semantics, such as the rule in banking that a "counterparty" includes both the parent and its legal subsidiary entities.
- Memory: historical interactions, such as a correction an analyst made last week, so the same mistake does not recur.
- Governed access: data boundaries, such as an analyst on Desk A being able to see Desk A positions but never Desk B.
- Continual learning: refinement of components such as retrieval rerankers based on governed human feedback.
At the gateway layer, the intelligence plane links the end user's identity to data permissions; at the orchestration layer, it turns into governed context assembly. The thesis is summarized in three equations: an agent is a model plus a harness; control is governance plus security; and intelligence equals control multiplied by knowledge, memory and learning. Zero control makes an enterprise deployment unviable, but control without intelligence yields an agent that is secure and completely ignorant of company-specific business logic.
The idea is not claimed to be entirely new. In 2003, Clark, Partridge, Ramming and Wroclawski proposed a Knowledge Plane for the Internet at SIGCOMM, separate from the management, control and data planes, and a 2017 ACM SIGCOMM CCR paper extended it as Knowledge-Defined Networking. Agent development, in this framing, has moved through four phases: prompt engineering in 2023, retrieval and context engineering in 2024, control planes and governance in 2025, and now agents that know, remember and learn.
Learned decisions at every pipeline step
A second shift makes the intelligence plane practical. Open-weight models now trail frontier models by only three to six months, and a new class of machine-native decision models is built for structured system-level execution rather than text generation. One example cited, a decision model called Jev, returns typed decisions in 70 to 100 milliseconds, described as 20 to 100 times faster than general-purpose frontier models.
Legacy retrieval pipelines used learned models in only two of ten steps, with static rules handling routing, input validation, caching and guardrails. Modern pipelines can use learned models in all ten: a router model, an input guard classifier, a semantic cache validator, an embedder and reranker, a query planner, a reasoning LLM, a decision model, a memory manager, an output-check judge and in-database inference. Every module then understands enterprise context and enforces the same identity and permission semantics.
Governed versus naive: one benchmark run
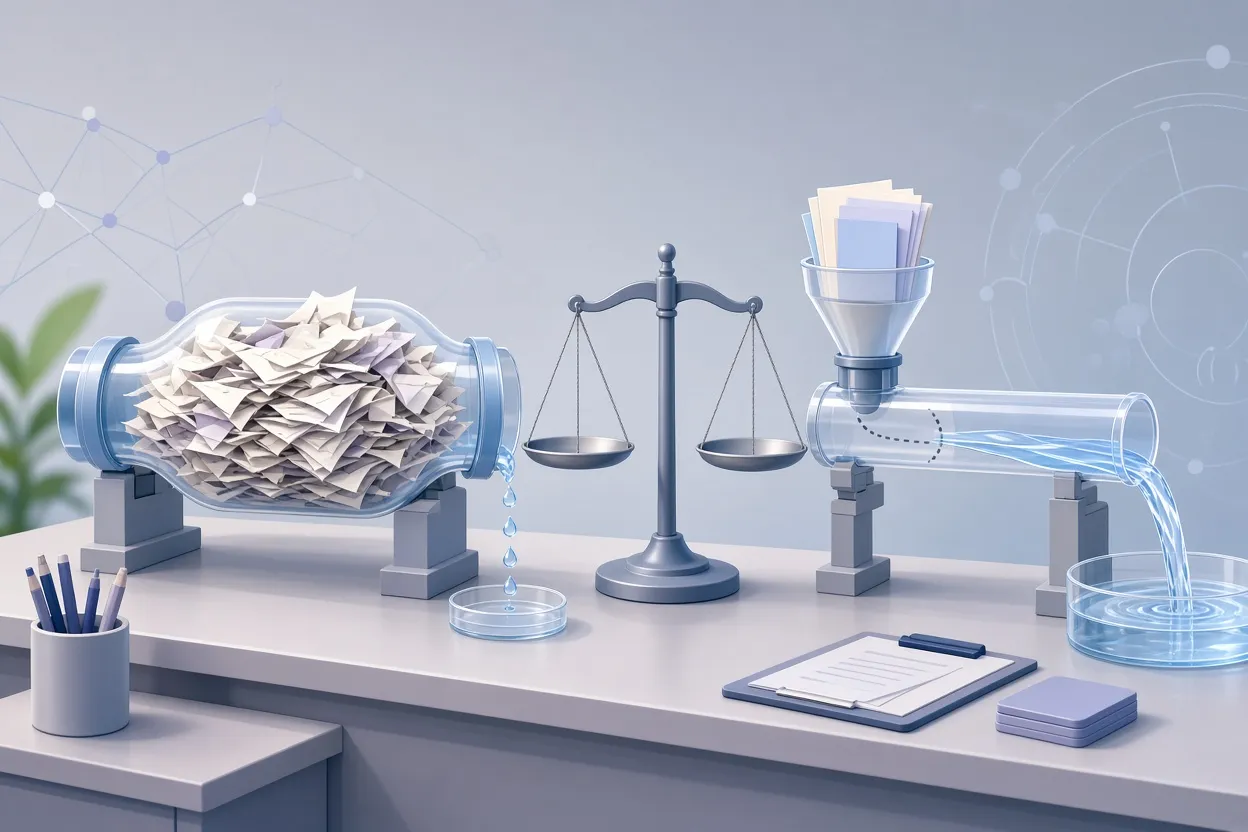
▲ Naive versus governed agent context flow
The practical effect appears in a comparison on Fieldbooks, an enterprise benchmarking platform. Two agents answered the same complex portfolio-risk question about net exposure to the Acme group: a Governed Analyst backed by an intelligence plane, and a Naive Analyst without one. The figures below come from this single evaluation run.
| Metric | Governed Analyst | Naive Analyst |
|---|---|---|
| Golden-answer accuracy | 97% | 33% |
| Total tokens | 32,999 | 234,267 |
| Inference cost | $0.0362 | $0.4567 |
| Average latency per query | 10.6 seconds | 42.8 seconds |
| Context size | 3,425 tokens | 18,277 tokens |
| Cache hits | 4 exact, 5 semantic (of 29 turns) | not applicable |
The governed agent's semantic and ontology layers resolved the credit parentage structure and metrics such as Desk NAV correctly. The naive agent, relying on keyword-style retrieval, miscalculated the credit metric by 5.42% relative to the golden definition. In a regulated setting, a 5% error is treated as unacceptable rather than approximately right. Precise semantic pre-filtering and exact-match caching explain much of the token and latency savings; the claim is that an ontology and semantic layer can cut token use by more than 80% on complex tasks while raising accuracy. One caveat: the figures come from pre-cached benchmark runs rather than queries generated fresh for the comparison.
Four things teams can do now
The architecture translates into four immediate steps:
- Treat memory as first-class, governed data. Store it in the database alongside the business records it came from, under the same compliance, retention and governance rules, rather than in an external black-box silo.
- Define business entities, metrics and ontologies explicitly before agents are forced to guess them.
- Push entitlements and role-based permissions down into the database layer so that retrieval and memory caches inherit access rules natively.
- Capture granular execution traces today: user interactions, task sequences and human corrections are tomorrow's fine-tuning datasets.
A common failure mode noted is agent identity: teams stitch together disparate third-party identity providers instead of propagating the end user's identity straight to the database.
How Oracle maps its tooling onto the plane
Oracle places the intelligence plane above the control and data planes and offers tools across five pillars.
Agent memory and context cards
The oracleagentmemory Python package, installable with pip, reduces memory engineering to three primitives: users and agents, memories, and threads. It condenses long multi-turn histories, including tool calls and corrections, into structured "context cards" with sections for topics, summary, relevant information and relevant messages, which are injected into the prompt. On the LongMemEval benchmark, which tests long-term conversational memory, the package answered 472 of 500 questions correctly (94.4%) when paired with GPT-5 at high reasoning effort.
Memory traces double as training sets: workflow traces train small planning and tool-calling models to run multi-step workflows in one pass; memory units train decision models that classify in milliseconds whether new context should be kept, forgotten or flagged sensitive; corrections fine-tune rerankers and answer models; and entity memories train extraction models.
Deep Data Security
Rather than filtering in application code, Deep Data Security makes the database enforce access. When a user prompts an agent, their OAuth2 token travels through the agent harness into the database. During SQL execution, Oracle AI Database rewrites the query, evaluates row-, column- and cell-level policies, drops unauthorized records before retrieval, and logs an auditable check. An analyst cleared only for Desk A sees Desk B rows and margin columns stripped out, while a colleague cleared for both desks sees everything. Because memory lives in the same database under the same security context, recalled context cards obey identical permissions.
Private inference
For regulated industries, the Private AI Services Container runs on premises or air-gapped, packaging LLM inference via vLLM or llama.cpp on CPUs or GPUs, embeddings, reranking and text classification behind OpenAI-compatible REST endpoints. Oracle AI Database can call these models directly from SQL through functions such as DBMS_VECTOR_CHAIN and UTL_TO_GENERATE_TEXT. Teams preferring managed infrastructure can use OCI Generative AI for fine-tuning and hosting, including Grok and OpenAI models on dedicated clusters.
Continual learning with Memoriaz
Memoriaz, an open-source continual learning system, teaches small open-source models to manage memory planes. Its dashboard tracks three fine-tuned components: memory routing, memory embeddings and memory reranking. A Qwen model fine-tuned on conversation trace logs routes incoming context to conversation memory or workflow memory in milliseconds on consumer Apple silicon; the dashboard showed 85.6% routing accuracy against an 83.3% comparison figure and 98.2% reranking accuracy, alongside loss curves and per-epoch accuracy used to gate deployment. The payoff is lower latency and cost than sending unstructured context to a frontier model every time.
Continual learning spans three tiers: truth space (memory engineering in the database), latent space (prompt caching of KV states) and weight space (fine-tuning with LoRA or QLoRA). Traces are filtered by classification, fine-tuned, evaluated against gate benchmarks and deployed back to the database through ONNX runtimes.
Private Agent Factory and schema enrichment
Private Agent Factory offers a no-code canvas for connecting input, prompt, model and output blocks into governed agents. AI schema enrichment inspects tables and writes column descriptions and semantic annotations into the metadata, so models do not have to infer what a column like PARK_CODE means. Oracle AI Database combines SQL property graphs over relational tables with RDF knowledge graphs to model parent-subsidiary LEI ownership structures, and a governed semantic layer fixes definitions such as net exposure so every agent calculates them the same way. The stakes cited are concrete: in finance, an ungrounded calculation error can expose a firm to a regulatory fine on the order of $100 million.
What this means for practitioners
The core claim is that with models and data commoditized, the differentiator is the layer that decides what an agent knows, remembers, sees and learns, and that teams focused only on orchestration and tool guardrails are neglecting it. The benchmark figures come from one run on one platform, so treat them as an illustration rather than a guarantee. The design guidance, however, applies regardless of vendor: keep memory inside the governed database, write down your ontologies and metric definitions, enforce entitlements in SQL rather than application code, and start logging execution traces now so that specialized small models can take over routing, reranking and planning later. In this view, owning the memory and ontology layer is the moat, and renting it from a black box is the risk.


