OpenAI’s new Decisions API does not write answers. It picks one. You send text or an image along with a fixed list of possible answers, and it returns a probability for each option in about 150 milliseconds, with no output tokens to pay for. Put to work on seven practical builds, from a distraction-catching focus timer to a rough-cut video editor, it shows clearly where a fast, cheap classifier beats a chat model and where it falls short.
How a decision model differs from a chat model
A standard language model generates its answer one token at a time. A token is the small chunk of text a model reads and writes, and every extra token adds both delay and cost. The Decisions API skips generation entirely. It scores a set of predefined options in a single pass through the model, so it produces zero output tokens.
A customer support example shows the idea. Send the message “I was charged twice for my order” with four options, Billing, Technical, Shipping and Other, and the API returns Billing with 100% confidence. The answer is always one of the options you supplied.
The same mechanic can drive a bot that plays an open-source first-person shooter with no human input. Screenshots and coordinate data are paired with movement choices (advance, back off, strafe) and action choices (fire, reload, jump), and the bot makes these calls several times per second for a fraction of a cent per decision.
OpenAI’s own figures put the numbers in context:
| Measure | Decisions API | Standard gpt-6-luna call |
|---|---|---|
| Typical latency | About 150 ms | About 1.6 seconds |
| Price | $0.10 per million input tokens | Charged per generated token |
| Output tokens | None | Yes |
There are no fees for output tokens, cache reads or cache writes.
The rival that came first
OpenAI did not invent this approach. TypeSafe AI, a company founded by a former OpenAI researcher, announced Jev on September 15, 2026, and billed it as the first public “System One” model: a model built for instant classification and structured probabilities rather than slow, deliberate reasoning. Early users ran it on high-volume sorting jobs, such as triaging thousands of support emails or tagging real estate listings by architectural style or highway proximity.
| Feature | OpenAI Decisions API | TypeSafe AI Jev |
|---|---|---|
| Price per million input tokens | $0.10 | $0.042 |
| Inputs | Text and images | Text only |
| Notable spec | Reads screenshots and photos directly | 64k-token request context |
Jev costs less than half as much, but it cannot see. The Decisions API accepts images and live desktop screen captures, which is what makes real-time visual bots possible. That vision support appears to be the deciding difference between the two.
Getting set up
- Create an API key on OpenAI’s developer platform. API usage is billed separately from a ChatGPT subscription.
- To experiment without code, use the Decisions Playground on the same platform to try inputs and option lists.
- To build an app, describe it to a coding agent such as Claude Code or Codex and keep the API key in a local .env file.
▲ Instant decisions on screen and voice input
Seven builds and what they showed
1. A focus timer that notices when you drift
This desktop app adds screen awareness to a 25-minute Pomodoro timer. You type your goal, such as coding, and every few seconds the app captures all connected monitors and asks the Decisions API whether the screen still matches that goal. If you stay off task for more than a minute, it scolds you through text-to-speech. Scrolling through ads on X turned the floating orb orange and triggered a spoken reminder to get back to coding; returning to work shrank it back. A beginner project becomes an active monitor once it gains vision and instant classification.
2. Lag-free voice control for macOS
Hold a push-to-talk key, speak, and speech-to-text turns the command into text. The Decisions API then chooses from a list of actions: launch or quit an app, switch apps, or control browser tabs and navigation. Claude built the Electron app in about 15 minutes, and commands resolved in roughly 120 to 280 milliseconds. Holding Right Option and saying “Open Arc” or “Open Google Chrome” switched apps almost instantly.
Two lessons came out of the build. When actions were organized as a nested, multi-step hierarchy, “quit Spotify” drew only 67% confidence. Flattening the choices into a single list restored both confidence and speed. And the app needs both Accessibility and Input Monitoring permissions granted in macOS System Settings.
3. Cleaning ads and bait out of an X feed
A Chrome extension sends each post’s text and images to the Decisions API, asks whether it is an ad or low-effort engagement bait, and collapses flagged posts into a thin bar you can expand. Claude wrote and tested it against a mock feed in about four minutes. It did over-trigger at first, hiding company product announcements and ordinary posts that used promotional language. Telling the model to look specifically for the “Ad” label in the top right corner of a post addresses that.
4. Automatic blurring of private data in screen recordings
FFmpeg pulls a frame every half second, the Decisions API checks each frame for personal information such as API keys, email addresses, phone numbers and home addresses, and the tool blurs the spot it locates. A one-minute test recording filled with fake emails and secret keys produced these results:
| Measure | Result |
|---|---|
| Frames checked | 144 |
| Frames flagged | 84 |
| Total pipeline time | 15.8 seconds, about 4.6 times faster than real time |
| API cost | $0.0732 |
An earlier approach, uploading the whole video file to Gemini to scan for sensitive data, was slower and more cumbersome.
5. A Wikipedia race as a speed and cost benchmark
In a Wikipedia race, a model moves from one article to a distant target by choosing the most promising link on each page. Three competitors ran side by side: the Decisions API, Jev and GPT-5.5 as a standard chat model.
| Route | Decisions API | Jev | GPT-5.5 |
|---|---|---|---|
| Banana to Moon landing | 3 hops, 2.9 s, $0.00327 | 3 hops, 7.3 s, $0.00272 | 2 hops, 8.9 s, $0.0944 |
| Taylor Swift to Photosynthesis | 3 hops, 1.2 s, $0.00242 | 3 hops, 2.0 s, $0.00179 | 3 hops, 16.3 s, $0.1277 |
| Pokémon to Roman Empire | 6 hops, 3.1 s, $0.00268 | 5 hops, 2.1 s, $0.00136 | 2 hops, 14.2 s, $0.0678 |
The chat model sometimes found shorter paths, but the dedicated decision models were often about 10 times faster per step and roughly 20 to 50 times cheaper.
6. Calorie counts from a single photo
This mobile web app, opened in Safari on an iPhone over local Wi-Fi, has one camera button. Its data comes from the free USDA FoodData Central list, which Claude organized into 5,412 food products across 172 categories. The key design choice is that the model never reasons about calories. The Decisions API answers two constrained multiple-choice questions, food category and portion size, and a follow-up call narrows down the specific item. Ordinary code then calculates calories from the database’s standard weight tables.
A cheeseburger photo came back as 488 calories in about one second for $0.000054. An eight-pound bacon-wrapped novelty burrito, however, was classified as an extra-large burrito and scored only 964 calories. Fixed portion buckets such as small, medium, large and extra large cannot handle extreme outliers like that without a reasoning model.
7. Finding bad takes in raw footage
The last build removes flubs, false starts, restarts and dead air from raw recordings. Editing with Opus 5.5 inside Adobe Premiere Pro reached about 98% accuracy but cost hundreds of dollars in API fees per video. So the first, coarse pass goes to the Decisions API instead. Whisper-1 transcribes the audio with timestamps, the transcript is split into sentences, and each line is classified as a flub, false start, restart, editor cue or keeper.
| Test | Result |
|---|---|
| 4-minute, 45-second 4K clip | 40 decisions in 1.3 seconds, all 7 bad takes found, $0.0029 for decisions plus $0.029 for transcription |
| 4.25 GB raw file | Audio extraction 0.2 s, transcription 5.7 s, decisions 1.7 s; 54 dead-air pauses and 7 bad takes marked |
Whisper-1 beat a locally run MLX Whisper model on both speed and accuracy of word-level timestamps at the points where speech stumbles. Lines with low confidence scores can be routed to a larger reasoning model such as Opus, creating a tiered, cost-efficient editing workflow. The browser-based editing interface Claude generated was cluttered and confusing, but it worked.
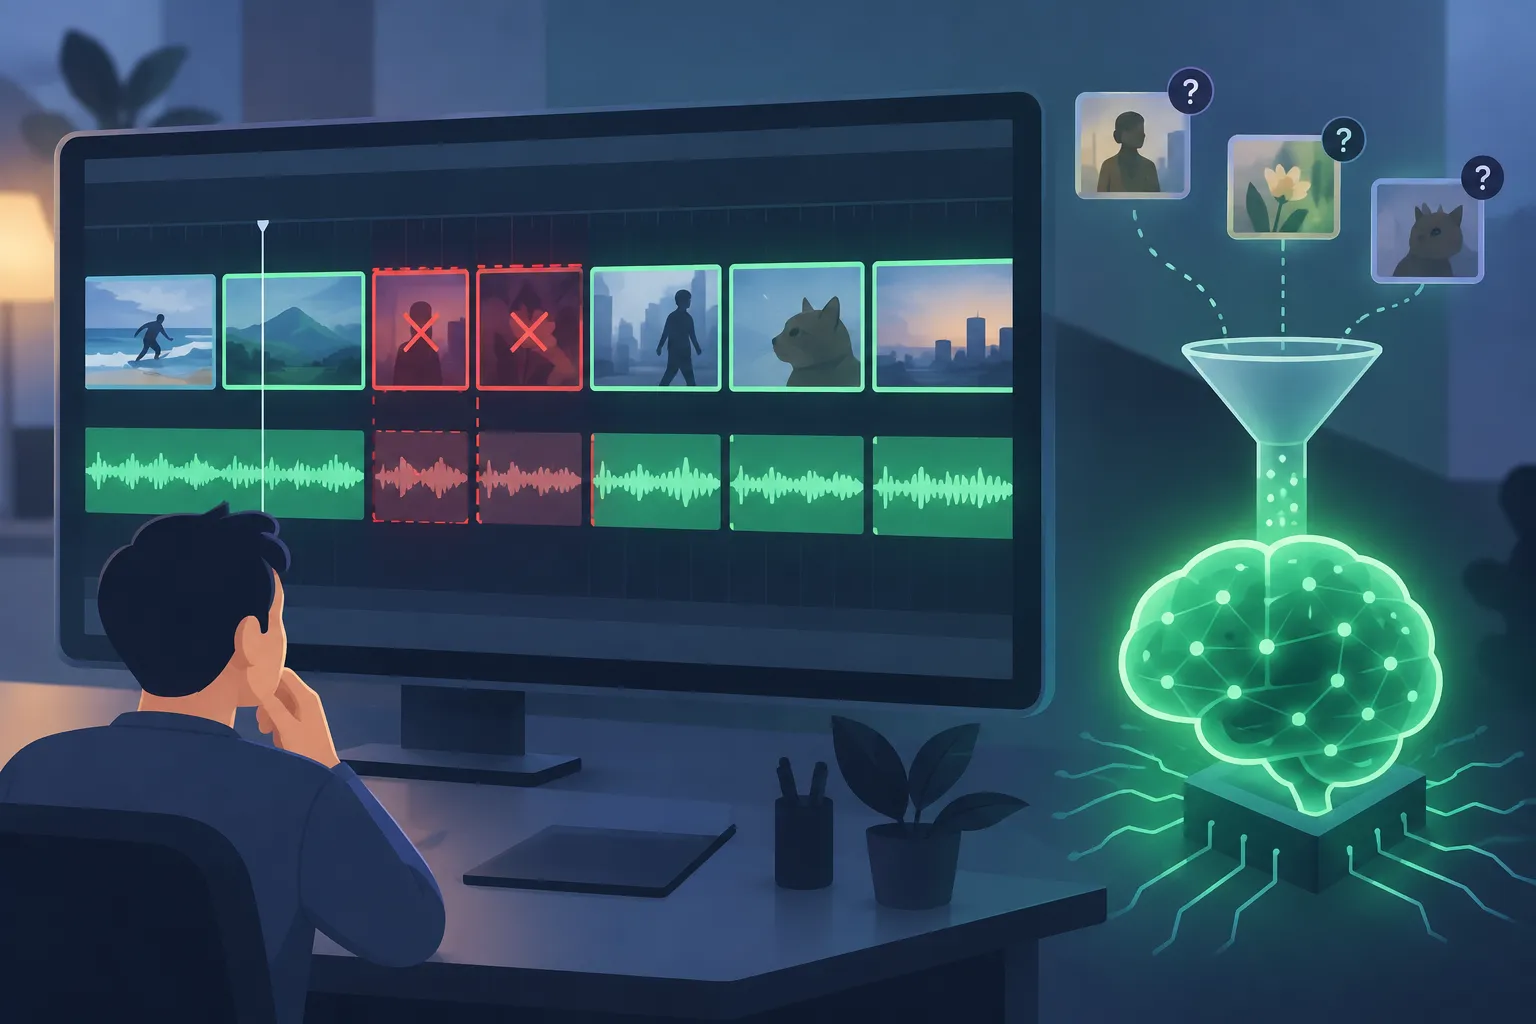
▲ Cheap first pass before a larger model
Limits to know before you rely on it
- It cannot act outside its list. Voice commands to type text into the browser or open a URL with no mapped action failed, because the model only chooses among the actions it is given.
- It misses subtle nuance in complex edge cases. Those still call for a full reasoning model.
- Nested option trees lower confidence. A single flat list works better.
- Classifiers can over-trigger. When that happens, give the prompt a concrete cue to look for, as with the “Ad” label.
- Fixed buckets break on extreme values, as the novelty burrito showed.
Where to start
The Decisions API fits work that repeats a bounded choice many times, fast and cheaply: real-time tools that react to what is on a screen or in a photo, bulk sorting of text or video frames, and a cheap first pass in front of an expensive model. A sensible way to try it:
- Pick one task in your work whose answer falls into a few fixed categories and test it as an option list in the Decisions Playground.
- Keep the options in one flat list rather than a nested tree.
- Let the model pick categories, and let lookup tables and code produce numbers such as calories or prices.
- Set a confidence threshold and send only the items below it to a larger reasoning model.
- If you need image input, use the Decisions API; for text-only bulk classification where cost matters most, compare it with Jev.