OpenAI did not build a separate model for Wall Street. According to Joseph Kim, OpenAI's head of financial services, ChatGPT for Financial Services, launched on September 10, 2026 with Morgan Stanley and Evercore as design partners, runs on the same flagship models everyone else uses. Financial reasoning data flows into the company's main pre-training pipeline, and the product itself is mostly standard ChatGPT plumbing wrapped around licensed market data, firm-specific templates and a workflow that assumes a human reviews every result. The design choices behind that approach say a lot about how OpenAI thinks vertical AI products should be built.
Why there is no dedicated finance model
OpenAI describes itself as a research and deployment company, and Kim says the ordering is deliberate: research and capability evaluation come first, and product design follows. In practice, that means financial reasoning and analysis data is "upstreamed" into what the company calls the Big Run, the pre-training run that produces flagship models such as the 6 Astra and 6.1 Astra series.
The effect is that financial capability is not siloed inside one enterprise product. Any third-party developer calling the core models gets the same underlying reasoning. The finance team then operates, in Kim's words, essentially as an internal startup on top of those foundation models, facing the same technical hurdles an outside company would.
The 80/20 thesis and the 95% that anyone can copy
The team's core thesis is simple. An off-the-shelf model such as Codex delivers roughly 80% of what a viable financial product needs. Ship that raw 80% into a bank, however, and the product fails. The missing 20% is specialized workflows, proprietary data and user-interface work tailored to how finance professionals actually operate.
Kim is candid that about 95% of ChatGPT for Financial Services consists of standard ChatGPT plugin architecture and primitives that are available to all external developers today. The training-level work generates the most excitement, but plain harness and integration engineering accounted for the overwhelming majority of the product's commercial traction. From that, Kim draws a prediction: a standalone billion-dollar software business will be built by capturing that 20% vertical layer on top of ChatGPT plugins. This is presented as a forecast, not a result.
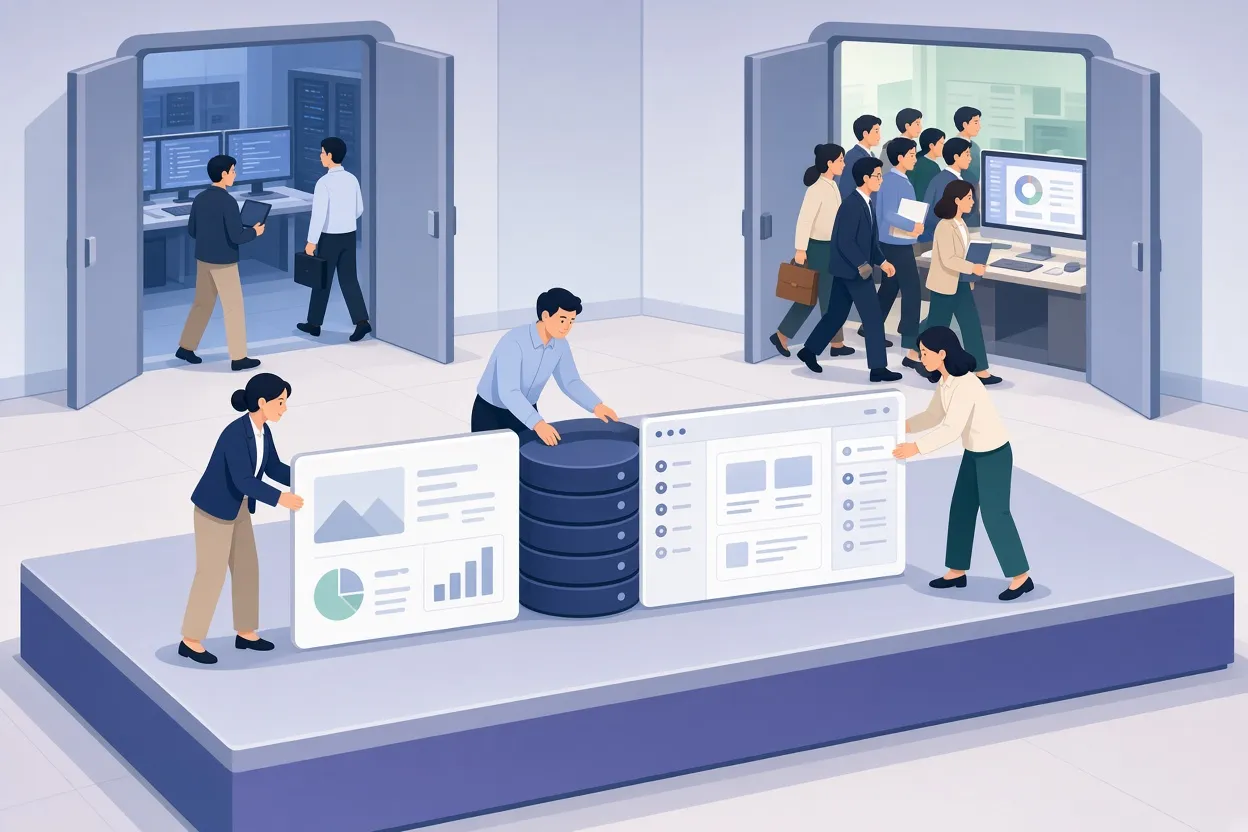
▲ The 20% domain layer and the desktop app adoption leap
Form factor matters: the Codex adoption curve
An internal OpenAI chart tracking Codex usage by department since August 2025 illustrates why the product layer is not optional. Software engineering adoption rose steadily and linearly. Finance, recruiting and legal teams sat near 0% for months. When the Codex desktop app shipped in February 2026, adoption in those non-technical teams jumped almost vertically to roughly 90%.
| Department group | Before Codex desktop app | After February 2026 |
|---|---|---|
| Software engineering | Steady linear growth from August 2025 | Continued growth |
| Finance, legal, recruiting | Near 0% | About 90% |
The lesson OpenAI took from this is that business professionals will not engage with raw developer environments or command-line tools. They need a dedicated interface built for their work.
Why OpenAI hosts the market data itself
From a first-principles view, bundling financial datasets looked redundant. Enterprise clients often already hold licenses with data vendors, and third-party connectors using the Model Context Protocol (MCP), an open standard for linking AI models to external data sources and tools, already existed.
Testing told a different story. External MCP connectors for several prominent financial data providers failed more than 40% of the time. For an enterprise product, that reliability level was unacceptable. OpenAI instead chose to license, index and host datasets from vendors including Daloopa, PitchBook, LSEG News, Crunchbase and S&P directly on its own infrastructure. The product interface exposes these as plugin options such as Company Filings, Financials & KPIs, SEC Filings, Earnings Calls & Transcripts, Investor Presentations and Market News & Trading.
Direct indexing sharply reduced latency and failure rates, and Kim says the built-in data bundle became the feature enterprise users praise most. The broader point, in his telling, is that enterprise tools cannot be designed purely from theory. They have to adapt to commercial realities, existing licensing arrangements and user habits.
Designing for a human in the loop
The first version of the product is a productivity tool for financial knowledge workers, and it rests on a single assumption: a human is always in the loop. Much as software engineers use coding assistants, an analyst can use the model to complete 30 to 80 percent of a daily task while keeping responsibility for final auditing and validation.
For the more autonomous agents expected in 2027 and 2028, the team is designing agent security profiles that mirror how people already supervise each other. Kim points to engineering practice at Google, where readability certifications and peer checks gate code changes before deployment. Investment banking has its own implicit version: junior analysts do the groundwork, associates review and improve it, and vice presidents or managing directors apply final scrutiny. Because those tiers already exist to stop human mistakes from reaching business outcomes, slotting AI output into the same ladder provides natural risk management.
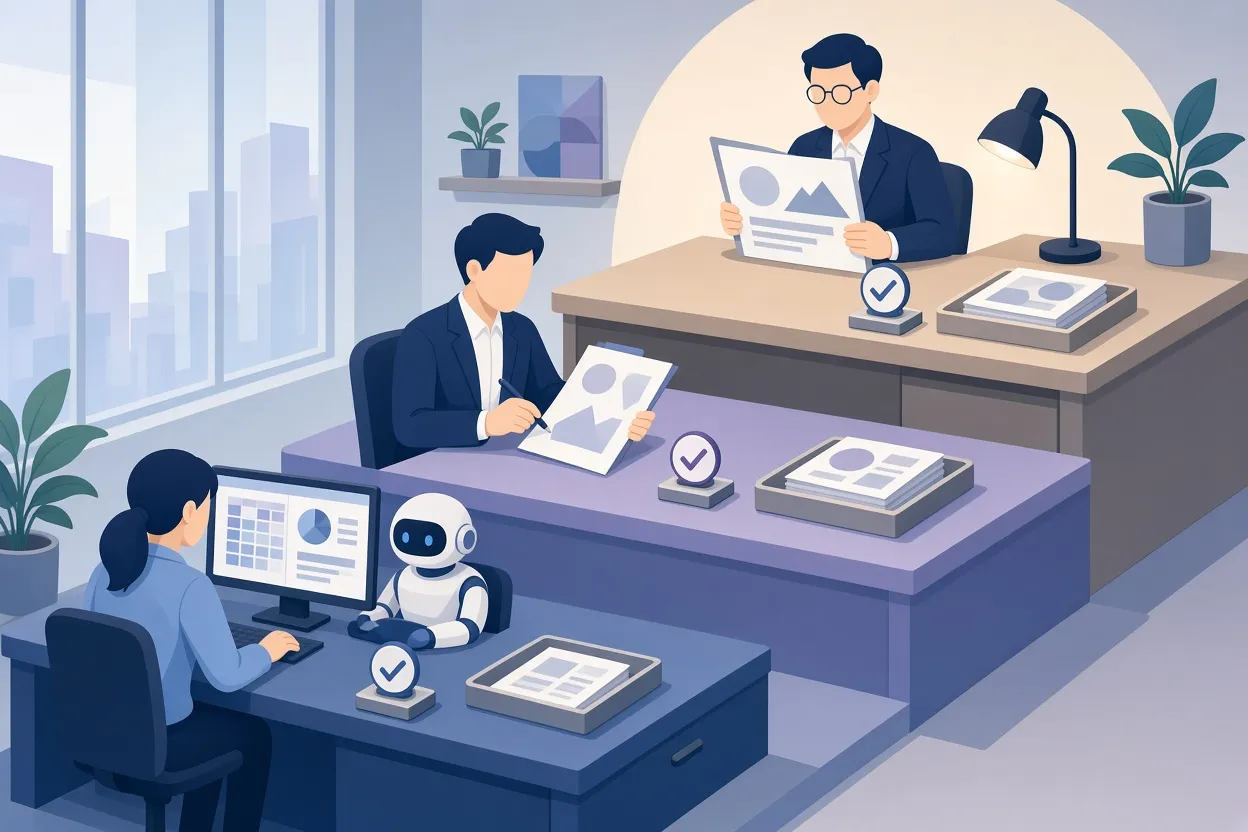
▲ AI output passing through the banking review ladder
The fear of the career-ending mistake
Junior analysts often worry that one compounding error could end a career. Kim's view is that not all mistakes are equal. The truly dangerous ones occur when factually wrong data changes a final business conclusion, and those rarely escape institutional safety nets, because senior leaders only see work that has passed multiple layers of review. He also argues that factual hallucination, the dominant complaint of 2022 and 2023, has diminished dramatically as models improved in precision and reliability.
The real gap: taste, not facts
What models still get wrong, according to Kim, is taste. A slide deck can carry accurate numbers and still be ugly, poorly formatted or visually sloppy. That subjective quality, rather than basic fact-checking, is now the main bottleneck for AI work products in finance.
To close it, the team went back to the technique that launched instruction-following language models in the first place. InstructGPT in 2022 used reinforcement learning from human feedback (RLHF), in which human labelers rank several model outputs from best to worst and a reward model is trained on those pairwise comparisons. Recent machine learning trends have emphasized verifiable environments with hard reward functions, but Kim argues pairwise human preference remains the superior method for teaching design nuance.
The team applied this directly to slide generation, collecting human ratings on side-by-side presentations to build aesthetic benchmarks. Humans can judge which of two layouts looks better within seconds, whereas automated grading models tend to over-analyze individual pixel placements and reach wrong conclusions.
The software engineering precedent
Kim frames financial modeling as structurally similar to coding. Software combines verifiable rules such as compilation, syntax and unit tests with qualitative judgment about clean design and maintainability. A financial model has verifiable elements, such as whether Excel sums compute and whether references are broken, alongside a qualitative feel for how inputs perturb outputs, which experienced professionals test intuitively. Because AI has made strong progress on clean, well-structured code, the team is confident the analogous finance problems can be solved.
Evaluation is moving the same way. Cognition's FrontierCode benchmark asks not whether a patch resolves an issue, as SWE-bench does, but whether a human maintainer would actually merge the pull request among several valid solutions, measuring hygiene, style and mergeability rather than binary success.
From junior analyst tasks to fuzzier objectives
Most AI finance applications so far target junior analyst work, and for two reasons: current models excel at explicit, structured instructions, such as building slides in a corporate template with precise brand styling, and finance professionals dislike repetitive, detail-heavy tasks like multi-tab Excel models where small formula errors cascade.
With that low-hanging fruit largely addressed, the roadmap for 2027 moves up the hierarchy toward associate and managing director responsibilities, including investment theses. Objectives there are far fuzzier, and validating a contrarian multi-year thesis can require three or more years of real market feedback. Kim says reaching near-expert reasoning will demand high-quality financial data paired with feedback from practitioners at the 99.9th percentile, and OpenAI has designated financial services a dedicated strategic research priority.
Why benchmarks are harder than they look
Every evaluation is an imperfect proxy for human capability, and Kim describes building good ones as exceptionally difficult and widely underestimated. Answer keys and scoring functions are painstaking to create, and weak evals invite reward hacking. OpenAI's own GDPval benchmark, which spans 44 occupations, became saturated on general knowledge tasks and contained broken, uninformative items.
During GPT-6 testing under the Astra project, financial benchmark scores stopped reflecting real progress because legacy evals had hit ceilings. A deep inspection found flawed questions, erroneous answer keys and ambiguous prompts rather than model regressions. Kim notes a common bias here: researchers accept good numbers without scrutiny and only audit tests when scores disappoint. OpenAI is now building a new generation of investment banking evaluations meant to correlate with full automation of junior roles, and treats objective metrics for financial taste as an open call to quantitative practitioners.
What this means and what to do
The picture that emerges is of a vertical AI product built from a shared foundation model, in-house hosted data, a purpose-built interface and a review workflow borrowed from existing institutions. OpenAI is rolling ChatGPT for Financial Services out to enterprises, plans to bring features to ChatGPT Pro, and is hiring front-end and back-end engineers, product managers with investment banking, equity research and asset management backgrounds, and subject matter experts to train base models directly.
For readers, a few practical takeaways follow from this account:
- Test any third-party data connector for error rates and latency before relying on it in critical workflows, and consider hosting and indexing key datasets yourself.
- Give non-technical teams a dedicated interface rather than developer tooling if you want adoption.
- Spend engineering effort on the domain-specific 20%, such as templates, proprietary data and workflow, rather than training a bespoke base model.
- Treat every AI output as junior analyst work: it goes through the same review ladder before anyone acts on it.
- For subjective quality, collect side-by-side human preferences rather than writing deterministic rules, and separate verifiable checks from taste checks.
- Scrutinize strong benchmark results as aggressively as weak ones.
Finance professionals curious about these workflows can evaluate ChatGPT for Financial Services through their institutions, and those interested in building it can look at OpenAI's careers page.


