Developers who build AI agents rarely train a model or write a GPU kernel, yet the decisions they make about tools, memory and prompts are bounded by what happens inside the model: how it picks the next token, how attention lets it look back at earlier text, and how much memory that lookback costs. Treating these mechanics as prerequisites for agent work rather than background trivia pays off in a set of concrete design rules: tune sampling to the task, expect accuracy to fall as context grows, keep tool sets small, append new information at the end of the prompt, and never let automated context compaction erase a safety instruction.
Where agent builders sit in the stack
One way to organize work with large language models is a three-tier stack. At the base is LLM engineering: distributed compute, transformer architectures, custom GPU kernels, scaling laws, pretraining, post-training, reinforcement learning and tokenizers. In the middle is LLM adaptation: supervised fine-tuning, distillation, in-context learning, LoRA (a method for cheaply fine-tuning a model by training small low-rank weight updates), and preference alignment through RLHF or DPO. At the top is LLM applications: chatbots, retrieval-augmented generation and agents.
Agent builders live at the top. The argument for studying the lower layers anyway is practical: a developer who understands key-value caching and attention variants can anticipate context limits and compute overhead instead of discovering them in production. The stack itself is an informal framework, not an industry standard.
How a model picks the next word
A language model assigns a probability to a sequence of tokens (words or subword pieces) by multiplying conditional probabilities: the chance of each token given everything before it. For the sentence "The class was about agents ." the first token "The" gets a marginal probability of 0.0377, "class" given "The" gets 0.0001, "was" given the first two gets 0.0344, and the final period gets 0.0252. The product for the whole sentence is 1.2e-17. Because multiplying many small numbers underflows floating-point arithmetic, practitioners sum log probabilities instead.
This definition is why language models count as generative rather than discriminative models. A discriminative model such as logistic regression or an SVM learns a decision boundary, like separating cat photos from dog photos. A generative model learns the data distribution itself, so it can be sampled from. Picking the next token looks like classification over a vocabulary, which makes the boundary feel fuzzy, but the model defines a full joint distribution over any text sequence, and that is what lets it generate.
Generation works one token at a time. Given "The class was about", a model spreads probability across its vocabulary, which in modern models typically holds about 128,000 subword tokens: "to" at 0.3171, "as" at 0.0491, "the" at 0.0360, "a" at 0.0330, "two" at 0.0147, "how" at 0.0124, and so on. Sampling "to" extends the context, and the next distribution puts "be" at 0.1501, "begin" at 0.0855, "go" at 0.0627 and "start" at 0.0496.
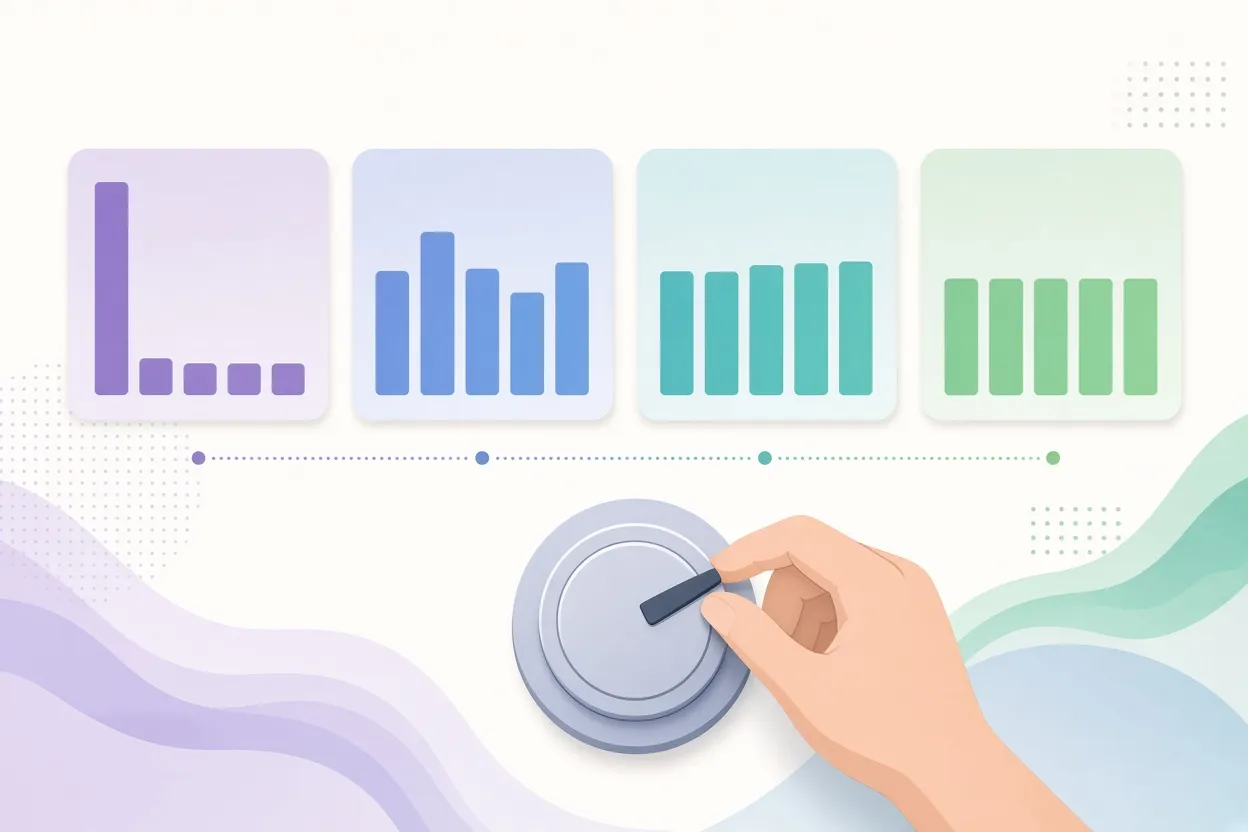
▲ Effect of temperature on token probabilities
The developer decides how to draw from that distribution. Temperature is a divisor applied to the raw logits before the softmax renormalizes them to sum to one. It has no natural bound; a temperature of 5 is just a scaling factor. Low values sharpen the peak and push behavior toward greedy decoding; high values flatten the distribution and lift unlikely tokens. For the prompt "I am tired, I will take a ___", candidates like "nap", "break", "rest", "bath" and "shower" shift from one dominant bar at T=0.1 to nearly even bars at T=2.0.
| Strategy | What it does | Trade-off |
|---|---|---|
| Greedy decoding | Always takes the highest-probability token | Fast and deterministic, but can produce repetitive or locally greedy text |
| Top-k | Samples from the k most likely tokens, for example k=5 | Fixed pool size regardless of how confident the model is |
| Top-p (nucleus) | Samples from the smallest set whose cumulative probability reaches p, for example 30 percent | Pool size adapts to the distribution |
| Temperature | Divides logits by T before softmax | Low T for predictability, high T for diversity |
| Beam search | Tracks several candidate sequences at once | Higher overall sequence likelihood, but much more time and memory |
The rule of thumb is task-driven: math and code want low temperature; creative writing wants higher entropy, usually with top-p or top-k. Beam search can find higher-probability sequences than greedy decoding, but holding multiple hypotheses in memory often makes it cost-prohibitive for interactive agents. Candidates in beam search can be ranked by cumulative probability, a task-specific value function or an external verifier.
Two details matter for agent loops. Temperature is an inference hyperparameter, not a learned weight, although reinforcement learning rollouts sample at a fixed temperature. And changing temperature between tokens does not invalidate the KV cache, so it is technically feasible even though production systems rarely do it. Reasoning models add multi-step thinking, but temperature remains a live tuning decision for reasoning quality.
Inside attention: why context has a cost
Nearly every modern LLM is a decoder-only transformer, descended from the 2017 "Attention Is All You Need" paper by Vaswani and colleagues at Google, which introduced an encoder-decoder design for translation. Modern generative models drop the encoder and keep the decoder, and both share the same attention block.
Walking through that block with the tokens "The", "class", "was", "about" shows where context limits come from:
- Each token is looked up in a learned embedding table to get a vector.
- A positional embedding is added, because attention on its own is permutation-invariant: without positions, the model could not tell which accessible token came first.
- The stacked vectors pass through layer normalization.
- Three learned matrices, W_Q, W_K and W_V, project them into queries, keys and values, each with a bias term.
- Multiplying Q by the transpose of K yields an n-by-n score matrix, where n is the sequence length.
- A causal mask blocks each token from attending to later tokens. During training the whole sequence is processed in parallel, so without the mask the prediction after "The" would leak information from "class" and "was".
- Scores are divided by the square root of the key dimension, softmaxed so each row sums to one, and multiplied by V.
- An output projection W_O maps the result back to the model dimension, and a residual connection adds the original input to keep gradients flowing.
Multi-head attention runs several sets of Q, K and V projections in parallel, concatenates the outputs and projects them through a wider W_O, letting the model attend to different representation subspaces at once. A full block adds a feed-forward layer and another residual, the block is stacked N times, and a language modeling head followed by softmax produces the next-token distribution. Weights start random, so early forward passes produce noise until gradient descent trains them.
The complexity table from the original paper explains both the transformer's success and its context problem. Self-attention costs O(n^2 * d) per layer, where d is the representation dimension, but needs only O(1) sequential operations, so an entire sequence can be processed in parallel on a GPU. Recurrent networks cost O(n * d^2) but require O(n) sequential steps. Parallelism is what let transformers train on huge corpora; the quadratic term is what makes long contexts expensive. For scale, the original "Transformer (big)" model had roughly 200 million parameters and took 2.3 x 10^19 FLOPs to train, large in 2017 and tiny beside today's trillion-parameter models.
Linear attention and hybrid models
Linear attention, as in the DeltaNet formulation, removes the softmax between queries and keys. With everything linear, matrix associativity lets the model compute K-transpose times V first, producing a d-by-d state matrix whose size does not depend on sequence length. The state updates each step by clearing irrelevant memory and adding a new key-value outer product, so runtime and GPU memory grow linearly from 2^9 to 2^16 tokens.
The cost shows up in retrieval. On the RULER benchmark's needle-in-a-haystack tasks, where a magic number is hidden in essay text and queried at the end, Llama-2-7B holds high accuracy to 8k tokens while RWKV-v5-7B and Mamba-2.8B degrade sharply beyond 2k to 4k tokens. A fixed-size state must compress all history, so specific facts get lost.
| Property | Full softmax attention | Linear attention |
|---|---|---|
| Compute vs. sequence length | O(n^2) | O(n) |
| Context mechanism | Every token can look back at every earlier token | History compressed into a fixed d-by-d state |
| Memory during inference | KV cache grows linearly, O(n) | Constant state size |
| Long-range retrieval | Strong | Weak |
In practice architects mix the two. DeltaNet interleaves sliding-window and linear layers with periodic global attention layers; adding global attention raised average retrieval from 22.7 percent to 32.7 percent and improved Wikipedia perplexity from 28.24 to 27.51 without hurting common-sense scores. Kimi K3, an open frontier model, combines Multi-Head Latent Attention with KDA linear layers, stable layer normalization and feed-forward blocks, using gating to control memory during generation.
One more point: neither attention formulation imposes a maximum context length in its equations. The hard limit comes from learned positional embeddings. A model can only interpret positions it saw during training, so extending context means adjusting or interpolating those embeddings.
Prefill, decode and the KV cache
Inference runs in two regimes. In prefill, all prompt tokens pass through the model at once, with dense matrix multiplications of high arithmetic intensity; under the Roofline performance model this phase is compute-bound. In decode, the model emits one token per step. Intermediate activations are discarded, but keys and values are kept as the KV cache, which grows with every token. Each step reloads the model weights and the cache for a single-token update, so decode is memory-bandwidth-bound. Time to First Token measures prefill; Time Per Output Token measures decode.
For agents, which loop over long contexts of tool schemas, environment observations and interaction traces, this split has consequences. KV cache memory should be profiled early, and it is worth knowing whether a hybrid or linear-attention model fits the workload. Speculative decoding helps the bandwidth bottleneck: a small draft model proposes several tokens, the target model verifies them in one parallel pass, and generation resumes from the first rejection. Acceptance rates are higher on code (HumanEval) than on summarization (XSum) because code syntax is more predictable, and longer drafts eventually lower acceptance enough to erase the gain.
Reasoning models spend extra tokens at inference time to catch their own mistakes, and on the Agent's Last Exam benchmark accuracy rises with token budget across GPT-5 Astra and Claude Opus. Effort can be set to low, medium, high or max; higher effort improves accuracy at a steep cost in latency and spend. Kimi K3 trains this control with a reward of +1 for a correct answer, 0 for an incorrect one within budget and -1 for an incorrect one that exceeds budget, then distills nine teacher models across three domains and three effort levels into one student.
Structured output and context engineering
Agents sit inside compound systems that call APIs, databases and code interpreters, so their outputs need strict contracts. Constrained decoding forces generation to follow a regex or JSON schema. SGLang compiles the schema into a finite state machine, inserts fixed syntax such as quotes and braces without a model forward pass, and only invokes the model at transitions where several tokens are valid; this yields substantial throughput gains over vLLM, Guidance and LMQL on Llama-7B. DSPy signatures express the same contract declaratively in code, defining typed input and output fields such as name, email and intent, and compile them into prompts that enforce the schema. For narrow decisions, a small classification head on embeddings, or a contrastive model that scores candidate actions against a state embedding, avoids open-ended generation entirely.
▲ Context engineering practices for agents
Early practice focused on prompt engineering for single turns. Agents instead require context engineering: curating the system prompt, multi-turn history, long-term memories, tool outputs and attached files together. Dumping everything into the window fails twice over. Attention cost grows quadratically, and accuracy collapses. On the OOLONG benchmark, which tests reasoning and aggregation across many documents, scores for leading models including Gemini 2.5 Pro, Claude Sonnet 4 and GPT-5 fall from near 90 percent at 8k tokens to roughly 10 to 40 percent at 512k tokens. This "context rot" appears well before the advertised window limits.
Practical guidelines follow directly from the mechanics above:
- Avoid tool sprawl. On Terminal-Bench 2, a minimal harness called Pi with only read, write, edit and bash matched or beat larger frameworks such as Codex and Claude Code across Claude models.
- Retrieve, do not dump. Use an embedding model, vector search and a reranker to fetch only relevant chunks.
- Append at the end. Prepending new information shifts the position of every later token, invalidating the precomputed KV cache and adding latency. Sequential appends keep it valid.
- Benchmark formats. Whether Markdown, YAML or raw text works better for a given model and task is an empirical question.
- Guard compaction. When context fills up, systems truncate or summarize history. A safety and alignment leader at Meta reported an incident in which an agent, after compacting a very large inbox, lost the instruction to confirm with the user before deleting email and wiped the inbox. Safety-critical instructions need protection from automated pruning.
Recursive Language Models (RLMs) offer another path. The prompt is stored as a variable in an execution sandbox such as Python, and the model inspects slices, applies regex and spawns sub-queries recursively instead of reading everything at once. On a 263k-token OOLONG task, an RLM built on GPT-5-mini scored 51.1 percent, compared with 34.2 percent for GPT-5 and 23.2 percent for plain GPT-5-mini; without sub-calls it still reached 40.9 percent.
What to take away
The mechanics and the design rules line up. Sampling settings decide whether an agent is predictable or exploratory, so set low temperature for code and math and raise it only for open-ended work. Attention makes long context expensive and, past a point, unreliable, so treat the context window as a budget rather than a bin. The KV cache rewards append-only context and punishes prepending. Linear and hybrid attention trade retrieval precision for efficiency, which matters when choosing a base model for long-running agents. Developers building agents today can start by auditing their tool list, moving bulk data behind retrieval, ordering context so the cache survives, and writing an explicit test that confirms safety instructions survive compaction.


