When a team at the consulting firm AlixPartners pointed Claude Code at a post-merger pile of more than 40,000 supplier contracts, the first answer came back clean, well formatted and confident. It was also wrong in two of its five headline numbers. The agent undercounted total contract value by $800,000 because one amendment was never linked to its parent agreement, and it set a renewal notice deadline of December 1, 2026, when the contract actually required notice by November 1. Nothing in the output hinted at either problem. The case shows a pattern anyone handing bulk document analysis to an AI agent should expect: the more plausible the answer looks, the more carefully it needs to be checked, and the checking has to happen in code rather than in a prompt.
The business problem
The engagement involved a large healthcare company that had acquired a smaller specialized business. The procurement department inherited hundreds of overlapping vendors and more than 40,000 contract documents spread across three database systems that had never been connected. Nobody had a single view of what the combined company was paying any given supplier.
To protect client confidentiality, the team built a synthetic replica of the problem: Harbor Health as the acquirer, Summit Health Plan as the acquired company, and Acme Health Services as a vendor both sides used. Before the merger, Harbor spent $4.64 million a year with Acme across two contracts and Summit spent $3.06 million across two more, for a combined $7.70 million over four active contracts with no shared terms.
Procurement leadership wanted two things: to know whether combining that volume could unlock better rates or rebates, and an exact timeline for renegotiating before any contract hit an auto-renewal date. The standard was strict. Every figure had to hold up in front of the vendor, backed by a specific contract page and invoice line.
What the first run got wrong
The initial test was a direct query to Claude Code asking it to analyze the company's position with Acme. The agent correctly identified the four active contracts and produced a combined annual spend figure. But an audit against the source documents showed two serious errors:
| Metric | Agent's answer | Verified answer |
|---|---|---|
| Total current contract value | $16.7 million | About $17.5 million |
| Next notice deadline | December 1, 2026 | November 1, 2026 |
The missing $800,000 came from an amendment whose parent contract field was empty, so it never rolled up into the total. The deadline error was more dangerous. The agent based its date on a 90-day termination clause, while the auto-renewal clause elsewhere in the same contract required 120 days of notice before the March 1, 2027 expiration. Acting on the agent's date would have put the company a full month past the real cutoff and triggered an unwanted automatic renewal.
Why real contracts break naive parsing
The failures traced back to the raw data rather than to the agent's reasoning. Four edge cases came up repeatedly:
- Very long documents timed out during preprocessing and were never indexed, so they simply did not exist as far as the agent was concerned.
- Amendments were orphaned when indexing failed to map them to their master service agreement (MSA), the umbrella contract that governs the relationship. Hundreds of thousands of dollars vanished this way.
- Amendments often restate a contract's total value instead of adding to it. A naive parser that summed an original $4.0 million MSA with amendments of $6.0 million and $7.0 million arrived at $17.0 million, when the last amendment had actually reset the total to $7.0 million.
- Rate tables that spanned page breaks without repeating column headers left later pages with no context for optical character recognition (OCR), the technology that turns scanned pages into text.
Rather than asking a language model to interpret raw PDFs, the team spent two weeks building a dedicated pipeline to structure the documents before any agent touched them. Once built, it processed the full repository overnight, replacing what was estimated as a multi-week effort for a 10-person review team.
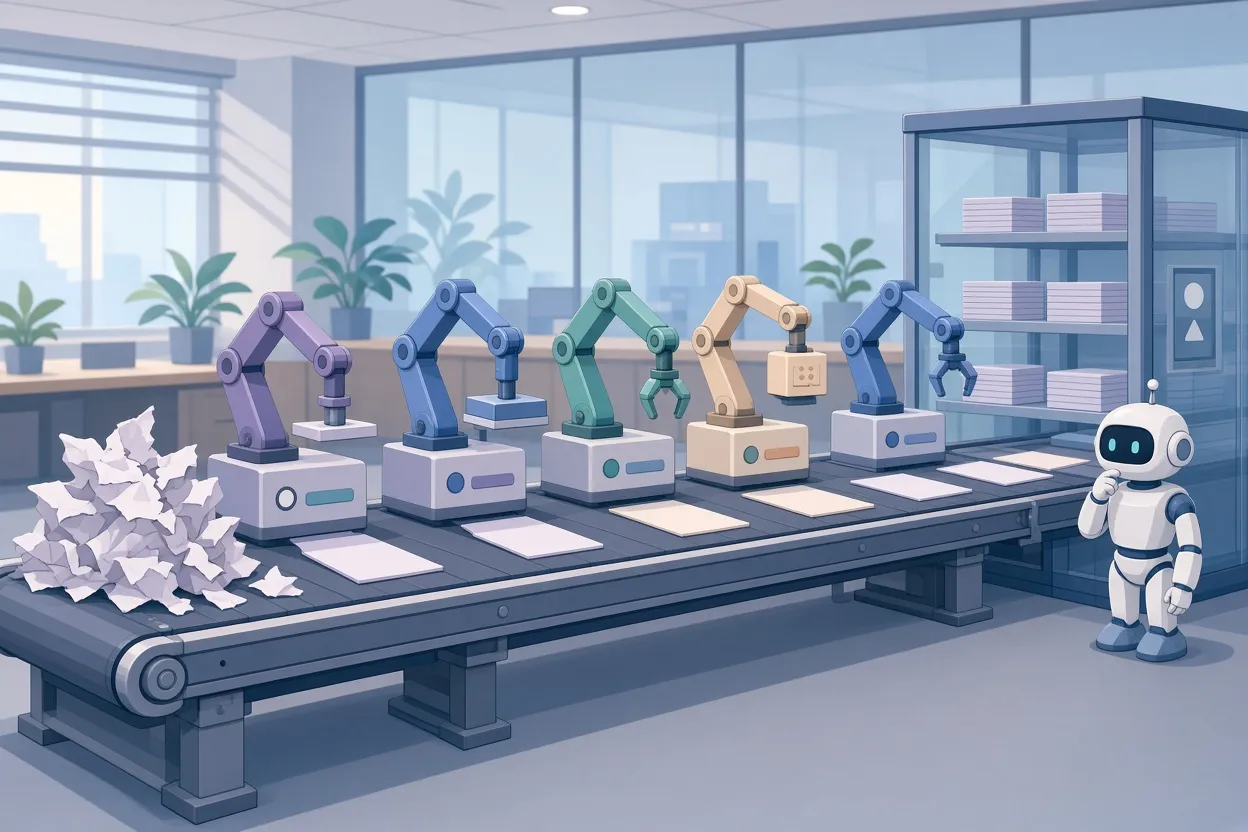
▲ Five-stage pipeline structuring contracts before analysis
The five-stage pipeline
The pipeline ran in five sequential stages:
- Preprocessing with document intelligence tooling, OCR and DSPy, a framework for programmatically optimizing prompts and language model pipelines.
- Classification of each document as an MSA, statement of work (SOW), amendment or non-disclosure agreement.
- Extraction of contract terms, rate tiers and historical spend, reconciled across the three databases through a unified crosswalk.
- Mapping of services described in SOWs into standard enterprise spend categories.
- The Claude Code analyst agent, which queries the resulting structured data through custom tools.
One detail mattered for extraction quality. Terms such as tiered volume rebates frequently appear only as charts, and OCR tends to pick up tick marks and dollar thresholds while losing the rebate percentage curve. The team converted those pages to images and used DSPy with multimodal model calls to output typed schema objects listing each spend threshold and its rebate percentage. Defining the schema up front produced more consistent results than free-form reading, though multimodal extraction techniques are changing fast and today's approach may be outdated within six to twelve months.
Structuring the data first served a second purpose: once contract terms lived in database tables, the team could verify the agent's answers with automated test scripts.
Governed access through MCP tools
With the warehouse populated, Claude Code was never allowed to touch raw tables. It saw data only through custom tools exposed over the Model Context Protocol (MCP), a standard for connecting AI agents to external tools and data. The MCP integration took about three days to build. The tools were execute_sql, list_tables, get_rate_card_page, get_amendment_chain and get_vendor_spend, and each one could carry business logic the agent would otherwise have to rediscover.
The server enforced the limits rather than trusting the prompt to do so:
- Connections were read-only.
- Each call could run exactly one SQL statement.
- Results were capped at 1,000 rows to keep the agent's context window from overflowing.
- Unauthorized operations were rejected before they reached the database.
- Every tool call and query was logged so any error could be replayed deterministically.
Claude Code was chosen as the agent because it is strong at exploring and reasoning through messy codebases, and a repository of contract and spend tables turns out to resemble one.
Five lessons from production
Codify the rules for deadlines
The December 1 error happened because the termination clause and the renewal clause sat in different parts of the contract, and relying on the agent to read both correctly compounded the error rate. The fix was a test harness that inspects the query log and flags any run that checked termination text without also checking the renewal clause. When it finds an omission, it sends the task back to the agent to extract the quoted clause, then computes the date in deterministic code instead of letting the model estimate it.
Repair the contract hierarchy
Contract lifecycle management systems are supposed to keep MSAs, SOWs and amendments linked, but in practice they are rarely well maintained. In this case, amendment INTAKE-2026-6447 renewed a Summit contract from $5.4 million to $6.2 million but had a null parent ID, so reporting ignored it. The team added a secondary Claude process that reads unlinked amendments and looks for references to a parent contract. Deterministic checks then confirm the candidate parent appeared in the search results and that the extracted quote matches the document text word for word before the link is committed. Linking amendments moved the valuation from $16.7 million to $17.4 million and finally to $17.5 million.
Make permission failures loud
During spend consolidation, the agent concluded that Summit had $0 in spend with Acme, when the real figure was $3,064,117 alongside Harbor's $4,635,096. Row-level security on Summit's invoice tables returned empty result sets without raising an error, and the agent read empty as zero. The tools were rewritten to distinguish an empty result from an access restriction and to return informative feedback when permissions block retrieval, with fallback routes to approved rollup views.
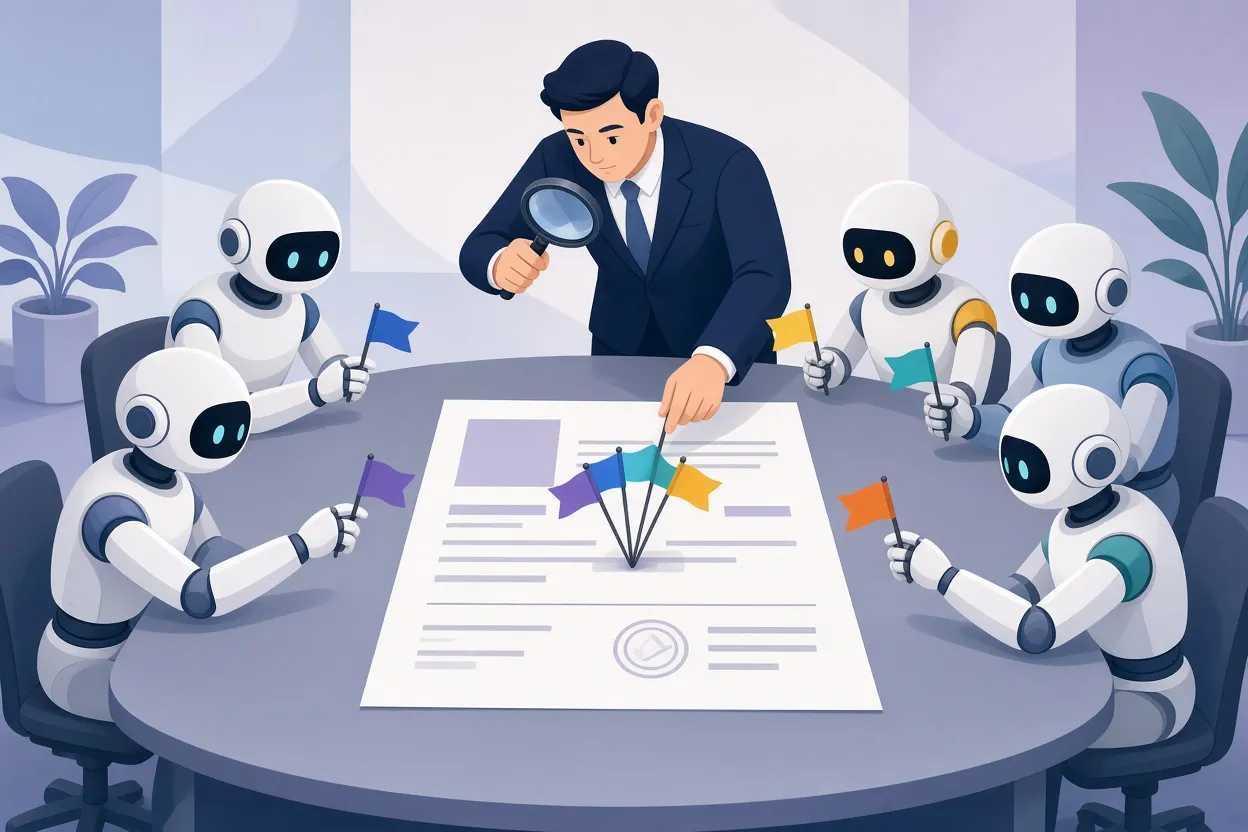
▲ Deduplicating savings claims from parallel agents
Deduplicate parallel agents
To size savings opportunities, five Claude agents ran in parallel, each on one lever: redundant services ($400,000), dead contracts ($500,000), duplicate vendors ($700,000), term arbitrage ($700,000) and rate benchmarking ($100,000), for a naive total of $2.9 million. Because the agents could not see each other's work, several claimed savings on the same invoice lines, inflating the projection by roughly $1.4 million to $1.5 million. A post-processing harness now matches invoice line IDs across findings and enforces a single-claim rule using a priority order agreed with the commercial team, so each dollar is counted once.
Feed in business context
The agent analyzed the top 30 vendor relationships in parallel, work that typically takes a human analyst about one day per vendor. Its math was sound, yet it recommended consolidating call-center providers, a project leadership had already started three months earlier. No model can see in-flight initiatives or hallway negotiations. Human analysts now annotate findings with deal context, which feeds a structured ruleset so later runs filter out initiatives already under way.
What to take from this
Two principles sum up the case. First, spending tokens and engineering time up front to structure messy data pays off, because an agent that must rediscover the schema on every run wastes reasoning and still misses things. Second, business context is not optional, no matter how large context windows become.
For teams planning bulk document analysis with an AI agent, the checklist that emerged looks like this:
- Preprocess documents into structured tables before the agent sees them; do not ask a model to aggregate numbers straight from multi-page PDFs.
- Handle restated amendment values, orphaned amendments, timeouts on long documents and headerless table continuations explicitly.
- Expose data only through read-only, single-statement, row-capped tools, and log every call.
- Put business rules such as notice-period logic into tool code, then verify from the query log that the agent retrieved every clause it needed.
- Return explicit permission errors instead of empty results so the agent cannot mistake restricted data for zero.
- Reconcile parallel agents on granular keys such as invoice line IDs with a fixed priority order.
- Keep a human in the loop to add operational context the documents do not contain.
The final architecture is simple to state: structured data, read-only tools, answers backed by traceable evidence, automated business-rule review, and a person making the judgment calls. Wrapping deterministic engineering around a probabilistic model is what turned a plausible-looking answer into a defensible one.


