Many AI agents still make routing decisions the slow way: they ask a chat model a yes-or-no question, wait for it to generate a JSON string one token at a time, and then parse the result. A newer class of models, usually called decision models, skips the text generation entirely. Given a piece of context and a fixed list of allowed answers, a decision model returns a calibrated probability for each answer in a single forward pass. That makes it faster and cheaper than a generative call, and it fits a specific job: the ambiguous judgment calls that are hard to write as rules but too small to justify a full language-model response. Products in this category now include TypeSafe AI's Jev, the OpenAI Decisions API and Cloudflare's Clef, plus an open-source model called Kev. The catch is that a probability on its own does nothing. The real engineering work lives in the thresholds, fallbacks and evaluation suites that turn a number into a reliable action.
The problem decision models solve
A concrete example makes the use case clear. One team built an internal Slack assistant that joins conversation threads. Once invoked in a thread, the assistant tried to answer every message that followed, including exchanges where two colleagues were simply thanking each other. The obvious fix, requiring people to @-mention the bot on every turn, made conversations feel clumsy and robotic. The better fix was a quick check before each reply: is this message actually addressed to the assistant, or is it meant for the humans in the thread?
That check has to be very fast and very cheap, because it runs on every message. It is also a fuzzy judgment rather than an exact rule. That combination is exactly what a decision model is built for.
How a decision model request works
A request to a decision model has three parts:
- The state: the context object the model should evaluate, such as a thread history or a support ticket.
- The questions: what you want to know about that state.
- The allowed answers: a strictly defined set of options for each question.
The model does not produce a string. It assigns probabilities to the allowed options based on the state. In Mastra, an open-source TypeScript framework for building agents that ships with classifier primitives for these models, three question types are available.
| Question type | What you provide | What you get back |
|---|---|---|
| Boolean | A true/false question | One probability that the answer is true (near 1 means strongly yes, near 0 strongly no) |
| Choice | A set of labels with criteria descriptions, such as billing, support or sales | A probability for every label |
| Score | An ordered numeric rubric, such as bug severity 0 to 2 | A probability per level plus a weighted average score |
A worked support-ticket example shows all three at once. For the message "I was charged twice this month. Can you reverse one of them?", a Boolean refund check returned 0.95. A Choice router produced probabilities across billing, support and sales. A Score question using a rubric of 0 for cosmetic, 1 for has a workaround and 2 for blocked with no workaround returned 12 percent for level 0, 72 percent for level 1 and 16 percent for level 2, for a weighted severity score of 1.03.
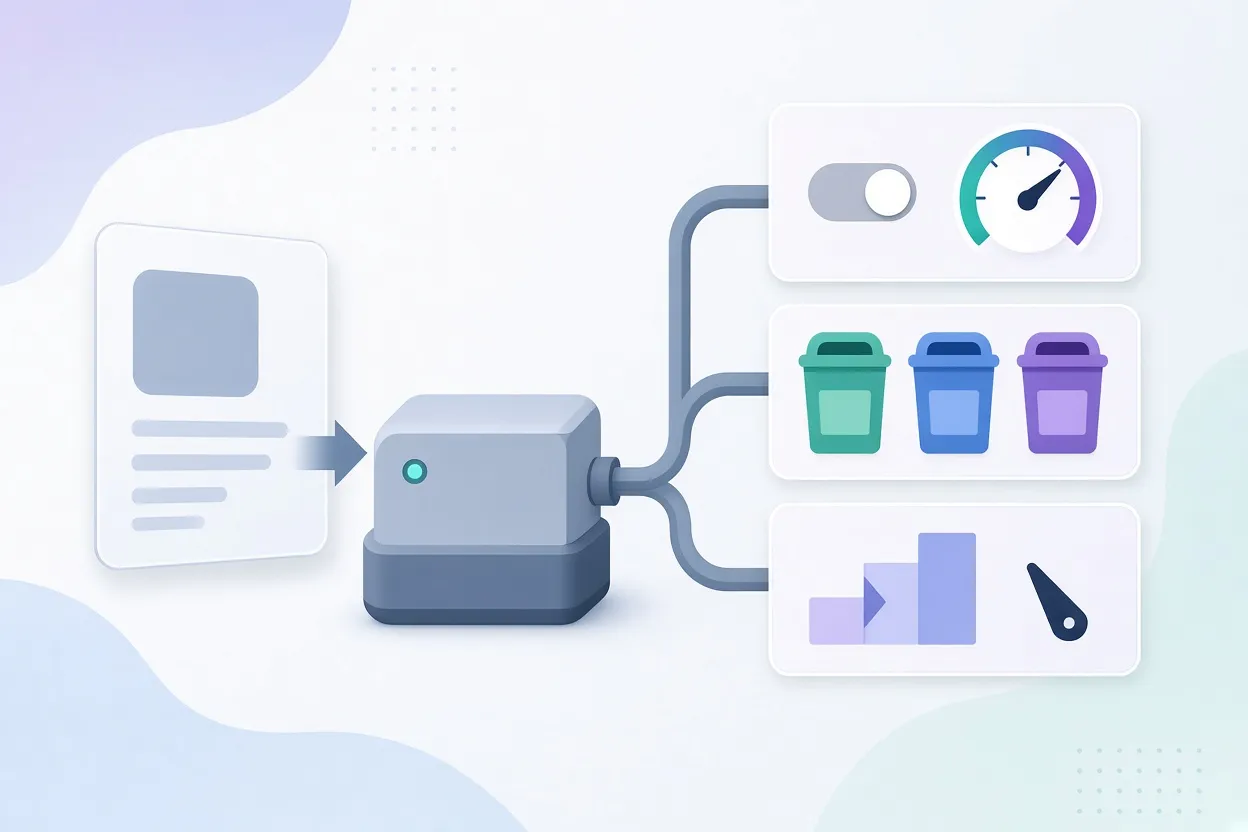
▲ Boolean, Choice and Score outputs in one call
Mastra lets you bundle Boolean, Choice and Score questions into one classifier call so the state is read once instead of across several round trips. TypeSafe's own guidance points the same way: ask every question your code might need in a single request and ignore the outputs you do not use, rather than issuing sequential conditional calls. The per-request limits differ by provider: the OpenAI Decisions API accepts up to 400 questions, Cloudflare Clef up to 64, and Jev as many as fit in its 64,000-token context window.
Why it is faster and cheaper
The speed difference comes from architecture. A standard chat model runs an autoregressive loop: compute a probability distribution over its whole vocabulary, sample one token, append it, and repeat until the full JSON answer is written and can be parsed. A decision model performs one forward pass over the state and questions and emits probabilities for the allowed categories directly. There is no sampling loop and no output text.
Because nothing is generated, output tokens are free on these APIs. Input-token prices at the time of comparison were:
| Provider | Input price per million tokens |
|---|---|
| Cloudflare Clef-flash | $0.038 |
| TypeSafe AI Jev | $0.042 |
| OpenAI Decisions API | $0.10 |
| Cloudflare Clef | $0.24 |
Which tool for which job
Decision models do not replace either generative models or ordinary code. A useful way to split application logic into three buckets:
- Generative LLMs for open-ended writing, summarization and explanation. Decision models cannot summarize, write creatively or show chain-of-thought reasoning.
- Deterministic code for exact business rules with one unequivocal answer. "Refunds over $500 need manager approval" or "only admins can delete a project" belong in an if statement, never in a probabilistic model.
- Decision models for judgment calls: detecting urgency, routing a ticket to a department, or deciding whether an assistant should speak up.
Thresholds belong in code
The decision model returns a probability. It does not act. What happens next is a line of plain application code comparing that probability to a constant. For the Slack assistant, the check is a single comparison against a threshold of 0.45: at or above it, the bot replies; below it, it stays quiet.
Keeping the threshold in code has practical advantages. You can unit test the branching logic deterministically with no live model calls. The constant lives in one named variable, so changing it is a clean one-line pull request that reviewers can track.
A single cutoff is appropriate only when a wrong call is cheap. For the Slack assistant it is: if the bot wrongly stays silent, someone mentions it again and the problem is solved in seconds. An unnecessary reply, by contrast, adds noise to the channel. That asymmetry decides where the threshold sits. The general rule is to set it higher when false positives are costly and lower when false negatives are costly.
For decisions that are not so forgiving, use two cutoffs and three bands:
- Above the upper cutoff: act automatically.
- Between the cutoffs: route to a human for review.
- Below the lower cutoff: take a safe default.
A refund-routing workflow built in Mastra illustrates this with an automation cutoff of 0.9 and a review cutoff of 0.4. A refund probability above 0.9 sends the ticket straight to the refunds team, a score between 0.4 and 0.9 goes to manual review, and anything below 0.4 goes to general support.
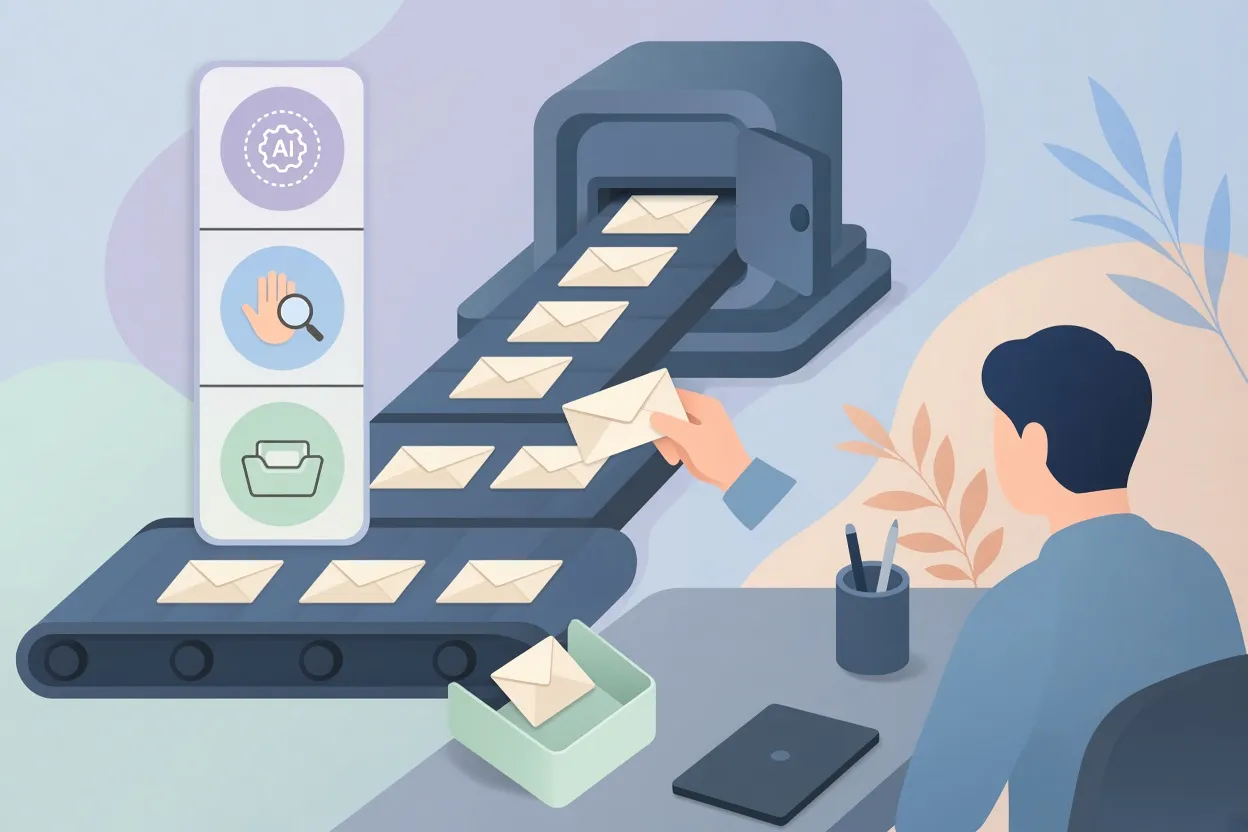
▲ Two cutoffs creating three action bands
Finding the threshold with an evaluation set
The 0.45 figure was not a guess. The team collected real Slack thread interactions and used Claude to turn them into an anonymized evaluation dataset of 16 cases: 6 where the assistant should reply and 10 where it should stay silent. One reply case, for instance, has a colleague asking the bot to add a company record, the bot explaining it cannot, and the colleague following up to request a fresh sign-in link. A no-reply case has one person asking for a summary of what shipped in the CRM that day, the bot answering, and a second person telling the first "nice one."
The evaluation runs the classifier inside a single-step Mastra workflow and scores the result with a custom scorer written in plain TypeScript: 1 if the decision matches the ground-truth label, 0 if not. No LLM-as-a-judge is involved. Mastra's runEvals pushes each labeled sample through the workflow, and a programmatic sweep tries several candidate thresholds (0.35, 0.40, 0.45, 0.50 and 0.55) to see how accuracy changes across the whole set. The same classifier scorer can also stand in for an LLM judge in larger evaluation pipelines where cost and speed matter.
The results showed a clear gap. All 10 no-reply cases scored 0.39 or lower. Five of the six reply cases scored 0.50 or higher; one outlier reply case scored 0.36. Any threshold between 0.39 and 0.50 therefore gives the same 15 out of 16 accuracy. The threshold went at 0.45, the middle of that gap, to absorb the natural variance of real production messages. Scores were checked across three runs to confirm they were stable.
These models are sensitive to wording
Two small experiments show why systematic evaluation is not optional. Renaming a single input field, from a name built around the assistant's conversation to later_replies, sent one no-reply case from 0.39 to 0.86, flipping it from silent to replying. Adding three words to the criteria instructions, a phrase that mentioned the assistant by name, dropped accuracy from 15 out of 16 to 13 out of 16. Both edits looked harmless; both were regressions and were reverted. The lesson is to run the evaluation suite in continuous integration so that prompt and schema changes cannot merge without passing the benchmark.
Running it in production
Several details matter once a decision model sits in a live system.
Work around webhook time limits. Slack requires an acknowledgment within a few seconds, which is too short for a blocking model call. The assistant acknowledges immediately and runs the classifier in an asynchronous background job. If the probability lands below 0.45, or if the classifier call fails outright, the bot stays silent and keeps the message as context for a future mention.
Use classifiers as input guardrails. In Mastra, a ClassifierProcessor can be attached to an agent to inspect incoming messages before they reach the main model. A support agent, for example, can be scoped to billing and account questions, with an onResult hook aborting off-topic requests and returning a canned message. If the classifier returns a refusal or an unhandled category, treat it as off-topic rather than letting the main model improvise.
Decide how failures behave. The errorStrategy setting controls what happens when the classifier itself fails: strict halts execution, while warn logs the error and lets the message through. For guardrails, strict is the safer choice, since an upstream failure then blocks ingestion instead of silently waving messages past.
Log decisions without logging secrets. An onDecision hook can write audit entries to a database recording the thread ID, outcome, classified answers, execution duration and turn ID, without storing the raw message text. For sensitive communications, Mastra's hideInput and hideOutput tracing options keep user text out of telemetry.
Switching providers means re-calibrating
Mastra abstracts the provider, so moving a classifier from OpenAI to TypeSafe AI's hosted Jev (jev-latest) or a self-hosted Kev (kev-9b) is a one-line configuration change using the TypeSafeAI client adapter. Kev shares an API with Jev, though running it on Cloudflare Workers AI currently needs a small proxy worker or locally hosted open weights, which makes that swap somewhat less seamless.
The one-line change is deceptive, however. Probability calibration does not transfer between models. A 0.45 from OpenAI does not mean the same thing as a 0.45 from Jev or Kev. Every provider switch, like every prompt edit, requires re-running the full evaluation suite and sweeping thresholds again to establish a new baseline.
What to take away
The division of labor is simple to state: the decision model outputs clean, calibrated probabilities over explicitly allowed answers, and application code owns everything else, including thresholds, branching, fallbacks and fail-safe defaults. For developers looking to apply this:
- Reserve decision models for fuzzy judgment calls. Put exact rules in code and open-ended text in a generative model.
- Batch every question into one classifier call so the context is read once.
- Use a single threshold only where mistakes are cheap and self-correcting; otherwise use two cutoffs with a human-review band in between.
- Build a labeled evaluation set from real cases, sweep candidate thresholds, and place the cutoff in the middle of the observed gap.
- Run the suite in CI, and re-run it before any prompt, schema or provider change ships.
- Run slow checks in background jobs for webhook-driven platforms, choose strict error handling for guardrails, and keep sensitive text out of logs and traces.
Done this way, a decision model becomes a small, testable component rather than an unpredictable oracle, and the agent built around it makes routing decisions you can test, review and trust.


