A crowded week brought new image, language and voice models at once, and hands-on testing suggests that leaderboard positions do not always match which ones are worth using. One of the most practical newcomers appears to be Krea 3, an image tool that changes only the parts of a picture you mark with a box. On the voice side, xAI’s Grok Voice 3.0 replied so quickly that a test support agent felt close to a real conversation. Meanwhile, Meta’s Muse Wonder posted the top score on a coding benchmark, a standardized test used to compare models, yet the game it built from one prompt looked rougher than those from Claude Opus 5.5 and Gemini 4 Argon.
Image models now compete on control and speed
Basic text-to-image quality across the leading models now looks largely mature, which shifts the competition to two questions: how precisely can you change one part of an image, and can you run the model on your own hardware?
Krea 3 edits only what you select
Krea 3, now in public beta on the web, performs comparably to models such as GPT Image 2.5 and Nano Banana at plain text-to-image generation. Its real strength is multi-turn editing built on bounding boxes: you draw a box over one area, type an instruction that applies only there, and the rest of the image stays untouched.
A test on a thumbnail image showing a person’s face and a smartphone went like this:
- Boxes over the phone screen and the person’s eyes, with instructions to turn the phone background blue and make the eyes red and bloodshot, returned three variations in about 10 seconds.
- A second round changed the model name on the phone from Claude Haiku 5.5 to Gemini 4 Argon and swapped the Anthropic logo for the Google logo.
- A third round rewrote the headline to “NEW MODEL!” in the same yellow stylized font and turned an embroidered emblem on a hat into a baseball logo.
The edits blended in cleanly, down to the embroidery stitching and the font weight. For anyone who adjusts thumbnails or design assets often, Krea 3 appears to produce cleaner results than chat-based image editors. Draw tight boxes so nearby details stay put, and stack several boxes with their own prompts before submitting to batch changes in one pass.
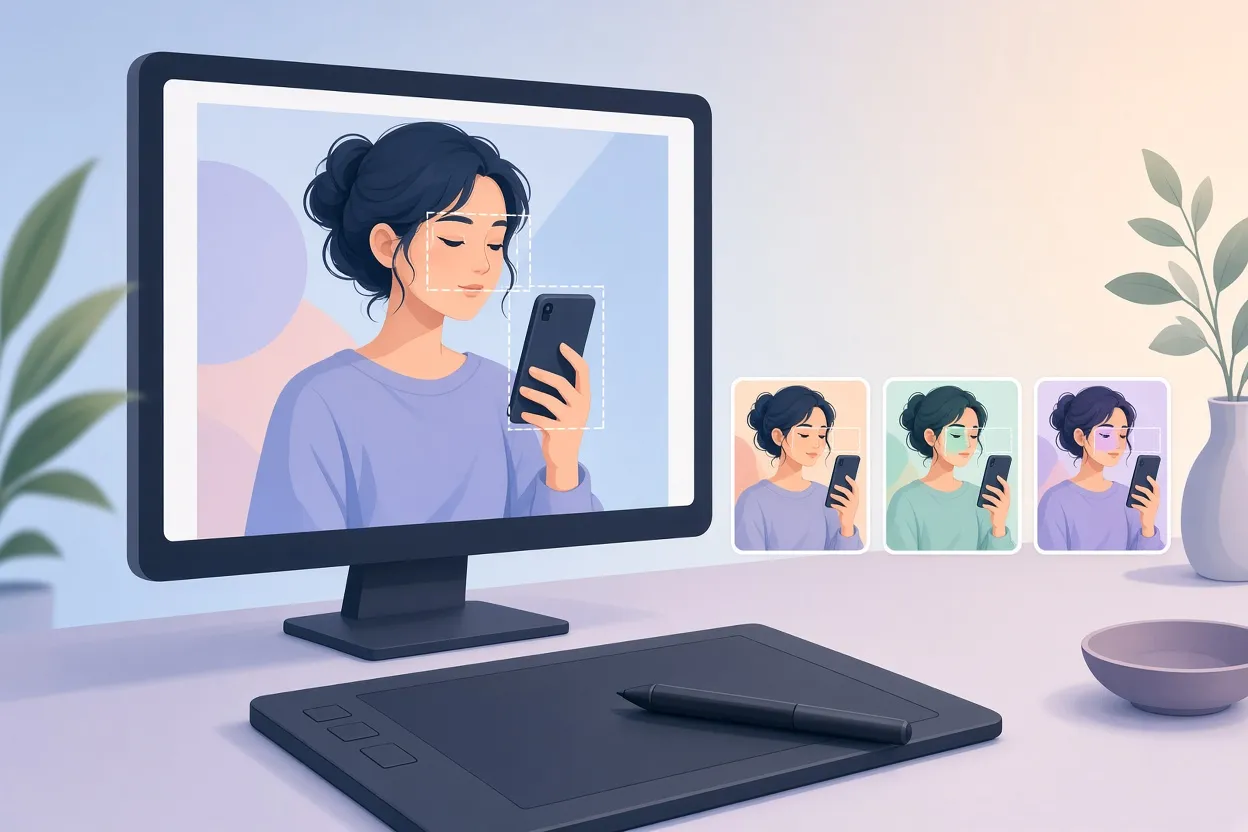
▲ Editing only the selected areas
Open-weight image models that fit a desktop GPU
Two new open-weight image models, whose trained files anyone can download and run, also arrived.
Black Forest Labs released FLUX 3 Image Klein, a 5.68-billion-parameter model for text-to-image generation, generation from multiple reference images, and image editing. The weights are on Hugging Face and can be fine-tuned, meaning further trained for a specific task, and distilled versions are tuned for lower latency.
| Hardware | Text-to-image | Image editing |
|---|---|---|
| NVIDIA DGX Spark, about $4,000 class | About 7.3 seconds | 16.2 seconds |
| NVIDIA GeForce RTX 4070, consumer GPU | 8.9 seconds | Not listed |
The consumer card trails the DGX Spark by less than two seconds per image, and for most people, running high-resolution generation and editing on an ordinary desktop likely matters more.
Alibaba added Qwen-Image-2.1-Turbo, an accelerated checkpoint of Qwen-Image-2.1 that creates and edits high-resolution images in just eight denoising steps, the passes a model makes to turn random noise into a finished picture. It gives up some fine detail but raises throughput for production work, and its samples include a dense chemistry study poster with atomic models and a reactivity table.
Both can be tried free in community Spaces on Hugging Face without downloading anything, though shared Spaces can slow down or queue requests under heavy traffic.
Grok Voice 3.0 makes response speed the feature
xAI released Grok Voice 3.0, a real-time speech-to-speech model that listens to speech and answers in speech directly. xAI claims benchmark records for latency and voice naturalness, with an overall speech benchmark score of 86.9.
xAI’s sandbox for voice agents, AI programs that work toward a goal on their own, lets you set system instructions, a greeting, response rules, interruption handling and a preset voice. A customer support agent built there for a website responded almost instantly, felt much faster than typical voice assistants and coped smoothly when interrupted. When asked, it also pulled tool recommendations and news stories straight from the site.
If you build a voice agent, spell out negative constraints in the instructions so it answers only from approved content, and tune the silence timeout and interruption thresholds so it does not talk over the person on the line.
ElevenLabs also launched Instant Soundtracks in ElevenCreative, which reads a video’s visual cues, pacing and transitions and adds matching background music and timed sound effects without manual editing.
▲ Real-time voice support without lag
Language models: the leaderboard and the output disagree
Gemini 4 Argon’s launch pricing runs through November
Google officially launched Gemini 4 Argon, first announced on September 30, across its developer APIs and Google AI Studio and for subscribers on its AI Ultra and Pro plans. It goes head-to-head with OpenAI’s GPT-6 Astra and Anthropic’s Claude Opus 5.5. Introductory API pricing is $2.00 per million input tokens and $10.00 per million output tokens, tokens being the small chunks of text a model reads and writes. That price runs through the end of November and then roughly doubles. On the Artificial Analysis Intelligence Index, Argon scores 53, five points behind Claude Opus 5.5, at a substantially lower cost per task.
In a test that asks a model to draw a caricature of a person as SVG code, a format that describes an image with shapes and lines, and has a panel of AI judges score it, Argon earned 7.6, second on the leaderboard behind GPT-6.1 Sol, in about four minutes for $0.34. Asked in a single prompt to build a 3D action game, it produced a working third-person arena game with bunny-hopping movement and upgrade cards, although the visuals were basic. Google’s engineers point to 3D-printable CAD models as an Argon strength, and a test bears that out: from one photo of a face, Argon produced an STL file for a printable bust that captured the likeness well from the front, though the side profile came out somewhat flat.
Muse Wonder leads on paper
Meta’s Muse Wonder leads the DeepSWE coding benchmark, with Muse Wonder Full at 79.0% and standard Muse Wonder at 78.8%, ahead of Claude Opus 5.5 at 74.2% and GPT-6 Astra at 74.1%. On the Artificial Analysis Intelligence Index, it scores above Gemini 4 Argon, GPT-6 Astra and Claude Fable 5.1 and ties Claude Sonnet 5.5. Its price, $4.00 per million input tokens and $20.00 per million output tokens, is comparable to Claude Opus 5.5, and its cost per task ranks fifth highest among models Artificial Analysis evaluated, slightly below Claude Opus 5.5.
In practice it was less dominant. On the same caricature test, Muse Wonder scored 6.6 and ranked 14th. Given the same 3D game prompt, it built working controls, hitboxes, jumping, camera panning and waves of enemies, but the game looked simplistic and moved stiffly next to the versions from Claude Opus 5.5 and Gemini 4 Argon. A benchmark lead does not guarantee polished output.
| Measure | Gemini 4 Argon | Muse Wonder |
|---|---|---|
| API price per million tokens | $2.00 input, $10.00 output until late November | $4.00 input, $20.00 output |
| Caricature SVG test | 7.6, 2nd place, $0.34 | 6.6, 14th place, $0.3422 |
| One-prompt 3D game | Works, basic visuals | Works, simple and stiff |
More new models, sorted by size, speed and price
- Muse Spark Open (Meta): Meta’s former top proprietary model, Muse Spark, released with open weights after Muse Wonder arrived. Meta calls it the most capable US open-weight model yet. It has 816 billion total parameters, 42 billion active per token, and a 1-million-token context window, the amount of input a model can consider at once. Optimized with Apple’s MLX framework, it runs locally across two M5 Ultra Mac Studios and leads Mistral Large 4 and Qwen 3.8 on general tasks, though it trails Kimi K3 on DeepSWE. Nearly $10,000 in Mac Studio hardware seems hard to call a consumer setup, and its caricature run scored only 3.9.
- Nemotron 3.5 Super VL (NVIDIA): a 120-billion-parameter open-weight vision-language model. It scores 26 on the Artificial Analysis index, behind DeepSeek, Qwen 3.8 and GLM 5.3, but generates roughly five times as many output tokens per second as smarter open-weight rivals, which makes it look best suited to agent workflows where low latency matters more than deep reasoning.
- MAI-Base 2 (Microsoft): a foundation model with 80 billion active parameters out of 2.8 trillion that has finished initial pre-training. Microsoft says it beats existing open-weight models on raw pre-training evaluations for coding and reasoning, but without post-training, public availability and independent testing are still pending.
- Ultramarine 1 Flash: an open model from an AI company, aimed at professional knowledge work and priced at $0.15 per million input tokens and $0.50 per million output tokens. The company claims Claude Fable 5.1-level performance in finance, law and consulting work at about one-sixtieth the cost of Fable-class models, but it is not yet on OpenRouter, so outside verification is pending.
OpenAI’s 28 Days of Shipping hits a quieter stretch
OpenAI’s “28 Days of Shipping,” a 28-day release event announced on October 4, had a noticeably quieter second week:
- Day 5: Composer Predictions in Codex suggests the next prompt from project context for Pro users.
- Day 7: the default context window for GPT-6.1 Sol in Codex grew from 272,000 to 500,000 tokens, about 84% more.
- Day 9: the ChatGPT and Codex desktop apps use about 60% less disk space.
- Day 11: added compute cuts down on capacity errors, and requests now retry in the background instead of blocking the user.
- Days 6, 8 and 10: no new features, only usage resets.
Many users dismissed Days 9 and 11 as overdue bug fixes and server maintenance rather than features, a criticism that appears justified. If you use Codex, update the desktop app and try feeding whole repositories into the larger context window.
Decision models do one job cheaply
Unlike generative models that write paragraphs, decision models evaluate an input and return a choice or a calibrated probability. Microsoft-Decision-1, fine-tuned from Qwen2.5-9B, handles yes-or-no questions, multiple choice, numerical ratings and rubric-based grading of AI responses or agent actions. Another AI company says its Nimble-v4-max reaches 85.0% accuracy on a decision benchmark, with 43% fewer errors than a competing model. Options from Microsoft, OpenAI and others appear nearly interchangeable, so the real gain is cost: for routing requests, content moderation or rubric grading, a decision model can stand in for a large language model and cut compute spending and response time.
How to use this week’s releases
In these tests, editing control, response speed and running cost appeared to separate the useful tools more than benchmark scores did. The coding leader built the less polished game, while a model with a modest intelligence score found its niche in speed. Depending on your work:
- If you edit images often, try Krea 3’s public beta with tight boxes and batched instructions.
- If you want image generation on your own PC, test FLUX 3 Image Klein or Qwen-Image-2.1-Turbo on Hugging Face Spaces before downloading.
- If API cost matters, evaluate Gemini 4 Argon on your own tasks before its introductory pricing ends in late November.
- If your agents need fast replies, consider a high-speed model such as Nemotron 3.5 Super VL, or a decision model for routing and grading.
- If you are building a voice agent, restrict answers with explicit negative constraints and tune the silence and interruption settings.
- When comparing models, look past overall leaderboards to field-specific benchmarks such as DeepSWE for coding or DiligenceBench for legal and financial work.