Gemini 4 Argon is now open to everyone. Google has released it in the Gemini app and Google AI Studio, through the Gemini API on Google Cloud, and in Antigravity. The general release comes about two weeks after Google first published the model’s benchmark results, and more than 100,000 Google employees used the model before launch. Two changes stand out. Argon can produce up to 1 million output tokens (the small chunks of text a model reads and writes) in a single generation step, and its writing has been retuned to drop the generic tone common in AI-generated text. Google also says Argon is already helping to build the next generation of Gemini models. Here is what changed, where the model is worth trying first, and how to check its work.
Two weeks of testing between benchmarks and launch
Google says it used the two weeks after its benchmark announcement to test Argon from several directions:
- Security: Google worked with cybersecurity partners, including Wiz, to find and patch vulnerabilities in critical systems with Argon.
- Staged rollout: Select enterprise customers got early access, so Google could collect production feedback and real-world edge cases.
- Specialist evaluation: Google DeepMind researchers tested the model in fields such as quantum computing, robotics, and advanced science.
- Government review: Google submitted the model to the U.S. government for safety evaluations.
- Internal testing: More than 100,000 employees used Argon, one of the largest pre-release internal tests in Google’s history.
Google describes its safety work as two layers: monitoring built into the model weights themselves, and guardrails, or filtering systems, placed around the model when it runs.
Use inside Google also spread beyond engineering to teams such as Google Cloud sales, which Google cites as evidence that Argon handles general knowledge work, not just code. Internal testers who had been tough critics of earlier checkpoints, the saved versions of a model taken during training, also turned sharply more positive.
One million output tokens in a single step
Google was first in the industry to offer a 1 million token input window. With Argon, it adds what it calls an industry-leading 1 million output tokens in a single generation step. The previous generation capped output at 64k tokens, and according to the team, that ceiling held back the model’s reasoning on hard problems.
| Previous models | Gemini 4 Argon | |
|---|---|---|
| Output cap per generation | 64k tokens | 1 million tokens |
| Producing 1 million tokens | Only by chaining several steps, as with Gemini 1.5 Flash | In one reasoning step |
The long output window is meant for hard math and open-ended scientific questions, where a model needs an extended chain of thought, the step-by-step reasoning it works through before answering. To use it, developers set reasoning effort, the control for how deeply the model thinks, to high. Argon then stretches its reasoning toward the 1 million token limit when a problem calls for deep computation.
Google co-founder Sergey Brin puts the number in human terms. By his estimate, 1 million tokens equals roughly half a million seconds of focused thought, about a week of nonstop thinking or a month of normal working hours, in response to a single query.
Writing with less AI slop
Josh Woodward, a vice president at Google Labs, says the team put heavy effort into Argon’s writing in the Gemini app. The target was AI slop, the bland, formulaic text that machines churn out: piles of bullet points, predictable filler, and stock transitions such as “to be honest.” Professional writers annotated model outputs to create high-quality reference data for training. Google says the result reads tighter and more distinctive, without the uniform voice that large language models often share.
Woodward’s own routine shows one way to use this. He records voice notes while walking or commuting, then asks Argon to act as a demanding copy editor: name the three weakest arguments, point out blind spots, and flag ideas a reader might find confusing. He sees the model as a strong editor and thinking partner, but says human judgment remains essential for original ideas.
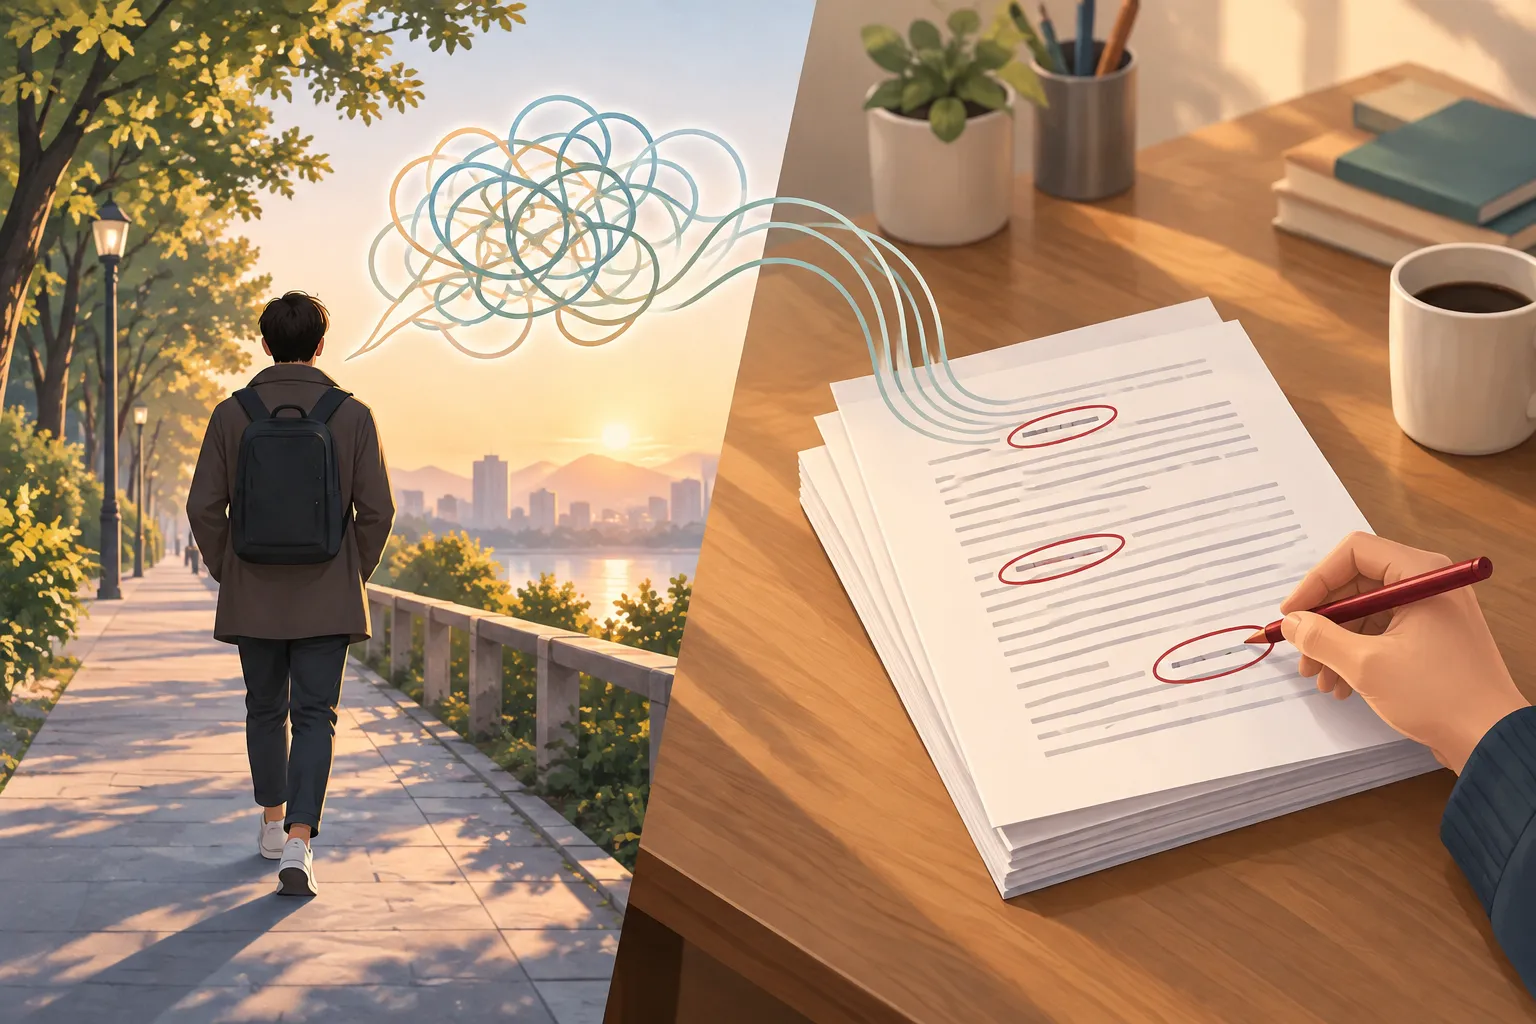
▲ Turning voice notes into edited prose
A Google DeepMind product leader uses a similar approach to ease wrist strain, speaking unscripted, rambling thoughts to the model. Earlier models tended to turn that kind of input into dense, clunky summaries, while Argon returns clean, well-organized documents. If the default style still feels formulaic, you can tell the model directly to avoid lists, filler phrases, and boilerplate structure.
How AI now helps build Gemini
The research vice president who leads post-training for Gemini calls Argon the first major release in which AI agents played an active role throughout the training pipeline. Post-training is the refinement stage that follows a model’s initial training, and agents are AI systems that carry out tasks on their own. In Argon’s case, agents:
- watched the largest training runs continuously and caught system misconfigurations
- checked whether reward signals were scaled correctly
- found bugs and proposed code patches
- screened datasets for duplicate records and inconsistencies before and during post-training
The way researchers ask for resources has changed too. Post-training teams used to request blocks of 500 or 1,000 GPU or TPU chips. Now they ask for Argon capacity measured in QPS, or queries per second, at levels such as 5, 10, or 15, because they use the model itself to generate training data for the next version. Brin adds that Argon has caught errors in its own training data, spotting flawed proofs of math theorems and producing valid counterexamples.
The cadence is fast. Google DeepMind runs training iterations every three to four weeks and evaluates candidate checkpoints every two to three weeks. Argon itself went through three to four weeks of internal post-training tests before its wider rollout. Brin points to the quick succession of Flash 3.6, 3.7, and 3.8 and says Google is now on an “RSI treadmill.” RSI stands for recursive self-improvement, a loop in which models help researchers design their own successors. Internal teams typically work several generations ahead of public models, and Brin and the post-training lead were testing later prototypes before Argon shipped.
Brin credits two drivers: a deliberate decision to speed up releases, and the practice of using current models to bootstrap the next ones. He adds that the jump between generations also included foundational research breakthroughs, which cannot be scheduled on demand. He expects the pace to keep accelerating. That is a forecast from Google’s co-founder, and the next few releases will show whether it holds.
What Argon has already done inside Google
Before launch, Google asked its teams for use cases and found Argon in wide use. Two of the projects below started from prompts alone, the plain instructions a user gives the model.
| Team or project | What Argon did |
|---|---|
| Chromium | Supported browser development and complex code tasks |
| Gemma | Drove benchmark optimizations for Gemma, Google’s open-weight model family whose trained weights are publicly released |
| Legacy migration | Helped the Antigravity team move external clients’ Fortran code to Rust |
| Data center game | Built a simulation game about running a data center, including swapping failed GPUs, from prompts alone |
| Reading app | Researched early childhood learning theory, set learning milestones, wrote the code, and deployed the front end for a team member’s young son |
| Minecraft-style game | Produced a game with cave mining and an on-screen status display from two prompts |
Fortran is decades old, yet much of the world’s legacy infrastructure still runs on it, which is why moving that code into a modern language like Rust remains valuable work.
A hardware fault engineers had lived with for months
The most striking example involved hardware. During Google’s largest training runs, machines kept falling into corrupted states. Engineers had hunted for the cause for months and had reluctantly learned to live with the failures. When one engineer handed the diagnostic problem to Argon, the model pointed to a flaw in the physical hardware itself.
The hardware team was skeptical at first and dismissed the analysis as AI slop. After engineers sat down with them and contacted the component vendor, the cause was confirmed: silent data corruption in high-bandwidth memory, or HBM. Error-correcting code (ECC), the mechanism meant to catch memory errors, had missed it. That made the model’s diagnosis decisive, and Google was able to find and isolate the affected machines across its fleet.
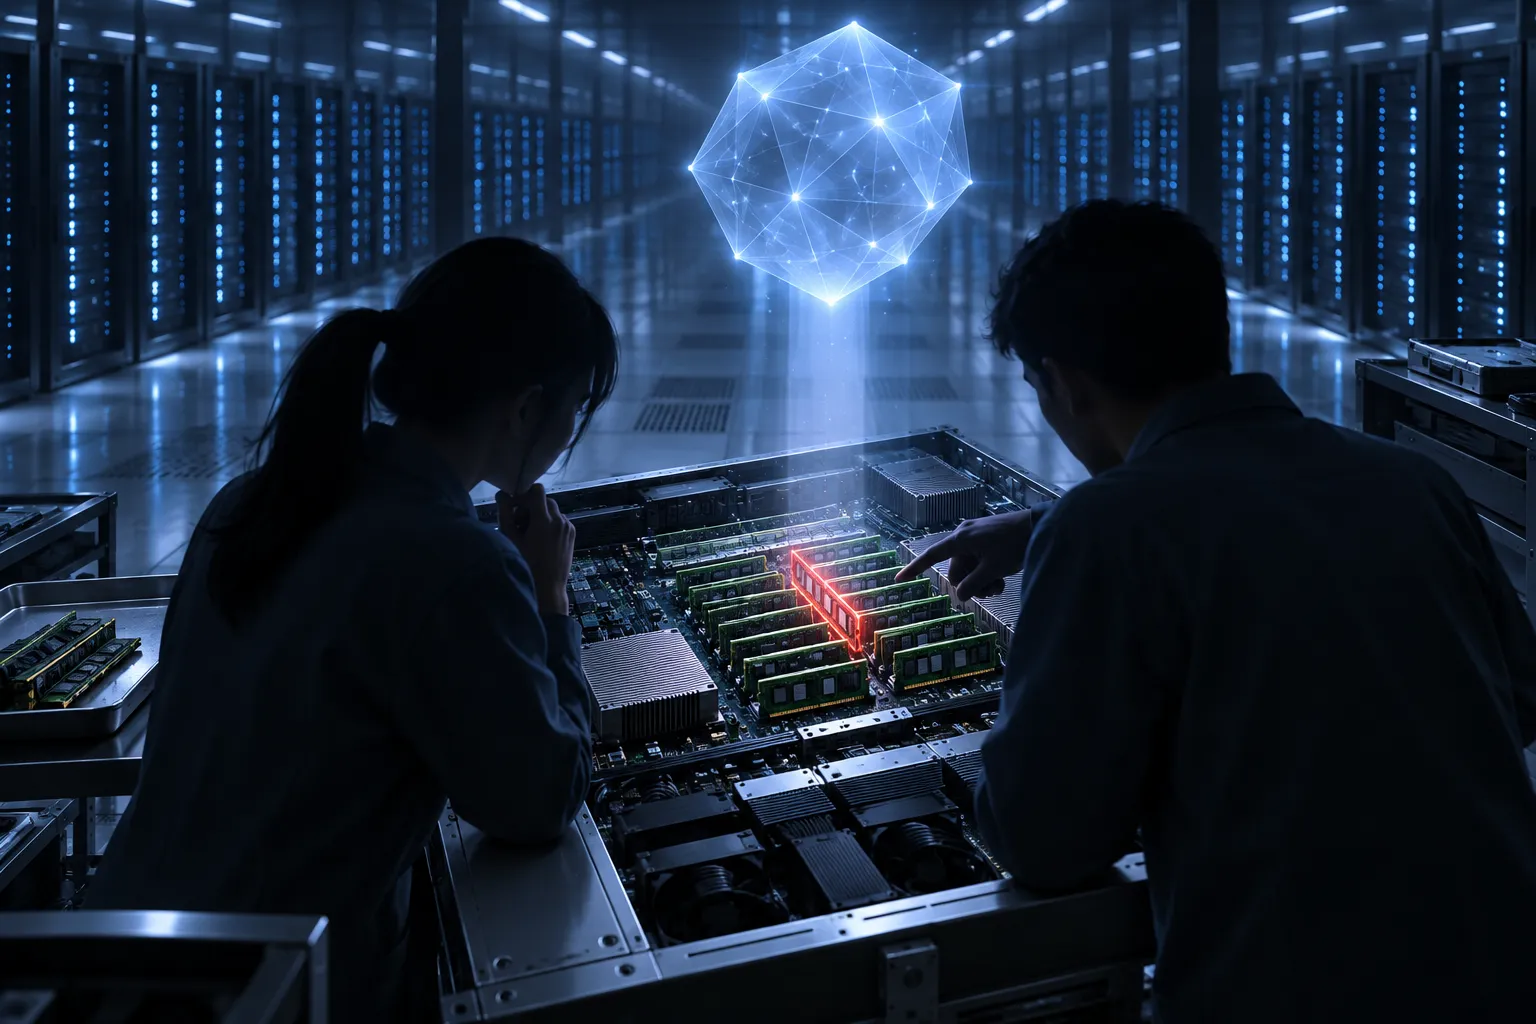
▲ Diagnosing silent memory corruption
Brin recalled a similar incident from 1998 or 1999, when none of the roughly 20 servers Google had just bought would install an operating system. After days of debugging, he found that the vendor had shipped higher-end memory that did not work with the motherboards and corrupted data every few hours. About 30 years later, an AI model tracked down a strikingly similar problem.
How to check what Argon tells you
As Argon spreads, users will face a familiar question: whether to believe a surprising or intricate result. Developers outside Google don’t have 100,000 colleagues to double-check the model’s work. Google says Argon is well grounded, avoids sycophancy (telling users what they want to hear), does not overclaim, and resists making up explanations. The team still recommends a few habits:
- Apply the same skepticism to everyone. Brin says an idea deserves the same scrutiny whether it comes from an AI model or from a human colleague.
- Let models critique each other. Models have no ego, so they readily point out flaws in another model’s output or an earlier draft. Different models offer different perspectives.
- Don’t stop at the first answer. Woodward says the bottleneck in software work is shifting from writing code to reviewing it. When an answer looks off, refine the exact prompt with a colleague and keep asking the model to dig deeper, since extra reasoning often produces a better result.
- Keep doing your own thinking. Treat the model as a brainstorming partner, read its output closely, and question anything that seems unclear or wrong. Subtle logic errors tend to surface only when someone actively checks whether the reasoning holds together, and non-experts are the most likely to miss them.
Balancing persistence, questions, and visible reasoning
Tuning a model’s behavior means trading off competing goals. A model that is too persistent can push ahead when it should change course, while one that is not persistent enough wears users out with clarifying questions.
How much reasoning to show is a similar trade-off. Detailed thought traces add transparency, but very long ones overwhelm the interface. Google gathers reactions in internal testing chat rooms and uses Argon to summarize that feedback. In the Gemini app, it has tested how long thought traces should stay visible and when users collapse or open them. Woodward says early adopters tend to study full traces, but as their trust grows they prefer short summaries. Google is also adding a dedicated thought summarizer to its developer API to condense the model’s reasoning into a brief summary.
Bottom line: what to do with Gemini 4 Argon now
Gemini 4 Argon is now open to consumers and developers. Google’s case rests on three things: much longer reasoning output, writing with less AI slop, and a model capable enough to help build its successors. The scale of testing, from 100,000 employees to a government safety review, also suggests that the bar for releasing a new model keeps rising.
- Pick an entry point. Consumers can use the Gemini app; developers can start in Google AI Studio or the Gemini API.
- Use it as an editor. Dictate rough thoughts, then ask for the three weakest arguments and any blind spots. If the prose sounds generic, tell it to avoid lists and filler.
- Save long reasoning for hard problems. Set reasoning effort to high for math proofs and deep research questions.
- Keep displayed reasoning short. If your app shows the model’s thinking, use the API’s thought summarizer.
- Verify before you trust. Have another model critique surprising results, rework the prompt, and make the final call yourself.
- Send feedback. Tell Google when the model should stop to ask clarifying questions and when it should proceed on its own assumptions, so it can tune the next version.