RunPod Flash can make an image-generation service cheaper to run by deploying Python model code without a custom Dockerfile and shutting GPU workers down when they are idle. The headline estimate of 3,000 images for $1, however, describes a warm worker handling steady traffic. A service with requests spaced far apart can incur more GPU time per image, while storage, application logic, and a two-image user experience add costs that a single-image benchmark does not capture.
What the per-image estimate measures
A commercial hosted image API is priced at roughly $0.03 to $0.04 per image in the comparison, or about 25 images for $1. The RunPod Serverless estimate uses a 24 GB GPU tier, with either an NVIDIA RTX 4090 or an Ada Generation card, at a flex rate of $1.10 per GPU hour. Dividing that rate by 3,600 gives approximately $0.0003 per billed second.
In six benchmark runs, SDXL-Turbo generated a 512-by-512 image with two inference steps in 1.10 seconds of total warm-request time. An inference step is one pass in the model’s image-generation process. Actual GPU execution took 297 milliseconds; queueing, dispatch, and Base64 image serialization accounted for about 800 milliseconds. Base64 serialization converts image data into a form that can travel in a text-based response.
| Traffic scenario | Time used in the estimate | Approximate GPU cost per image | Approximate images for $1 |
|---|---|---|---|
| Steady requests to a warm worker | 1.1 billed seconds | $0.00033 | 3,000 |
| Sparse requests with trailing idle time | 7 billed seconds | $0.002 | 500 |
| Commercial hosted API | Per-image API price | $0.03–$0.04 | 25 |
The warm figure comes from multiplying 1.1 seconds by roughly $0.0003 per second. The sparse figure assumes that six to seven seconds of trailing idle time are billed around an isolated request. Neither figure is an all-in cost to operate a SaaS product.
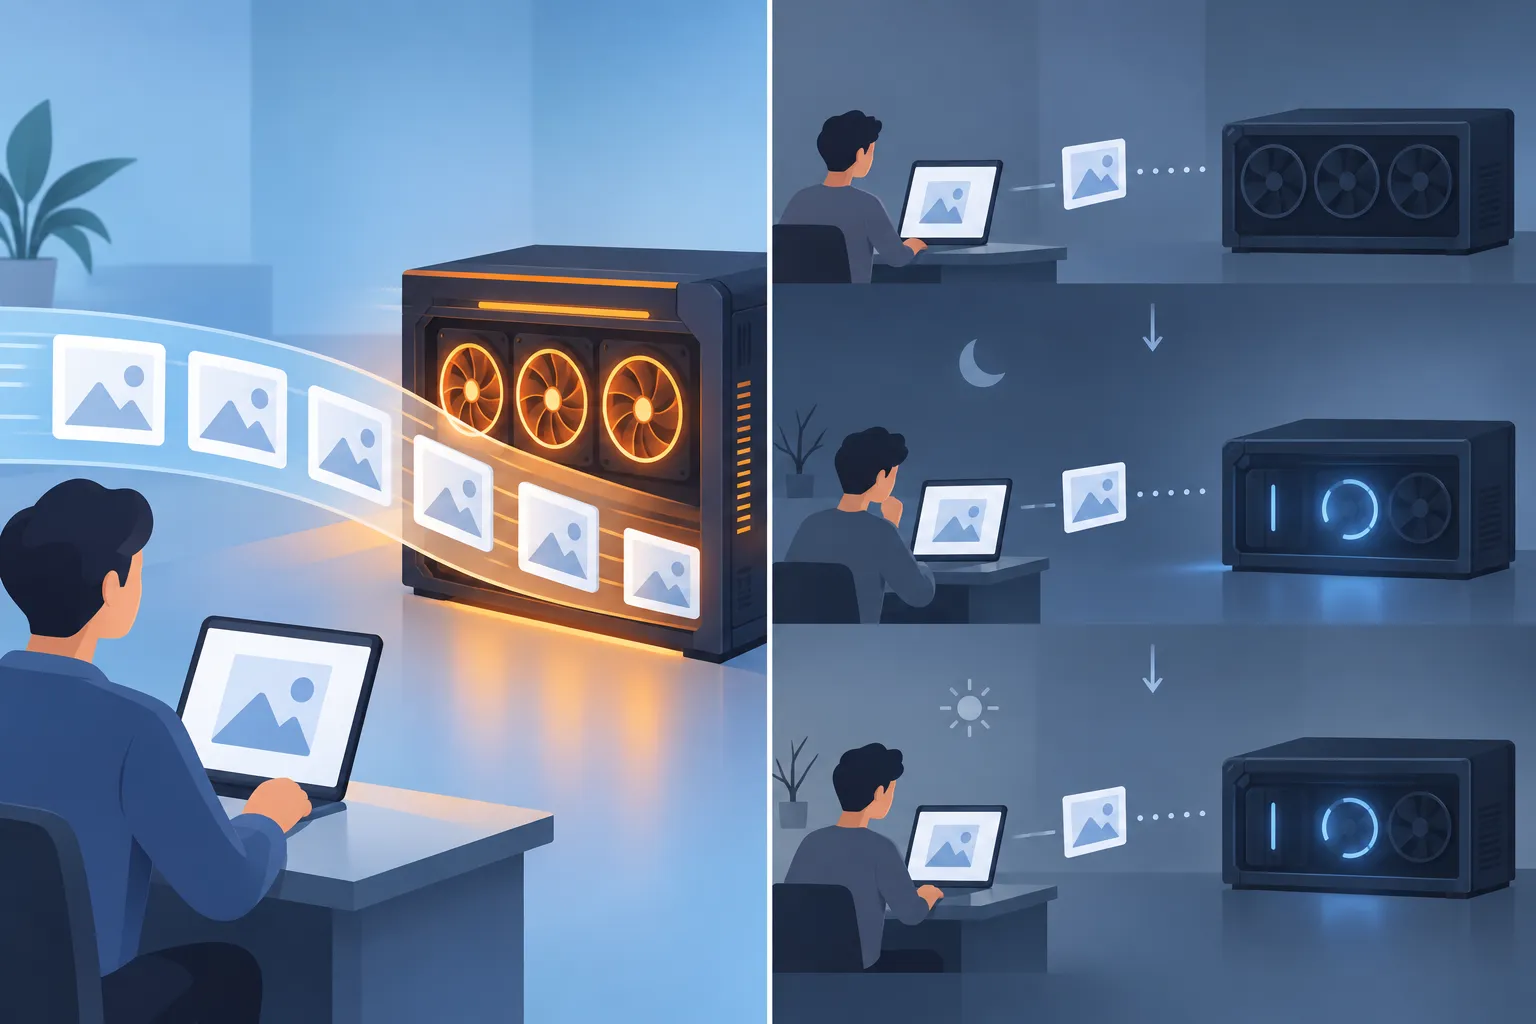
▲ Warm and isolated image requests
The difference between warm and cold behavior matters as much as the GPU rate. A measured cold start took 67 seconds end to end, including 15 seconds to load model weights into memory, while the GPU execution time remained 297 milliseconds. Model weights are the stored parameters the system needs before it can generate an image. The example worker configuration also sets a 300-second idle timeout, which determines how long a worker stays warm before shutting down. The seven-second sparse-traffic calculation should therefore be read as a pricing scenario, not as a measured bill for every request under that configuration.
Deploy the model without managing a Docker image
RunPod Flash packages a Python class into a serverless GPU endpoint: a service address that accepts generation requests. Its @endpoint decorator, a marker attached to the class in code, specifies GPU options, dependencies, scaling limits, and an idle timeout. RunPod handles the container packaging rather than requiring developers to write a Dockerfile, match CUDA components, and repeatedly push large container images.
The SDXL-Turbo worker in this example uses fewer than 40 lines of Python. It allows between zero and five workers. Zero as the minimum lets the service scale to zero—turn off GPU workers when they are no longer needed—while five caps the number that can run at once. That choice avoids the estimated cost of nearly $800 a month for a continuously running but idle 24 GB GPU. It also means a later request may face a cold start while a worker starts and loads the model.
The model pipeline loads in the class’s __init__ method, which runs when a worker starts, rather than in the handler for each request. That places the roughly 15-second weight-loading operation at worker startup instead of adding it to every generation. For the application setup, uv creates an environment and syncs dependencies; flash login authenticates, flash dev connects a local development proxy to a remote GPU, and flash deploy publishes the endpoint. Development calls are treated as cold starts, so they are not a sound basis for warm-request benchmarks.
Hardware selection remains a trade-off. A list of compatible GPUs can reduce assignment delays, but testing found inference on a Blackwell MIG slice—a portion of a GPU allocated as a separate instance—was 1.8 times slower than on an NVIDIA RTX 4090. Pinning a specific GPU favors predictable latency; allowing alternatives favors availability.
The web service still needs more than a GPU
The application design sends each image prompt to two open-weight models at the same time: SDXL-Turbo on a 24 GB GPU with two steps, and FLUX.1-schnell on a 48 GB GPU with four steps. The first completed image provides an early preview while the other request continues. A Cloudflare Worker serves a Hono API and a React single-page application built with Vite; the GPU endpoints do the generation work.
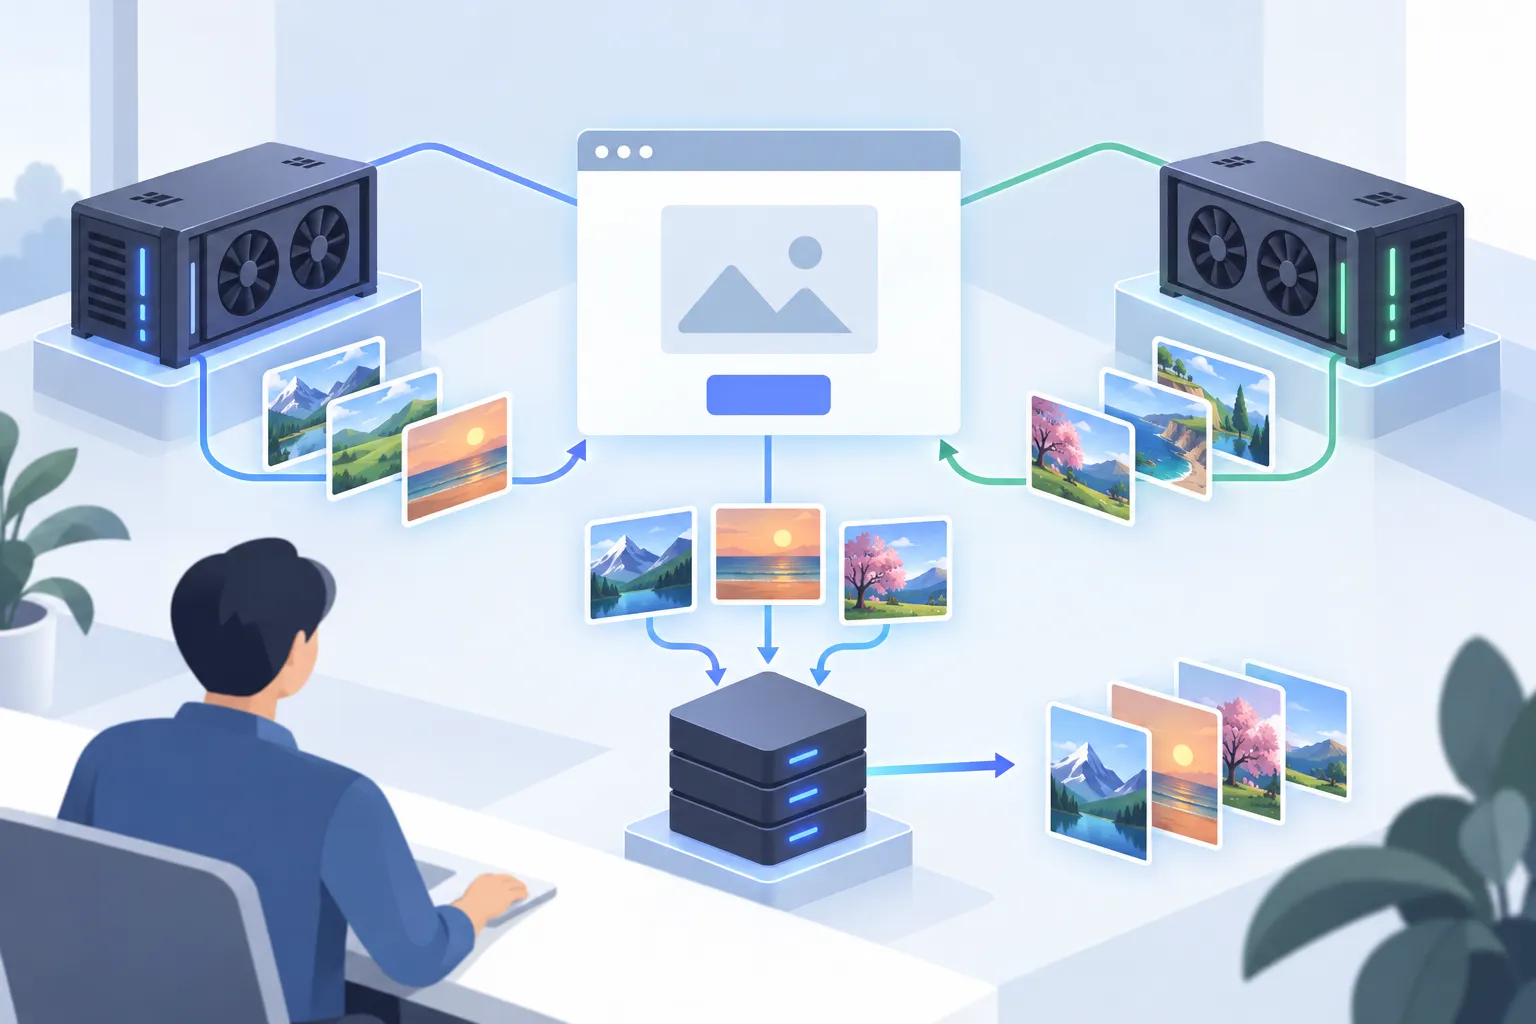
▲ Two-model image service architecture
Generated images go to Cloudflare R2 object storage, which has zero data egress fees in this setup. Cloudflare D1, a serverless SQLite database, stores account, session, battle-history, and credit records. The application keeps model identities on the server until a user submits a vote, so the initial response does not disclose which model produced either option.
Several backend choices address costs or reliability that the per-image GPU calculation leaves out:
- Long-running jobs: The backend submits asynchronous requests and polls for their status rather than waiting on a synchronous response with a 60-second timeout. That matters when a cold start must download roughly 7 GB of model weights.
- Credits: An append-only ledger records changes instead of repeatedly reading and overwriting a balance. An atomic database operation checks whether enough credits remain before recording a charge; unique Stripe event IDs prevent duplicate webhook deliveries from granting credits twice.
- Transport: With GPU execution below 300 milliseconds in the warm benchmark, reducing dispatch and image-serialization time may improve response speed more than further model tuning.
The service grants five tokens on registration and charges one token per battle. Its upgrade offers 500 tokens for $9. Because one battle requests two images, the cost of generating one image is not the cost of serving one battle. GPU execution estimates also exclude the other parts of operating the application; the token price and the per-image benchmark should not be treated as a complete profit calculation.
What to check before choosing serverless GPUs
RunPod Flash removes much of the deployment work and can eliminate idle GPU charges when workers scale to zero. Its strongest cost result depends on warm traffic, fast low-step models, and the billed time surrounding each request. Hosted APIs remain a practical choice when every request needs to avoid a cold start or when volume is small enough—such as 50 images a month at about $2 in the comparison—that configuring GPU infrastructure offers little benefit.
Before adopting this approach, measure warm and cold requests separately, check the billed idle behavior of the worker settings you actually deploy, and count both model calls in each user action. Then compare the resulting GPU bill alongside storage and application costs, rather than using the 3,000-images-per-dollar estimate as a service-wide budget.