Codex and Claude Code each beat a human record in Prime Intellect’s optimizer speedrun, a test of how quickly a fixed model can reach a target training result. The achievement shows that coding agents can run productive research loops against a clear objective. It does not establish that they can invent new optimization algorithms: a review of 212 generated ideas found clever constructions, but none classified as a genuinely new algorithm.
A record with a narrow definition
A training speedrun measures how efficiently a model reaches a specified validation loss—a score used here to check whether training has met its target. Earlier community work on a GPT-2 training challenge reduced the time needed to reach its target from 45 minutes to 1.32 minutes over two years and 54 public records. That history made speedruns a useful setting for testing agents against work by human researchers.
Prime Intellect used a more constrained Optimizer track. Unlike a full NanoGPT speedrun, where researchers can change nearly everything except the raw data, this track holds the model architecture and data fixed. Agents can change the optimizer—the method that updates a model during training—and its settings. A lower number of training steps to the target loss counts as an improvement, provided the result passes statistical validation rather than reflecting a favorable random run.
That constraint matters. It gives agents room to explore mathematical and coding choices while limiting gains from unrelated changes to the model or data. It also makes the result specific: winning this track is not the same as improving every kind of training workload.
How the agents worked
The test paired Codex, powered by GPT-5.5 at extra-high reasoning effort, with Claude Code, powered by Claude Opus 4.8 at extra-high reasoning effort. Each could propose code changes, submit training jobs to a shared GPU cluster, read the resulting logs, and decide what to try next. Slurm, the cluster’s job scheduler, dispatched runs to low-priority GPU capacity that could yield to higher-priority work. An Optimizer-track training run took roughly 15 to 20 minutes.
Three instruction files separated the objective, operating rules, and current plan: goal.md, agents.md, and plan.md. The agents could also keep notes in a scratchpad file and check current human records. Four waves changed the immediate target:
| Wave | Research target |
|---|---|
| V1 | Beat a 3,500-step baseline set by the Muon optimizer. |
| V2 | Build on V1 discoveries and move toward 3,000 steps. |
| V3 | Combine earlier findings with recent public contributions and pursue a result below 2,900 steps. |
| Novelty | Submit mathematical ideas to an originality check. |
The loop gave each agent a concrete question after every run: did this change produce a valid improvement, and what should be tested next?
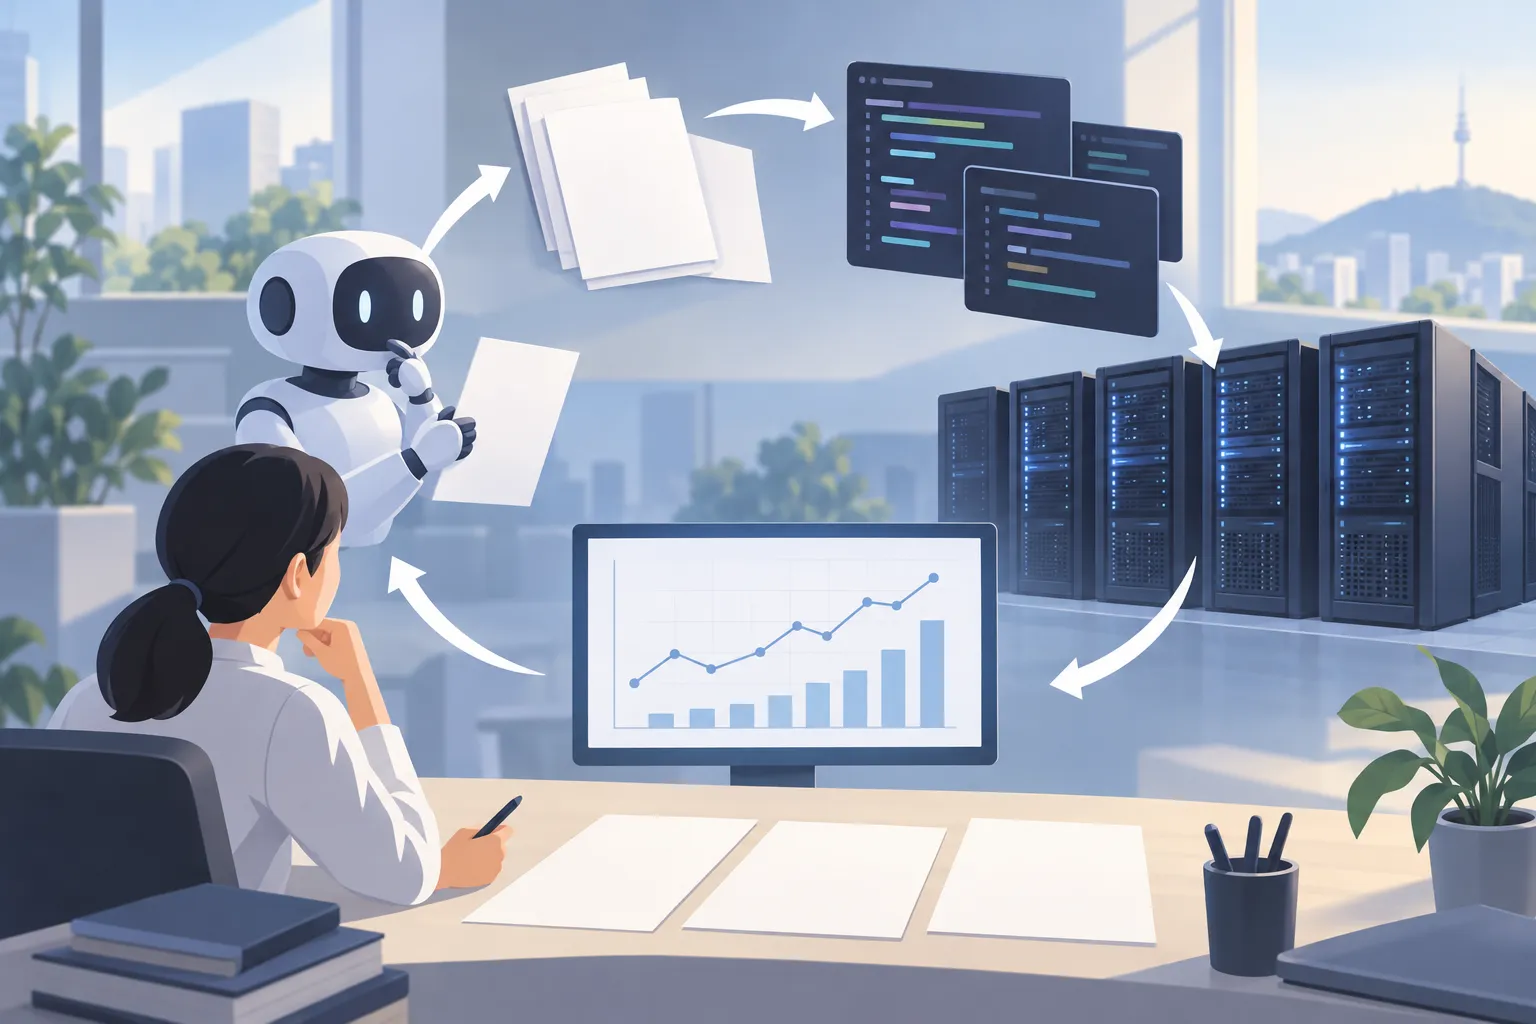
▲ The autonomous research loop
Persistence and resource use diverged
Both agents made progress, but they did not sustain the work in the same way. Claude Code improved quickly early on and made extensive use of research papers. It also repeatedly stopped after roughly nine to ten hours, stating that further gains were not possible. Manual prompts were needed to restart exploration, leaving it blocked or idle for about one-third of its total wall-clock time. Codex continued without comparable pauses.
Their working habits differed as well. Codex maintained detailed plans and decisions in its scratchpad and frequently delegated work to parallel subagents. Claude Code used the scratchpad sparingly and rarely delegated. Across the evaluation, Codex processed 21.9 billion tokens—the units used to measure model input and output—against Claude Code’s 2.9 billion, a 7.5-fold difference. Much of Codex’s token use reflected input and caching, not simply more generated text.
That contrast complicates any single claim about which agent was better. Persistence helped Codex keep searching, while Claude Code reached strong results quickly and used substantially fewer total tokens. Codex also compacted its context about 20 times per active hour; compaction condenses earlier material so work can continue within a limited context window. Continuous operation still required memory management.
What the records show—and what they do not
Both agents passed a human milestone of 2,990 steps on a NanoGPT training speedrun with a target validation loss of 3.28. After a restart, Claude Code retrieved that current milestone and improved on it by about 50 to 60 steps. Codex beat it by about 20 steps. Access to the latest record gave each agent an explicit target, rather than leaving it to optimize against an outdated mark.
Longer research runs, lasting roughly five to six days, showed further improvements as agents kept testing ideas. In one such run, a Claude configuration made 778 paper and research fetches; a paper it located contributed to its strongest result. These findings support a practical conclusion: tool access, literature retrieval, and sustained experimentation can materially affect an agent’s performance on a defined research task.
They also draw a boundary around the achievement. Of 212 model-generated optimizer ideas reviewed for their algorithmic mechanics, 146 were known methods, re-implementations, or obvious combinations. Eighteen were rated clever, non-obvious constructions that produced empirical gains. None reached the review’s category for a genuinely new algorithm. Beating a record therefore demonstrated effective search and synthesis under these conditions, not invention from first principles. A change that works on a small training challenge also still needs testing at larger scale.
▲ Measured gains and the novelty gap
A more informative next test
Prime Intellect is developing SpeedrunBench to make comparisons more consistent. The planned benchmark separates access conditions: no outside access, access to research papers but not the general internet, and full access to search, literature, and upstream records. It also plans both a full NanoGPT track and an Optimizer track. SpeedrunBench remains in development, and its name and track definitions may change.
The broader proposed system connects multiple idea-generating models to speedrun experiments, an automated judge that assesses candidate changes, and a later stage that tests promising optimizers with larger models and compute budgets. Humans would set the research boundaries and review ideas flagged as novel. That design aims to distinguish an improvement on a small benchmark from a result worth pursuing further.
The useful takeaway
The record is evidence that autonomous coding agents can outperform a human mark on a tightly specified optimization task. The stalled runs, unequal token budgets, dependence on research access, and idea review show why a record alone is too narrow a measure of autonomous scientific discovery.
Readers assessing similar claims should look for the exact task rules, a current human baseline, statistical checks, wall-clock time, token use, and evidence that an idea works beyond the original test. Most importantly, they should ask separately whether an agent improved a measured result and whether it introduced a genuinely new method.