Jev can give Claude Code a way to delegate narrow decisions without asking a language model to write a full response each time. Six open-source projects show what that approach looks like in interfaces, browsers, page filtering, verification, and transcript analysis. A seventh resource is a directory of builds rather than a repository. The useful question is not whether Jev replaces Claude Code, but which tasks need a quick, structured judgment.
A decision layer, not another writing assistant
Jev, developed by TypeSafe AI, maps an input to predefined choices, yes-or-no outputs, or probabilities. That differs from models that generate an answer word by word. The distinction makes Jev suitable for repeated classification and selection, while Claude Code remains the place for broader reasoning and planning. The projects below illustrate different ways to divide that work; only the Model Context Protocol project is presented as a direct connection to Claude Code.
Interfaces that respond while you type or speak
The shapeshift repository turns a text input into a component that matches the apparent intent. It evaluates 14 typed questions as the user enters text. A request for a 25-minute timer becomes an interactive countdown; an event request becomes an editable calendar card. A calculation such as 500/5 produces a card showing 100. The practical idea is an interface that chooses its next form before the user navigates a menu.
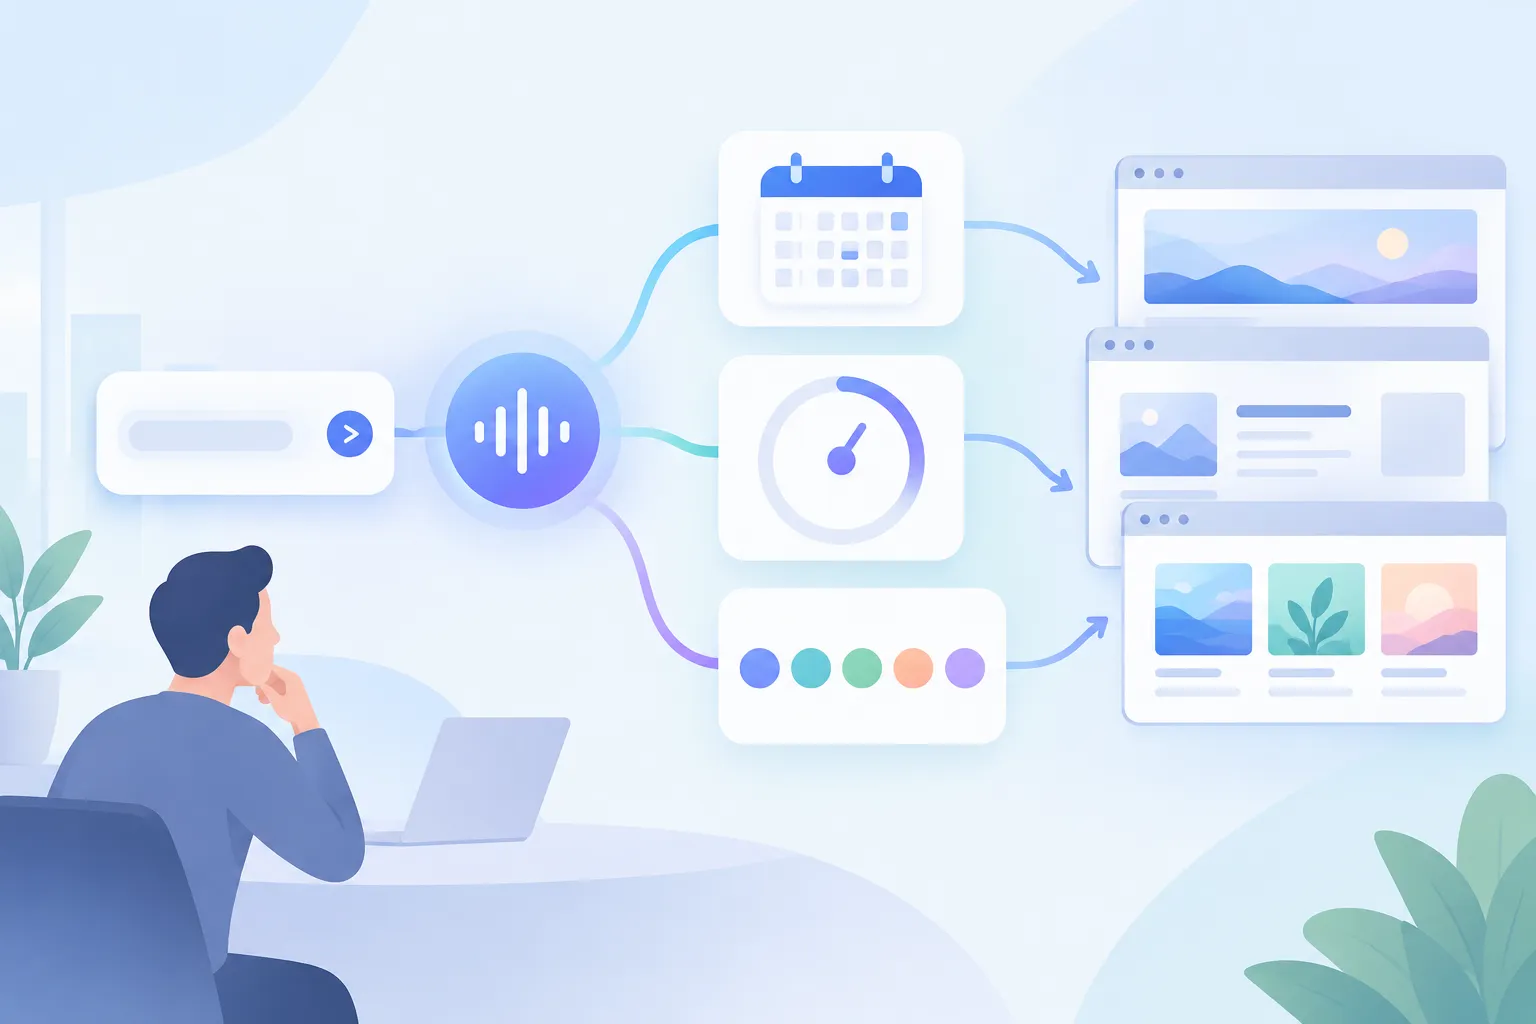
▲ Adaptive input and voice browsing
The jev-voice-browser repository applies a similar idea to speech. It evaluates streaming words and uses Playwright, a browser automation tool, to act on the inferred command. A demonstration navigates between Wikipedia pages through spoken requests. Its reported intent latency is roughly 250 to 350 milliseconds per spoken word, so the browser can begin responding before a complete sentence ends. That makes it a useful example for developers exploring voice-driven navigation rather than a general-purpose conversational assistant.
Browser choices and page filtering
The typesafe-computer-use repository selects interface targets using OCR, which reads text from a screen, and DOM trees, which represent a web page’s structure. It uses the resulting element locations instead of relying on a full screenshot for every decision. A ticket-checkout example shows it identifying ticket options and navigating page controls. The reported comparison is specific to the computer-use test, not a measured speedup for every Jev application.
| Measure in the reported test | typesafe-computer-use with Jev |
Claude Opus 5 screenshot-based use |
|---|---|---|
| Decision or step latency | 0.13–0.38 seconds | 5.2–5.5 seconds |
| Cost of a 12-step task | $0.003 | $0.50 |
For this kind of workflow, the division of labor is straightforward: a reasoning model can decide what the task requires, while Jev selects among identified interface elements. The reported figures describe that test case, not a cost or timing developers should assume for their own tasks.
▲ Browser selection and content screening
The typesafe-adblock repository tests a different browser task. Its Chrome extension examines DOM blocks as pages render, asks Jev whether each block appears to be an advertisement, and removes blocks classified with high probability. It stripped banner elements from Speedtest and Fandom pages in demonstrations. This is an experimental use of live page classification; established rule-based ad blockers remain more efficient for ordinary ad blocking.
Give Claude Code smaller verification tasks
The jev-mcp repository is the clearest direct pairing with Claude Code. MCP, or Model Context Protocol, lets an assistant use external tools. This package exposes 11 Jev judgment tools, including jev_screen for screening, jev_extract for extraction, and jev_verify for checking claims against supplied material. Their reported response times range from 150 to 500 milliseconds.
In one pricing-page test, Claude Code used Jev to screen external page content before relying on it. The screening tool flagged a hidden attempt to redirect the assistant with a reported probability of 0.99, and the workflow did not follow that instruction. Jev then checked four pricing claims against extracted page content, returning verified or contradicted judgments. The two Jev calls together cost $0.000062 in that test. A probability score is a tool output, not a guarantee that every future page or claim will be classified correctly.
This pattern may be useful wherever an agent must assess many pieces of outside material: screen the material, extract what matters, and verify narrow claims before asking a broader reasoning model to use them. The repository can be installed as an MCP server for Claude Code or Codex with a TypeSafe API key.
Score transcripts and explore other builds
The jevmeter repository combines Whisper or Faster-Whisper, tools that turn speech into text, with sentence-by-sentence Jev judgments. It displays scores for categories such as factual-claim accuracy, evasion, self-contradiction, emotional appeal, and dodged questions. In a presidential-debate test, it made 1,191 Jev calls across about 1.18 million input tokens. The reported API cost was $0.0497, with a median response time of 0.4 seconds per call. Those are figures from one demonstration, not proof that a score establishes whether any particular speaker was truthful. The same method could be explored for analyzing spoken cues in sales broadcasts, though a cue and a change in conversions would still need careful interpretation.
The seventh resource is a community directory listing 551 Jev builds and use cases, not a seventh code repository. Its categories include agents and browsers, games and real-time systems, content and growth, and tools and apps. It offers a way to look for a task pattern that fits an existing project rather than starting with a speed claim.
Choose one decision to delegate
Start with a bounded task in a workflow you already understand: selecting a page element, classifying a block of content, or checking a claim against extracted text. If Claude Code is already part of that workflow, jev-mcp offers the most direct starting point; the other repositories illustrate interface and browser designs to examine. Keep broad planning with the reasoning model, and measure accuracy, latency, and cost on your own task before expanding the Jev decision layer.