Apple’s claim that the M5 Ultra is up to four times faster than the M3 Ultra has a clear counterpart in local AI tests: some large language models begin responding about four times sooner than they do on the older chip. That does not mean every answer arrives four times faster. Once a model starts writing, the measured gain is usually closer to 1.5 to 1.7 times. For anyone considering a Mac Studio upgrade, the difference between those two stages matters more than a single headline speed figure.
What the two Mac Studios were running
The comparisons used Mac Studio systems as headless local AI servers, meaning they ran without a directly attached display or keyboard. The models ran offline, without internet access or cloud API calls. The M3 Ultra had 512GB of unified memory, while the M5 Ultra had 256GB, so these were not identical memory configurations.
Both machines had 80 GPU cores. The M5 Ultra added a Neural Accelerator inside each GPU core and raised memory bandwidth—the rate at which data moves between memory and the processor—from 819 GB/s to 1.2 TB/s. It also had 36 CPU cores, compared with 32 on the M3 Ultra. Those hardware changes provide context for the results, but the tests show different gains for different parts of an AI task.
A faster first token is not faster writing at the same rate
Time to first token, or TTFT, measures how long a model takes to begin its reply after receiving a prompt. Token generation speed measures how quickly it produces the subsequent pieces of text. The main language-model comparisons used prompts with 32,000 tokens, where a token is a piece of text the model processes. The Qwen models used 4-bit versions, which store their weights in a compact form.
| Local model | First token: M5 Ultra vs. M3 Ultra | Generation: M5 Ultra vs. M3 Ultra |
|---|---|---|
| Qwen3.8 27B, 4-bit | 21.66s vs. 82.85s | 43.3 vs. 28.1 tokens/s |
| Qwen3 14B, 4-bit | 14.43s vs. 57.25s | 55.8 vs. 32.6 tokens/s |
| Qwen3.6 35B-A3B, 4-bit | 7.25s vs. 17.5s | 110.2 vs. 73.5 tokens/s |
| Qwen3.5 122B-A10B, 4-bit | 14.58s vs. 46.9s | 65.8 vs. 43.1 tokens/s |
| Gemma 4 31B, 16-bit | 26.7s vs. 110.4s | 13.6 vs. 9.0 tokens/s |
The Qwen3 14B test came closest to Apple’s fourfold figure: its first-token wait fell from 57.25 to 14.43 seconds. The Qwen3.8 27B test, which summarized John Stuart Mill’s On Liberty, improved by about 3.8 times at that stage. Gemma 4 31B exceeded fourfold in its first-token result, yet its rate of writing the rest of the answer improved by only about 1.5 times.
A long prompt creates substantial work before the first token. Generating the reply is more sequential: for each new token, the system must repeatedly read model weights from unified memory. The Qwen3.8 27B model’s weights occupy about 15GB in this test. That helps explain why its generation rate rose by about 1.5 times, closer to the increase in memory bandwidth than to its first-token improvement.
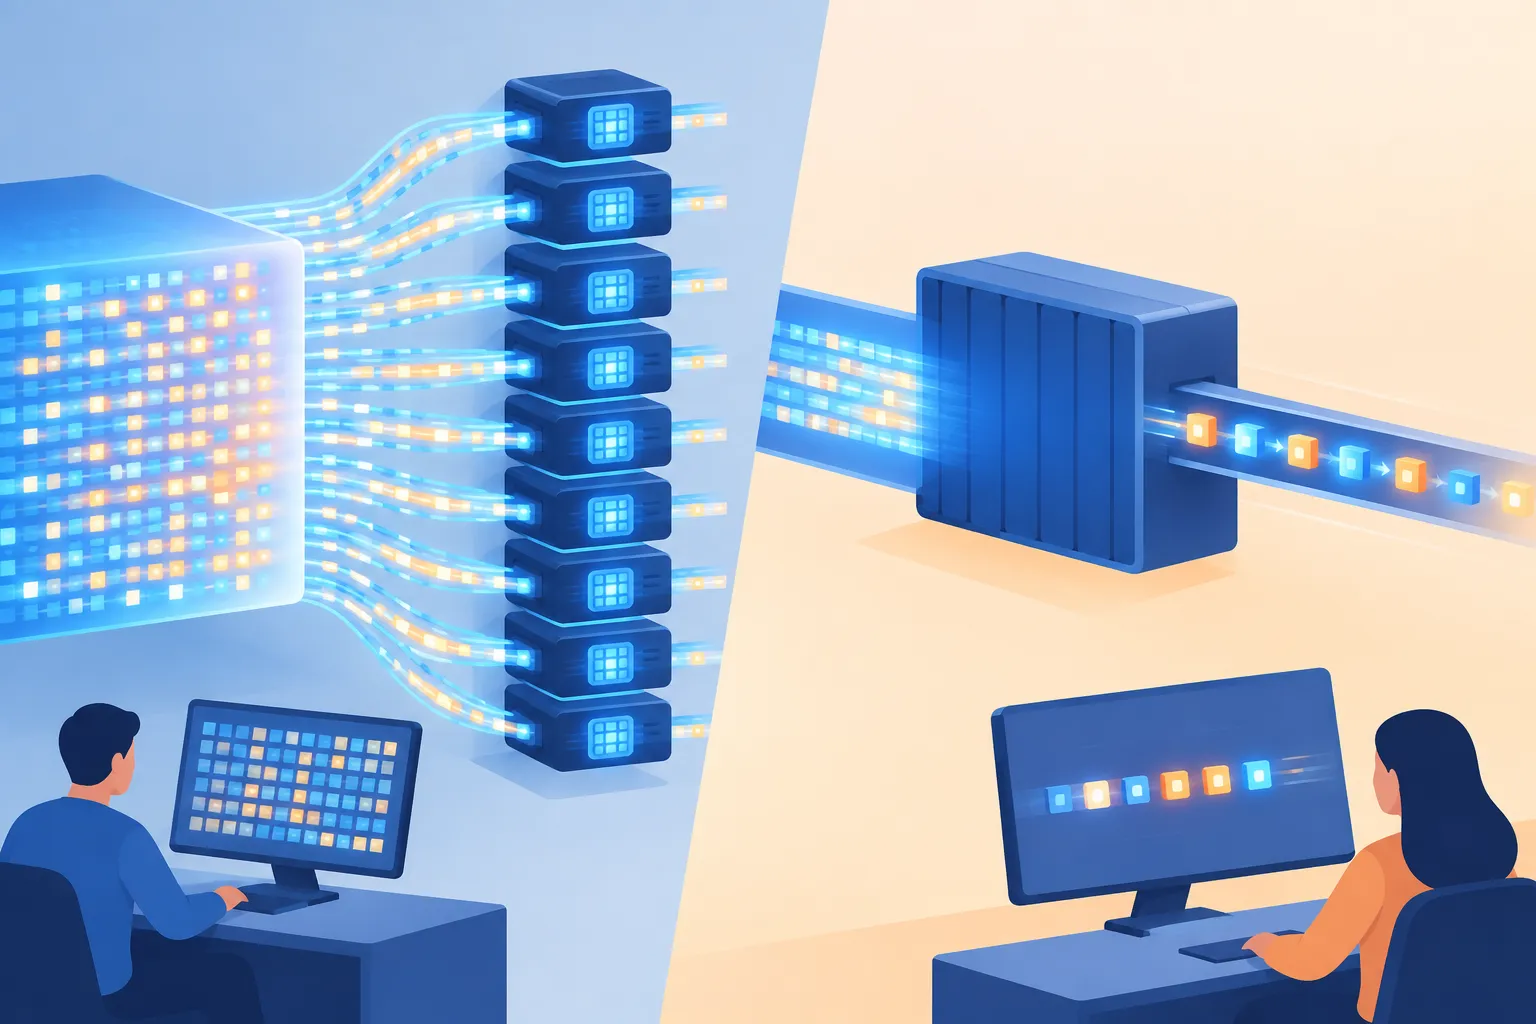
▲ Prompt processing versus token generation
The practical distinction is output length. If a task supplies a large document and asks for a short answer, cutting the initial wait can dominate the experience. If it asks for a long response, the smaller improvement in sustained generation matters more. In the Qwen3 14B test, total time fell from 67.9 to 21.6 seconds; that overall result reflects both stages, not a fourfold gain in every part of the task.
Audio and media work show different gains
Language models were only part of the offline workload. Local transcription, footage analysis, image generation and video generation all ran faster on the M5 Ultra, but by varying amounts. These tests are useful for judging a production workflow more precisely than a single LLM benchmark.
▲ Local media production workflows
For speech-to-text, Whisper ran through MLX, a framework used here to run models on Apple Silicon. On a 13.8-minute audio sample, Whisper Large-v3 finished in 11.4 seconds on the M5 Ultra versus 20.2 seconds on the M3 Ultra. Whisper Turbo took 3.1 versus 7.1 seconds. A longer, 2-hour-and-5-minute recording showed the same pattern:
| Transcription model | M5 Ultra | M3 Ultra |
|---|---|---|
| Whisper Large-v3 | 89.4s | 152.6s |
| Whisper Turbo | 24.4s | 56.2s |
Turbo’s speed could make it useful for draft transcripts of lengthy recordings. These timing tests do not establish that its transcript quality matches Large-v3 for every recording, so speed and output quality remain separate considerations.
For footage analysis, Qwen3-VL 32B processed 60 seconds of silent video sampled at one frame per second. It identified visible details, including a person and desk objects, in 22.9 seconds on the M5 Ultra versus 60.3 seconds on the M3 Ultra. That is a 2.6-times speed advantage for this local video-logging task.
In image generation, FLUX.2 klein 4B produced a 1024-by-1024 forest illustration in 2.6 seconds on the M5 Ultra versus 10.2 seconds on the M3 Ultra. A revised, photorealistic version took 2.2 versus 7.0 seconds. Using an image as input, LTX-2.5 22B generated a short animated clip in 17.5 versus 30.2 seconds. A larger clip took 19.9 versus 50.5 seconds. The spread reinforces the central point: a fourfold improvement in one task does not carry over to every local AI operation.
Automation and the price decision
The M5 Ultra also handled workflows that involved more than one model response. A local agent used Qwen3.8 27B with a context window of 131,131 tokens (the amount of material the model can consider at once) and quickly answered questions drawing on more than 24,000 tokens of personalized context from earlier sessions. In a separate classification test covering 300 text questions, the M5 Ultra finished in 23.5 seconds versus 33.4 seconds on the M3 Ultra. Both machines produced the same reported accuracy scores: 91.5% for spam detection and 66% for banking intent.
An editing agent connected a local model to DaVinci Resolve Studio through Model Context Protocol (MCP), a way for an AI system to use external tools. It read a transcript and made timeline cuts to remove false starts and hesitations. The automation produced an edited cut, but planning and executing cuts across the project took roughly 13 minutes. Faster model inference did not make the whole editing workflow instantaneous.
The tested M5 Ultra configuration—with an 80-core GPU, 256GB of unified memory and an 8TB SSD—was priced at $14,299. Its offline operation avoids cloud API calls for the tasks it can handle, but that price is the cost of this particular configuration, not evidence that every user would save money. The memory difference also matters: buyers running especially large models should compare their capacity needs with the 256GB test machine, not assume that speed alone settles the choice.
How to judge the upgrade
The M5 Ultra’s strongest case is for frequent local work with long prompts or repeated media-processing jobs. Its first-token gains can substantially shorten the wait before an LLM responds, and its transcription and footage-analysis results could save time across large batches. Users who mainly want longer answers to stream faster should expect the more modest generation gains shown here. Before upgrading, identify the models that fit your memory needs, measure how much of your own workload is prompt processing versus token generation, and compare those time savings with the cost of the configuration you would actually buy.