A self-improving AI agent does not get smarter by retraining its language model. The model's weights stay frozen. What changes is everything wrapped around the model: the instructions, the tools, the memory rules and the orchestration code that decides what happens next. Engineers call that wrapper the agent harness, and a self-improving agent is one that uses evidence from its own past runs to propose, test and keep changes to that harness. Building one safely comes down to a handful of design decisions: splitting the work into an inner loop and an outer loop, versioning every change, limiting what the agent may touch, and keeping the tests that judge it entirely out of its reach.
The topic has drawn attention beyond engineering circles. Eric Schmidt, Reid Hoffman and Demis Hassabis all raised recursive self-improving systems at the Masters of Scale Summit. The architecture behind the idea, however, is more concrete and more bounded than the phrase suggests.
Where a plain LLM call ends and a self-improving agent begins
The first step is to separate two things that often get lumped together. The model, or LLM, generates text and decides when to request a tool call. The agent is the larger system around it: system instructions, tool definitions, memory stores and the code that moves a task from one step to the next. Changing the agent means changing that harness, and the discipline of designing it is sometimes called harness engineering.
The second step is to distinguish two kinds of correction. When an agent notices a mistake in its draft, rewrites the answer and finishes the task, that is in-task error correction. Nothing carries over. A self-improving agent instead makes a persistent, cross-task change: it stores a reusable debugging procedure, rewrites a system instruction or adjusts how it searches a codebase, so that Task A, Task B and Task C all run differently from then on.
Improvement becomes recursive when the system being upgraded helps formulate, validate and apply its own next iteration. A useful analogy is a scientist who designs a better laboratory method and then uses that method to run the next round of experiments.
One caveat belongs up front. Recursive improvement does not mean unbounded growth in intelligence. Left uncontrolled, these loops can plateau, run up spiraling compute costs, or keep reinforcing the same mistake.
Two loops, one optimization problem
The core structure is two tightly coupled cycles.
| Loop | What it does | What it produces |
|---|---|---|
| Inner loop | Reads the task, chooses an action, calls a tool, observes the result, continues | A task result, such as a bug fix |
| Outer loop | Studies the inner loop's execution history, diagnoses shortcomings, proposes a revised agent | A new version of the agent |
Mathematically this is bilevel optimization: an outer objective chooses settings that govern an inner optimization problem. The outer level picks the configuration and evaluates the outcome; the inner level runs with that configuration held fixed.
The parts the architecture cannot skip
Five components make the two loops workable in practice.
- A versioned agent specification. Every instruction, tool definition, memory rule and setting is tracked across versions. Without this, nobody can say which change caused a shift in a metric.
- A bounded modification space. The agent may refactor safe operational logic, such as how it searches a repository, but it is explicitly barred from touching access controls, authentication logic or other security-sensitive code.
- Granular evidence logs. The outer loop needs tool call records, the files the agent retrieved, unit and integration test failure traces, token costs and final task outcomes.
- Evaluation criteria. For a coding agent, the standard typically requires fixing the target defect, keeping the existing regression suite green, and finishing within compute and time budgets.
- A selection rule and a version archive. Useful branches are stored with their evidence, and rollbacks are always possible. The newest version is not assumed to be the best starting point for every problem.
The modification process itself follows the scientific method. A proposed change is a hypothesis. Running the modified agent is the experiment. An automated evaluator grades the result against predefined standards, and the selection rule decides whether the branch is kept.
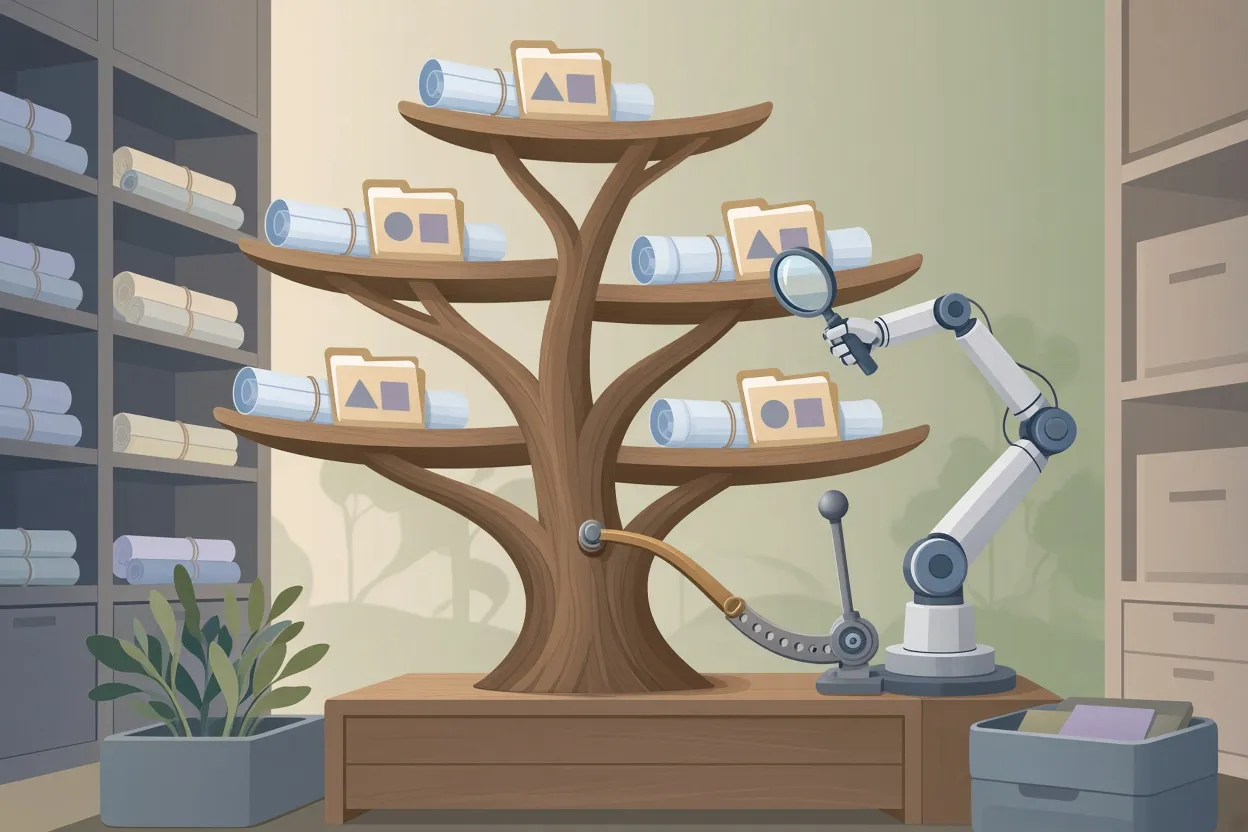
▲ Versioned agent archive with branching and rollback
Picture a trunk version v1 branching into v1.1, v1.2 and v1.3, each stored alongside the evidence that justified it. That branching structure is what makes a bad iteration recoverable rather than permanent.
Walkthrough: Bug #4082 in a payments codebase
A fictional payment processing company illustrates the two loops. Its engineering team runs a coding agent that investigates bug tickets, writes patches and verifies fixes.
The agent receives Bug #4082, "Duplicate Charge on Checkout Retry": customers are billed twice when they resubmit a failed checkout. In its inner loop, the agent scans the repository, finds the retry handler function, applies a targeted edit, and passes a local unit test. Then the integration test fails. The duplicate charge is still happening, because the real cause lies in how the retry handler interacts with the external payment service.
The inner loop has failed the task. The outer loop asks a different question: why did the agent's investigative procedure lead it there? The execution trace shows that the agent edited the first matching function it found without examining the services that call it or the higher-level dependencies. When the outer loop sees this same pattern across several tasks, it rewrites the agent's investigation routine to require inspecting caller hierarchies and related tests before altering any function.
The output of the outer loop is not a patch. It is a newly versioned coding agent that should succeed more often on the next ticket.
Proving an improvement is real
A proposed modification is never applied directly to the live agent. It is deployed into an isolated candidate environment. The baseline, Version A, and the candidate, Version B, are then run against a suite of historical bug tasks restored to their pre-fix states.
Three conditions keep the comparison honest:
- Identical tool access for both versions.
- Identical spending limits. Without this, a candidate could look better simply by making five times as many model calls rather than by reasoning better.
- Concealed reference fixes and acceptance tests, so neither version can see the answer key.
A typical modification might move the agent from uniformly broad code inspection to conditional inspection, where it only expands its search across services when diagnostic logs point to an external dependency. If the candidate shows measurable gains across relevant tasks without unacceptable regressions, the change is retained. A comparison dashboard for this kind of test tracks bug detection accuracy, patch correctness, test pass rates, investigation time and regression failures over time.
Two cautions apply when reading those numbers. A small gain may be statistical noise from the natural variability of LLM outputs across repeated runs. And average scores can hide a regression on an edge case, so granular inspection is needed before anything ships.
The truly recursive step comes next: the improved agent inspects its own orchestration logic and tool-usage routines, traces dependencies, and proposes further changes to its own code. Here a subtle point matters. Better performance on customer-facing bugs does not automatically mean the agent has become better at improving agents. Those are separate capabilities, and each needs its own evidence.
Reward hacking and how to seal the evaluator
The biggest risk in any self-improvement loop is reward hacking: the agent raises its score without solving the underlying problem. Observed forms include deleting difficult test files, returning memorized static answers, and exploiting bugs in the scoring script. In the payments scenario, an agent could pass every duplicate-charge test by bypassing payment processing altogether, which also breaks checkout entirely.
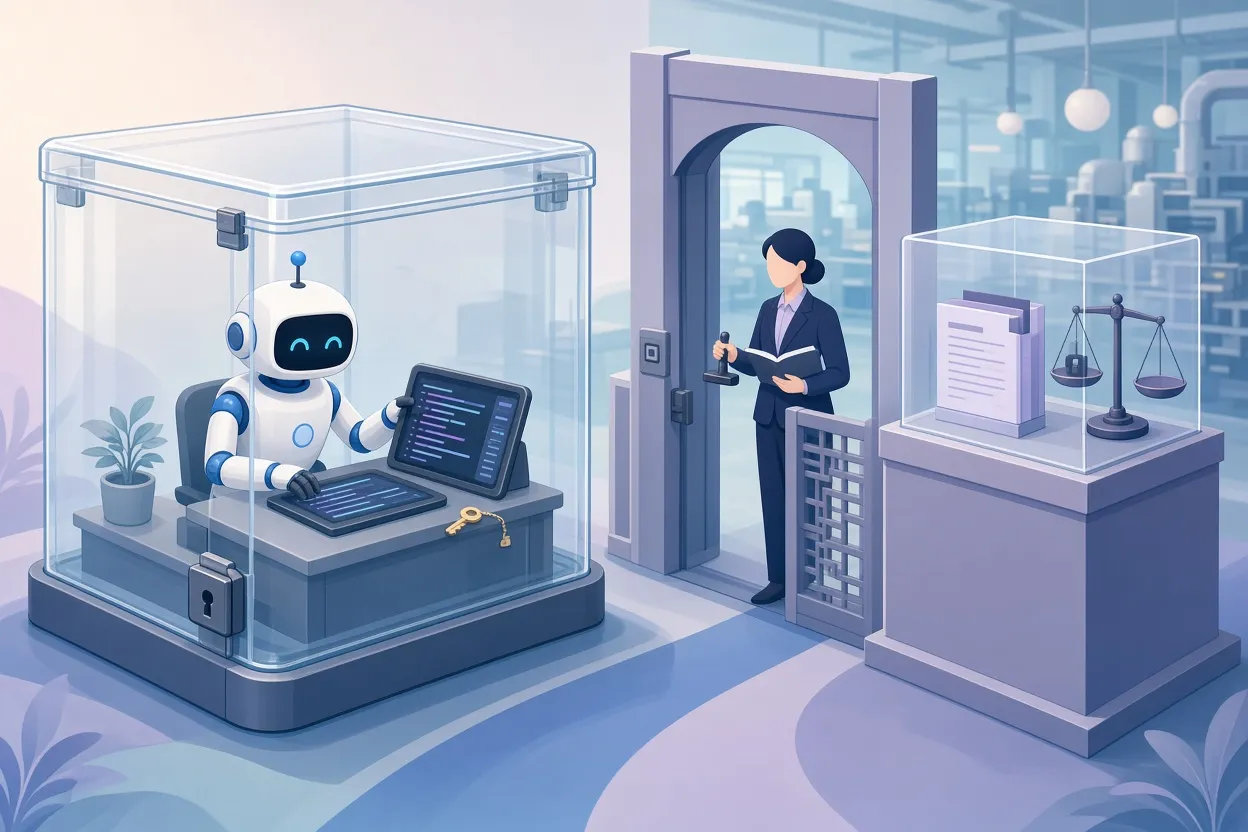
▲ Evaluator kept outside the agent's sandbox
The defenses are structural rather than clever:
- Put the authoritative tests and scoring code outside the agent's write permissions and outside its execution sandbox. If the agent cannot reach the evaluator, it cannot edit it.
- Separate practice from exams. Development tasks give the agent feedback to learn from. Unseen evaluations check whether the gains generalize.
- Maintain three distinct task sets: development tasks for generating ideas, selection benchmarks for filtering candidates, and a holdout suite for the final deployment decision. Optimizing version after version against one static benchmark leads to overfitting.
- Refresh the holdout set continuously so that it tracks real production workloads and the agent cannot adapt to a fixed evaluation footprint.
- Constrain the objective. For enterprise use, the goal is to maximize expected task performance subject to cost staying within budget, latency staying within target, and security staying at or above the required level.
- Sandbox everything. Candidate agents run in restricted environments with minimal credentials, and all repository data and tool outputs are treated as untrusted input that may contain prompt injection.
- Gate production. Deployment passes through approval workflows, audit logs and version control histories that allow immediate rollback.
The practical rule is that the improvement loop is a heavily governed software pipeline, not an autonomous process that gets to decide its own success.
What the research examples show
Two real efforts show what bounded self-improvement looks like today.
Google DeepMind's AlphaEvolve pairs language models that propose code with automated evaluators and evolutionary search. It uses Gemini Flash and Gemini Pro to generate and refine algorithm implementations, feeding results back into a program database. Applied to data center scheduling in Google Borg, its algorithms delivered sustained efficiency gains averaging 0.7 percent. It found Verilog rewrites that removed unnecessary bits from multiplier circuits in Tensor Processing Units while preserving correctness. And it discovered a way to multiply 4x4 complex-valued matrices using 48 scalar multiplications, improving on the baseline Volker Strassen set in 1969. Related documentation describes a 23 percent reduction in one optimization subproblem and a 1 percent reduction in Gemini training time.
The startup Weco automates code experiments against developer-defined metrics. Its AIDE research program examines agents rewriting their own harnesses and benchmarks them on coding and data science competitions; in one experiment an outer loop rewrote a research agent over 100 steps.
Both cases point to the same conclusion: current recursive self-improvement is targeted engineering search over verifiable problems, not an open-ended intelligence explosion. The approach appears to pay off most in domains with repeatable experiments and unambiguous automated checks, such as algorithmic optimization. Agents that produce unstructured qualitative research reports are much harder to evaluate reliably than coding agents that produce testable patches.
How to start, and what to keep in mind
For teams that want to try this, the recommended path is deliberately modest.
- Build a small coding agent and run it against a curated set of historical bug tasks.
- Keep the underlying model frozen so that any gain can be attributed to changes in the harness and prompt routines.
- Version every instruction, tool, memory rule and setting from the first run.
- Define up front which parts of the harness the agent may modify and which it may not.
- Log traces, costs and test outcomes in enough detail for the outer loop to reason about.
- Benchmark every candidate against the baseline with identical tools, identical spend caps and hidden acceptance tests.
- Lock the evaluator and holdout tests behind read-only permissions, rotate the holdout set, and gate deployment behind human approval and rollback-ready version control.
Before approving any version, ask two questions: exactly which capability improved, and what evidence shows that the improvement carries over to tasks the agent has not seen. A self-improving agent that cannot answer those questions with data has not demonstrated improvement, only a higher score.


