The latest round of updates to ChatGPT, Gemini and Claude points one way: AI assistants are leaving their own chat windows and settling into the browsers and office apps where work already happens. Claude now opens beside your work in Google Docs, Sheets and Slides. ChatGPT can look through the pages open in Chrome and act on them, from typing into forms to saving files. OpenAI’s voice model picked up six languages, Gemini can link to outside services and tell whether a picture came from Google’s AI tools, and developers get a much quicker GPT-6.1 variant plus a cheaper way to label and grade inputs. Here is what each change does, which ones are ready for daily use, and which deserve a closer look before you depend on them.
Claude arrives in Google’s office apps
Anthropic’s new Claude for Google Workspace connects Claude to Gmail, Google Calendar and Google Drive. Once its Chrome extension is installed, Claude appears as a panel along the edge of the doc, sheet or deck you have open, so it edits the real file rather than text you copied into another tab.
Typical jobs in each app:
- Docs: rework a staffing plan meant for executives, sharpen the section titles and convert bulleted points into side-by-side tables.
- Sheets: import a budget export in CSV form, calculate how far actual spending drifted from the plan, mark the departments that overspent and produce a summary table.
- Slides: combine notes on customers kept in Salesforce with Drive files into a complete deck for a quarterly business review (QBR).
There is also a separate Design section in Claude’s web app, reached from the menu on the left. It lets people produce presentations, interface layouts, code and complete design systems inside Claude, without needing Google Workspace. Teams that already work in Google’s apps will likely lean on the panel, while others can make the same kinds of material in Claude directly.
ChatGPT reaches into the browser
Hand your open Chrome tabs to ChatGPT
After you add the official extension to Chrome, ChatGPT can see your browser. Put “@Chrome” in your request and it reads the pages you currently have open and answers based on them. Imagine comparing several sofas in separate shopping tabs and asking which one would suit your apartment. ChatGPT checks each listing’s measurements, upholstery and cost, then names the one it thinks fits best.
It can do more than read. ChatGPT can type into web forms, save files to your computer and click through sites for you. Research and comparisons look like safe first uses. For anything that sends information or downloads something, it seems wise to check the outcome yourself.
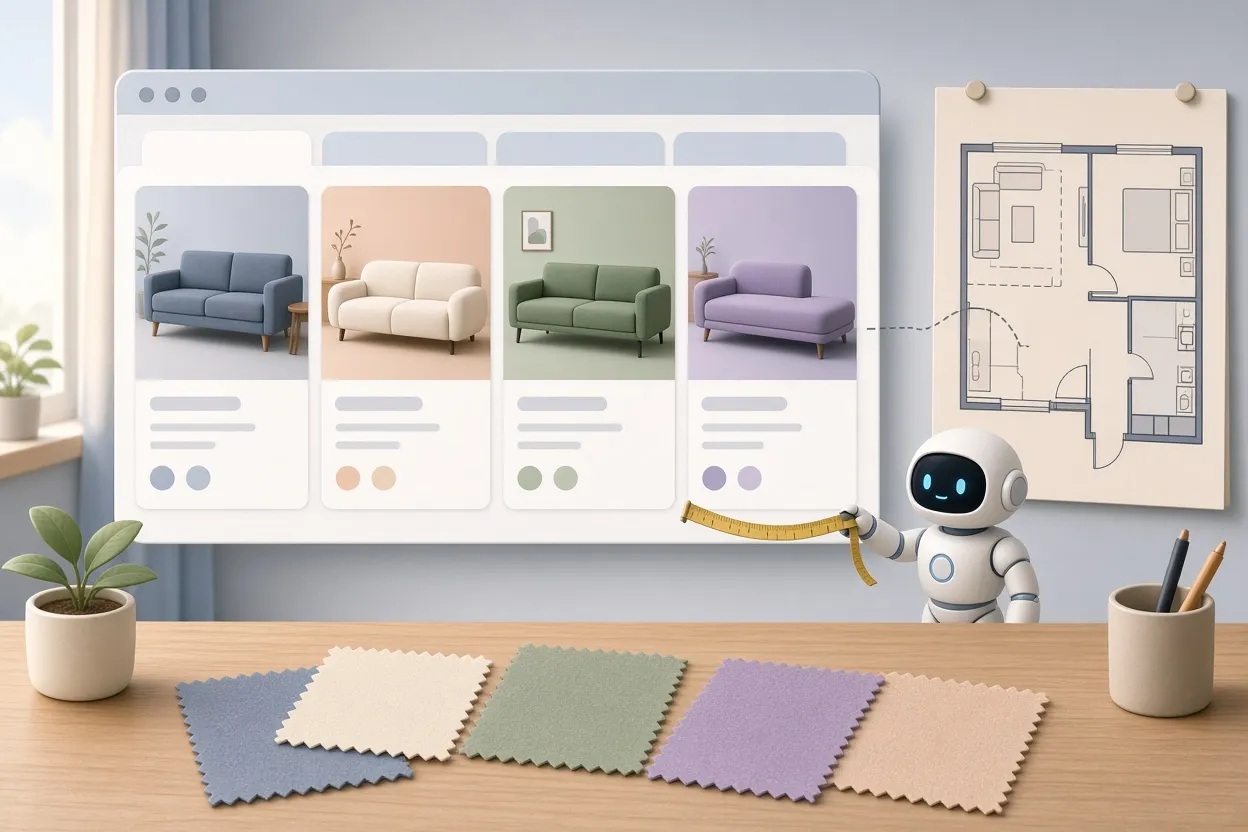
▲ AI comparing products across open tabs
A new voice model with six more languages
In ChatGPT, dots and Codex, OpenAI’s Voice Mode now runs on a new model called GPT-Live-1.1. It brings fresh voice choices and smooth conversation in Hindi, Korean, French, Japanese, German and Mexican Spanish. It also drops the repeated “Checking…” announcement that used to interrupt vibe coding, the habit of building software by describing what you want to an AI instead of writing the code by hand.
The new voice model also works in ChatGPT Work. With the microphone on, you can ask ChatGPT to go through attached files, use tools in the workspace and trigger plugins, all hands-free.
MCP apps in ChatGPT Work
Outside plugin makers and developers can now build dedicated apps for ChatGPT Work on the Model Context Protocol (MCP), a standard way to hook AI models up to external tools and data. One example comes from vidIQ, a YouTube analytics service. Its app reports how a linked channel’s latest uploads are doing and which other uploads in the same niche are taking off. A keyword view gives each search term’s monthly volume, a competition rating and how demand moved over the past 30 days. Pick one of the suggested actions and ChatGPT Work digs into the research behind the scenes and comes back with longer-range strategy ideas, without showing the user the prompt that drives it.
Gemini adds connectors and an AI image check
A settings menu called “Customize Gemini” now lets you turn on custom skills and hook up third-party services. The ready-made list covers Google Workspace plus Dropbox, Canva, Shopify and others, and you can also paste in the address of an MCP server you choose. Type “@” in the chat box and every skill and connector you have enabled shows up, ready to call by name.
One of those tools is @Verify AI, built on SynthID, Google’s technology for spotting content produced with its AI. Upload a picture, ask whether AI made it, and Gemini inspects it. An ordinary screenshot of a computer desktop comes back as not made with Google’s AI tools, while a portrait created by AI is flagged as produced or altered by Google AI.
That boundary matters. @Verify AI can tell you whether Google AI was involved, but it cannot always name the non-Google tool behind an image. A verdict that Google’s tools were not used is not proof that no AI touched the picture.
▲ Checking where an image came from
Gemini 4 Argon leads most of Google’s scorecard
Gemini 4 Argon now sits in Gemini’s model picker next to older choices such as Gemini 3.1 Pro. Google pitches it as its new top-tier model for business use and reasoning that spans many steps, aimed at work like digging through complicated financial reports, putting together slide decks and producing 3D models from a text prompt.
On the scorecard Google released, Argon outscored the other three models in the table below on most benchmarks, the standardized tests used to compare models on identical tasks.
| Benchmark | Gemini 4 Argon | Claude Opus 5.5 | GPT-6 Astra | Claude Fable 5.1 |
|---|---|---|---|---|
| Vals Index | 68.9% | 67.0% | 63.1% | 65.8% |
| AutomationBench | 51.3% | 42.5% | 41.4% | 31.4% |
| Vals Finance Agent v2 | 65.4% | 56.7% | 53.5% | 58.8% |
| DeepSWE v1.1 | 77.9% | 74.2% | 74.1% | 67.4% |
| Vibe Code Bench | 91.9% | 90.3% | 89.6% | 90.3% |
| GraphWalks, 256k | 84.2% | 66.8% | 71.8% | 65.0% |
| LVBench | 91.7% | 83.7% | 87.5% | 79.7% |
| FrontierSWE v2 | 55.0% | 62.3% | 65.5% | 56.3% |
| Terminal-Bench 4.0 | 57.4% | 66.4% | 58.2% | 57.9% |
Argon is not ahead across the board. It came last of the four on Terminal-Bench 4.0 and FrontierSWE v2. GPT-6 Astra beat it on Terminal-Bench Science 0.1, 68.1% to 57.6%, and on OSWorld-2.0, 72.6% to 69.2%. Claude Opus 5.5 finished ahead on PostTrainBench, 49.3% to 45.3%, and Argon and GPT-6 Astra tied at 68.0% on the CWE-Bench v1 security test. These are the company’s own numbers, and Argon trails on agentic coding tests like FrontierSWE v2, which measure how well AI agents handle programming jobs on their own. Anyone choosing a model for coding should run it on their own tasks first.
Faster output and cheaper judgments for developers
OpenAI has added GPT-6.1 Ultrafast to its API, listed next to GPT-6.1 Sol. It turns out tokens, the small chunks of text a model writes, eight times as fast as Sol. Every token is pricier, but the speed means far more work gets done in the same time, which looks worth the premium for large batches of repetitive agent jobs where waiting is the main cost.
The developer dashboard also gained a tool called Decisions. It sits outside the usual chat completions and makes judgment calls in three ways:
| Type | What it gives back |
|---|---|
| Predicate | How likely a statement is to be true, as a percentage from 0 to 100, for example whether a cat seems calm |
| Choice | A likelihood for every answer in a list you provide |
| Score | A calibrated rating that places an input on a ladder of levels you define |
Because Decisions never drafts a full reply, it responds almost at once and costs far less than asking a large language model to sort or check something. When an app only needs a label, a pick or a grade, routing that call to Decisions looks like an easy saving. The tool seems to have drawn little notice so far, but developers whose agents make many small checks may want to try it before anything else here.
What to try now, and what to test first
The updates that pay off fastest are the ones built into software you already open every day. Speed claims and benchmark wins are better treated as something to confirm on your own work before you rely on them more widely.
| Update | Worth trying if you | First step |
|---|---|---|
| Claude for Google Workspace | work in Docs, Sheets or Slides | Start with tasks you can check quickly, such as a budget review or a document cleanup |
| ChatGPT with @Chrome | compare things across many tabs | Use it for research and comparisons, and look over forms and downloads yourself |
| GPT-Live-1.1 voice | prefer talking to typing | Try spoken requests for file work in ChatGPT Work |
| Gemini’s connectors and @Verify AI | want one assistant across many services | Link the services you use most, and treat @Verify AI as a check for Google AI only |
| Gemini 4 Argon | hand off complex, multistep work | Select it in the model picker, but compare it on your own coding work |
| Ultrafast plus Decisions | build agents through the API | Use Ultrafast where speed sets your output, and Decisions for labels and grades |
The race among the three companies now seems to be as much about a spot inside everyday software as about benchmark scores. Before chasing the next model name, check which of these tools has already landed in the apps you open every morning.