Two developers can use the same frontier AI model with the same tools and get very different results. The best engineers may pull 10 to 100 times more value out of identical tools than an average user, and the gap appears to come from ambition: how large a job you are willing to hand the model. In an essay published on October 13, an engineering lead on Claude at Anthropic broke that ambition into four dimensions: speed, altitude, depth and range. This article walks through the last three and how to apply them to Claude Code and other AI agents, AI systems that use tools to carry out multistep work on their own.
Plain code generation no longer sets anyone apart
Anthropic’s own hiring records show how fast expectations have moved. In 2024, about 5% of technical hiring manager notes at Anthropic mentioned a candidate’s track record with AI tools, as did about 7% of non-technical notes. By 2026, those shares had roughly tripled and quadrupled. Asking Claude to write an isolated feature is now table stakes, and as basic code production gets cheap, engineers who stop there risk being left behind.
The four dimensions break down like this:
| Dimension | What it means | Example |
|---|---|---|
| Speed | Finishing hand-written work faster with Claude | The most basic level |
| Altitude | Raising instructions from tasks to outcomes to goals | From fixing one crash to keeping an app crash-free |
| Depth | Doing one task the way the field’s top expert would | Profiling instead of guessing |
| Range | Spotting when another field already solved your problem | Treating an error message as a support job |
Speed is the entry point, so the rest of this article covers the other three.
Altitude: hand over outcomes, not procedures
Raising altitude means moving your instructions up a ladder: from a procedural task, to the outcome you want, to the goal behind that outcome. A step-by-step prompt, meaning the instruction you give the model, caps the result at your own technical knowledge. A goal leaves the model room to reason its way to better architecture and solutions.
A database performance problem shows the three levels:
| Level | Instruction to Claude |
|---|---|
| Task | Add an index to the orders query |
| Outcome | Every page loads in under 200 ms for real users |
| Goal beyond the goal | Help users finish their work sooner. Find the spots where they wait or click around most, and remove them |
With the outcome-level prompt, Claude can first decide whether an index, a lookup structure that speeds up database reads, is even the right fix. The Anthropic engineering lead followed the same path. About 20 months ago, the lead asked Claude to fix individual crashes, then moved up level by level until the instruction became simply: keep the apps crash-free. Working at that altitude requires crash logging and environments that can reproduce bugs on Windows, macOS and Linux.
Give the agent its tools first
Before setting a goal like zero crashes, ask the agent directly which tools, credentials and environment access it needs to succeed. One practical setup is a dedicated Slack channel for the crash-free goal, where the agent gets the goal, is asked what setup and permissions it requires, and runs on its own every 12 hours. It inspects the repository and dependencies and may ask for resources such as a separate AWS account with a spending cap for sandbox experiments. The channel should work both ways, so the agent can mention a person whenever it needs new permissions.
Agents rarely stop to request missing tools on their own, so the work has to happen up front. A tools-first environment includes:
- Access to error logs and analytics events
- Read-only access to business systems such as Stripe
- Test devices and valid user logins
- The ability to create sandboxed test accounts
Set clear cost ceilings and safety boundaries on any sandbox before you give an agent broad rights to create infrastructure.
Stop acting as the middleman
When the process is manual, a person reads each support ticket, rewrites it as a prompt for Claude Code, tests the result and goes back and forth several times. That person is only relaying messages, and the relay becomes the bottleneck.
The alternative is an autonomous triage loop. Connect the support inbox to the agent through an MCP server, which uses the Model Context Protocol to link AI models with outside tools and data, and add real-time error logs from Sentry. The agent matches each incoming report with the corresponding crash trace and tries to reproduce the bug in a virtual environment. If it cannot, it asks the user directly, for example which browser they used or how their shortcuts are configured. In one case, a customer of an app wrote in Japanese about a shortcut problem. The agent rented a macOS machine, tried to reproduce the issue and drafted a follow-up asking whether “key” meant a keyboard shortcut or an API key.
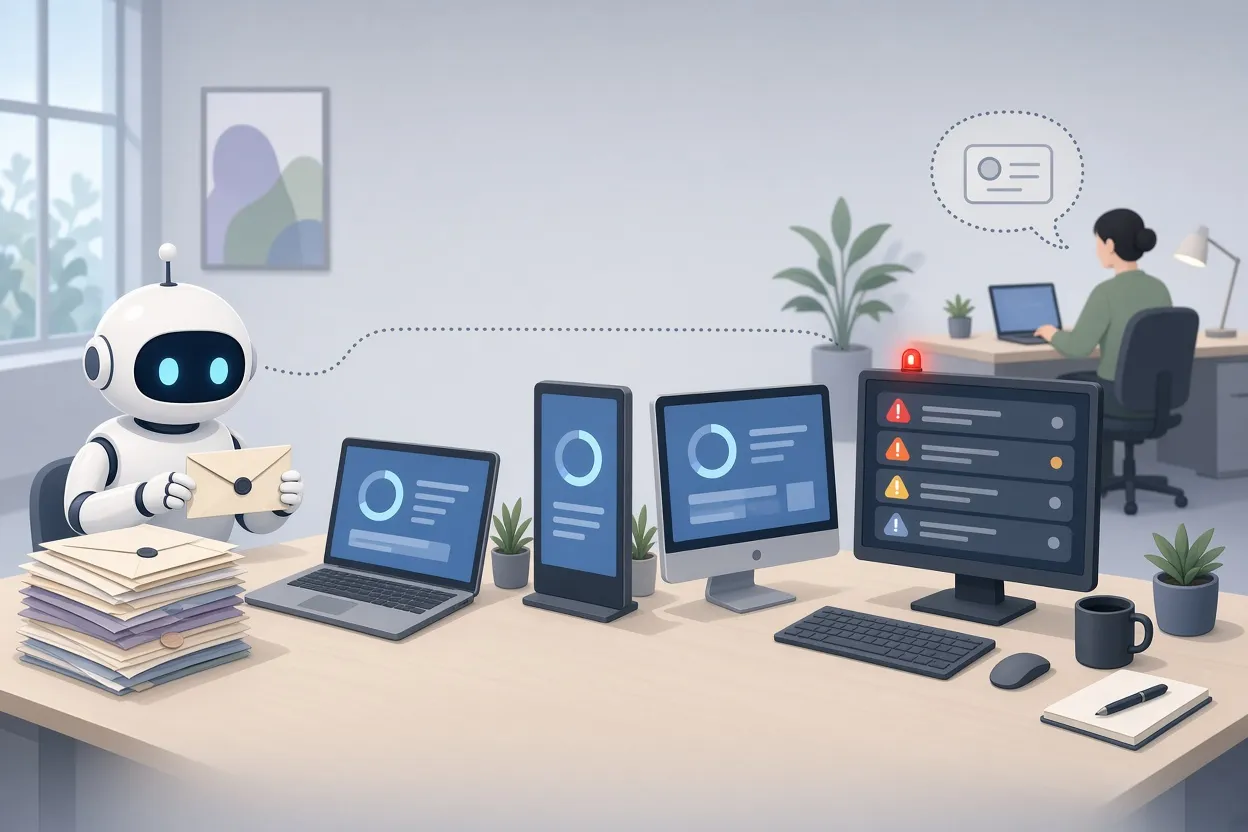
▲ An agent reproducing customer-reported bugs
Replace dashboards with an agent that asks questions
Analytics services connected to an agent through MCP servers make combined dashboards easy to generate on demand. But dashboards exist to answer business questions, so hand the agent the goal itself:
I want happier customers and more revenue. Each week, come up with the 10 questions that matter most for getting there, answer them, and write up the findings as a report with charts.
An agent given that brief found that the median time from first visit to purchase was about 4 minutes, a sign of impulse buying. It also found that people who watched promotional videos all the way through were less likely to buy: higher video retention went with lower revenue.
Give agents ownership of metrics, then aim at the system
The next step is to stop triggering agents by hand whenever something breaks. Instead, an agent owns a set of business gauges, such as revenue, signups, refunds, churn and application errors. It checks them daily or every few days and alerts a person only when something looks wrong.
The highest altitude is the software factory: the system that produces software, rather than any single feature. An agent pointed at the system builds features, repairs bugs and runs engineering workflows across several applications without constant supervision, and a fix to an underlying pattern spreads to every app and surface that depends on it. In one GitHub repository, bot agents find issues, open pull requests (proposed code changes), run verification and merge fixes around the clock. Routine tasks and bugs can go to agents, but very large, critical features still seem to call for hands-on human oversight.
Depth: expert methods, not expert vocabulary
Depth means doing a single task at the standard of the best professional in that field. Telling a model to “act like a pro” mostly changes how it talks: it starts mentioning p-values or cohort retention while its methods stay the same. Real depth comes from making it use real databases, statistical modeling and regression tools instead of quick Markdown tables and guesswork.
Take an app that needs 10 seconds to load. A plain request to make it faster tends to return generic advice such as lazy loading, which defers loading until something is needed, or React’s useMemo. Instead, ask Claude to work the way a performance engineer would and start from profiler traces, timing records that show where each part of the program spends its time. It then examines routing, authentication, rendering and database queries one by one and pinpoints the actual bottleneck, such as long-running database queries.
Targets matter too. Set goals that look unreasonable, such as 200 ms when 5 seconds would be acceptable, and keep pushing when the agent first calls the target impossible. That pressure can push the model past surface tweaks into structural optimization.
The essay also offers a four-step meta-prompt, a prompt that rewrites your ordinary prompt into a rigorous specification. It asks the model to:
- Point out what a leading expert would rely on that your prompt leaves out
- Identify the raw source material to work from
- Specify the tools an expert would use
- Define an objective verifier that can check the result
Range: turn nouns into verbs
Range is the ability to notice when a completely different profession has already solved the problem in front of you. Specialists often miss these connections, so the suggested fix is to rewrite the task’s main noun as a verb phrase that describes what people need to do and why. “A deck” becomes “convince busy people of a cause-and-effect story so they can decide under uncertainty within 30 minutes.” Framed that way, the methods of journalists, editors and analysts become available. If you are unsure which fields apply, ask Claude to interview you about the problem and identify professions that face the same structure.
Treat error messages as a support job
Applied to an HTTP 500 (internal server error) page, the noun “error message” becomes “help a confused person solve the problem on their own, without reaching out to anyone.” That is a support agent’s job. Claude analyzed six months of support tickets and grouped the errors by frequency. Four error types, covering login, upload, payment and export, accounted for about 61% of all tickets. For an upload that fails on size, the generic “try again later” notice gives way to a clear message that the 6 GB file exceeds the plan’s 5 GB limit, with inline options to compress the file or upgrade the plan.
Read feature requests as symptoms
When users keep asking for a CSV export button, the usual response is to ship the button and mark the ticket done. A good doctor treats a patient who demands antibiotics differently, examining the symptoms before writing a prescription. Prompted to act as a diagnostic doctor, Claude reviewed 43 CSV export requests:
| Underlying need | Requests |
|---|---|
| Automatic weekly Google Sheets sync on Mondays | 29 |
| Statements that users had been emailing to accountants by hand | 8 |
| A standalone CSV download button | 6 |
That diagnosis points to higher-leverage features, such as an automatic Google Sheets sync and monthly statements sent on a schedule, with a basic export button as well. Today’s frontier models do not reach for range by default, so users still have to prompt for it explicitly. Future models may do it naturally.
▲ Diagnosing feature requests like symptoms
Expectations are falling behind the models
The essay closes on self-efficacy, the belief that you can achieve significant results. Model capabilities appear to step up every two weeks while human expectations stay put, and that gap acts as an artificial ceiling. Seeing someone else do the hard thing resets it. After Roger Bannister broke the four-minute mile in May 1954, another runner did the same just 46 days later. Sabastian Sawe broke the two-hour marathon barrier in London. Mathematician George Dantzig arrived late to a class at UC Berkeley, took two famous unsolved statistics problems on the board for homework, and solved both. Watching what others do with agents may be the simplest way to raise your own expectations.
What to change in your next prompt
Getting more from the same model means aiming higher, going deeper and looking wider. Practical steps:
- Rewrite your next Claude Code instruction at three levels: task, outcome and the goal beyond the goal.
- Before assigning a big goal, ask the agent what tools, access and setup it needs, and set cost ceilings and safety boundaries on its sandbox.
- Connect support tickets and error logs to an agent through MCP, and let it ask users directly when it cannot reproduce a bug.
- Replace dashboard reviews with a weekly set of 10 questions and a report that answers them.
- For performance work, demand profiler traces and an aggressive target. When stuck, turn the problem’s noun into a verb and look for a profession that already solved it.
Keep a close hand on the largest, most critical features, but start moving routine work to goal-level instructions to see how much more the same model can do.