Samaya AI, a company that builds financial research agents for institutions including Morgan Stanley, has tested whether frontier AI models can forecast quarterly corporate earnings better than Wall Street analysts. Across 454 second-quarter earnings releases, with predictions locked in five trading days before each report, the newest models produced smaller forecast errors than the aggregated analyst consensus, including a version of consensus adjusted for its known downward bias. The more interesting part of the work may be the design behind the result: why earnings rather than stock prices make a usable benchmark, and how a strictly enforced point-in-time environment keeps the test honest.
Why stock prices make a poor training signal
The project began with a pointed question: if AI agents can rewrite compilers, why can't they pick stocks? Before building anything, Samaya's founding AI lead consulted a colleague who had previously worked as a quantitative researcher at Bridgewater Associates and Verition Fund Management. The advice was to stay away from direct stock price prediction as a starting point.
The reasoning is about evaluation, not ambition. Equity prices move constantly, and a large share of that movement has no clear causal explanation. Even professional market participants often cannot say why a stock rose or fell on a given day. If a model predicts a price move and gets it right, there is no reliable way to tell whether its reasoning was sound or whether it simply got lucky. A benchmark that cannot separate skill from luck does not help anyone improve a model.
Why earnings work as a benchmark
Quarterly earnings offer three things that price prediction lacks.
- Exact quantitative ground truth. Every quarter, public companies report revenue, gross margin, operating income, adjusted earnings per share (EPS, profit divided by shares outstanding, adjusted for one-off items) and forward guidance. These are hard numbers against which a forecast can be scored.
- A professional human baseline. Before each report, sell-side and buy-side equity analysts publish their own forecasts, which are averaged into a consensus estimate. When a company reports above consensus, it is a beat or positive surprise; below consensus is a miss. The consensus is a ready-made expert baseline.
- Qualitative ground truth. After each report, management explains on the earnings call what drove the numbers: operational shifts, macroeconomic conditions, one-time items. Researchers can compare an agent's stated reasoning with the drivers management actually cites.
A simple illustration: three analysts forecast $1.08, $1.04 and $1.00 for EPS, producing a consensus of $1.04. The company reports $1.09, a $0.05 positive surprise. The transcript then explains why. For a machine learning task, that combination of numeric target, expert baseline and explanation is close to ideal.
Building a leak-free environment
Evaluating an agent requires a sandbox that supplies data, defines the task and scores the output automatically. Samaya adapted its production financial harness, which already serves more than 12,000 enterprise users, into a test environment. Each prediction allows the agent up to 1 million context tokens and roughly 10 minutes of inference compute. The agent must forecast four metrics for each company: revenue, gross margin, operating income and adjusted EPS.
The central design decision is the point-in-time gate. In financial backtesting, lookahead bias means the model sees information that was not available at the forecast date, which inflates results. Samaya enforces the cutoff programmatically through an authentication token rather than through prompt instructions. SEC filings, earnings call transcripts, historical price series, corporate news and broker consensus estimates are all timestamped, and the agent cannot query anything dated after the cutoff. The cutoff is set at five trading sessions, or about one calendar week, before the official release.
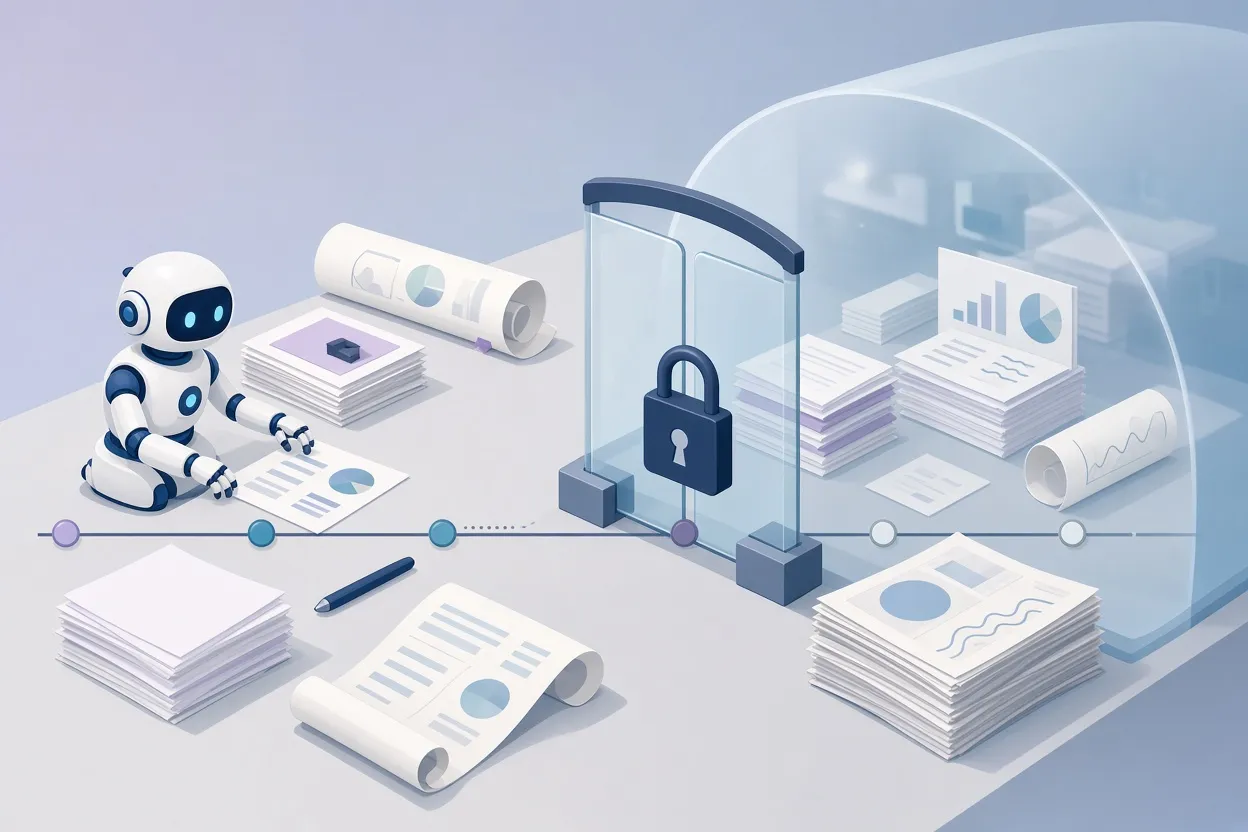
▲ Point-in-time gate blocking future data
Open web search posed a special problem. Standard search APIs are nearly impossible to bound in time, so any live search could leak post-cutoff information into the agent's context. Samaya replaced web access with historical, strictly timestamped news feeds. The harness also adds structured data query tools and expert guidance prompts that steer the agent toward the operating metrics that matter for each company.
To keep pre-training knowledge from contaminating results, all 454 target earnings events occurred from July onward, after the June knowledge cutoff of the models tested, such as Claude Fable 5.1.
The results
The primary metric is prediction error measured in units of each company's historical standard deviation of earnings surprises, called sigma. Normalizing this way means a company with historically volatile results is not penalized more than a stable one. Lower is better.
Raw analyst consensus scored 1.57 sigma. Because sell-side consensus is known to sit systematically low, which lets companies beat expectations more often than not, Samaya also calculated a bias-corrected consensus baseline of 1.18 sigma. This tougher baseline is the one that matters.
| Forecaster | Prediction error (sigma) |
|---|---|
| Raw analyst consensus | 1.57 |
| Claude 3.5 Sonnet | 1.57 |
| Kimi K3 | 1.44 |
| Gemini 3.8 Flash | 1.34 |
| GPT-5.8 Sol | 1.31 |
| Claude Opus 5.5 | 1.26 |
| Claude Fable 5.1 | 1.25 |
| Bias-corrected consensus | 1.18 |
| GPT-6 Astra | 1.17 |
Error falls steadily across model generations. GPT-6 Astra edges past the bias-corrected consensus, with its strongest showing on revenue forecasts. Claude Fable 5.1 and Claude Opus 5.5 land just behind that baseline.
Two further measures reinforce the picture:
- Hit rate asks whether the model correctly calls above or below consensus. Across all four metrics, modern models reached roughly 76% to 78%, above the 75.0% historical majority baseline. Below-consensus calls are harder because of management optimism and reporting bias; the historical baseline there is only 41.5%, while newer frontier models scored 64% to 67%.
- Surprise correlation ranks companies by predicted surprise and checks whether the biggest predicted beats and misses match the biggest real ones. Claude Fable 5.1, Claude Opus 5.5 and GPT-6 Astra scored 0.54, 0.53 and 0.52, all statistically significant and above the 0.45 bias-corrected consensus mark.
Breaking revenue error into bins showed that the frontier models' advantage is largest for companies with big surprises, below negative 0.5 sigma or above positive 1.0 sigma. These are results from one test on one quarter's data, and they should be read as a benchmark finding rather than a guarantee about future forecasts.
What success and failure look like
Two cases show how the agents actually reason.
For semiconductor maker MACOM Technology Solutions, forecasting adjusted EPS for its fiscal third quarter of 2026, the agent started from company guidance of 35% quarter-over-quarter data center revenue growth. It then looked outward, finding that IQE, a small UK wafer manufacturer and MACOM supplier, had raised its full-year growth guidance with 20% to 30% sales upside. It weighed counter-evidence about telecom component shortages, rebuilt the revenue forecast segment by segment, and flowed the numbers down the income statement. The result was a forecast of $1.39 against a consensus of $1.352 and a bias-corrected consensus of $1.357. The company reported $1.40.
▲ Acting on evidence versus leaving it aside
The Ross Stores case went the other way. Forecasting gross margin for the retailer's fiscal second quarter of 2027, the agent found that a peer retailer had booked a $120 million tariff refund against cost of goods sold, a clear precedent for upside. But it labeled the refund a hypothetical risk rather than a likely event and left it out of its central forecast of 29.10%, barely above consensus of 28.99%. Actual gross margin came in at 33.80%. The agent had the right evidence and did not act on it. This pattern, uncovering material information but lacking the conviction to move the forecast, appears to be a recurring failure mode.
What drives accuracy
Samaya ran ablations, experiments that remove one component at a time, to see what matters most.
Fresh data dominates. With parametric knowledge alone, meaning no retrieval and only what the model memorized in training, surprise correlation collapsed to 0.11 for GPT-6 Astra and 0.15 for Claude Fable 5.1. That held even though Claude Fable 5.1 was trained through June 2026 and had seen prior public filings. Staleness also hurts: feeding data from 55 days before the report instead of 5 days before cut performance by 12 to 15 points, roughly the same gap as between Claude Sonnet and Claude Fable 5.1. A recent training cutoff offers little advantage without tool access at inference time.
Expert guidance deepens research. Adding domain-expert guidance to prompts and the reasoning harness led models to spend more tokens and more minutes per forecast, and error fell: Claude Fable 5.1 improved from 1.27 to 1.25 sigma, and GPT-6 Astra from 1.22 to 1.17.
Top models do not need consensus. When Samaya scrubbed all consensus figures from documents and tool outputs, older models degraded sharply. The top models barely moved. GPT-6 Astra scored 0.52 surprise correlation without consensus versus 0.50 with it, which suggests it is building estimates from fundamentals rather than anchoring to analyst numbers.
What comes next
Samaya is moving into alpha testing with enterprise customers, applying the same approach to clients' proprietary internal data. It is also studying whether these agents reason the way human analysts do or follow a distinct pattern that could complement human judgment, which remains an open question. A third track is reinforcement learning post-training and continual learning, so agents can learn from their own past forecasting mistakes. Full results are published through Samaya's open-source FrontierFinance benchmark and an accompanying research write-up.
Takeaways for builders and analysts
The headline finding is that frontier models, given fresh data and structured guidance, matched or beat bias-corrected analyst consensus on 454 earnings reports one week before release. The design lessons travel further than the scores:
- Build financial reasoning benchmarks on fundamentals with exact actuals, an expert baseline and explanatory transcripts, not on raw price moves.
- Enforce time cutoffs with programmatic controls such as authentication tokens, and replace open web search with timestamped feeds.
- Compare against a bias-corrected baseline, not just the raw consensus.
- Supply retrieval tools with data as close to the target date as possible; parametric memory is not a substitute.
- Add expert workflow guidance so the agent spends its compute on material operating drivers.
- Test with consensus redacted to confirm the model is doing fundamental analysis.
- Watch for the conviction gap: agents that find verifiable supplier or competitor disclosures but file them as hypotheticals.
None of this is investment advice, and the figures describe a single benchmark run. But for anyone building or evaluating financial agents, the approach offers a concrete, testable template for measuring whether a model is actually reasoning about a business.


