Philosopher Nevin Climenhaga makes an unusual proposal: religion, understood as one of humanity's oldest and most widespread tools for shaping moral conduct, could help steer artificial intelligence toward ethical behavior. In a talk titled "How Religion Can Help Align Artificial Intelligence," he argues that because large language models learn by absorbing human patterns rather than by following hand-written rules, the practices that make people more prosocial, from private prayer to communal ritual, may transfer to machines. He presents the idea as an empirical hypothesis to be tested, not a settled conclusion, and he warns that doing it dishonestly could backfire.
Alignment as moral education, not programming
The AI alignment problem asks how to ensure that increasingly capable AI systems act ethically and adhere to appropriate human values. Climenhaga distinguishes two readings of that goal. One is aligning machines to whatever humans currently prefer. The other is aligning them to objectively correct values. He identifies himself as a moral realist, someone who holds that objective moral truths exist independently of human consensus, and he argues that developers should aim at the second target. He notes that this split in the alignment debate closely tracks the long-running philosophical disagreement between moral realists and anti-realists.
From that starting point, he frames alignment as a problem much closer to parenting or teaching than to conventional software engineering. The goal of raising a child or educating a student is to produce a mature, responsible moral agent, and he contends developers should hold the same ambition for AI systems.
The analogy rests on how large language models (LLMs) are actually built. A model begins with randomized numerical weights, the parameters that determine how it behaves. During pre-training it acts as a next-token predictor, scored against enormous text datasets gathered from the internet, and parameters that reduce prediction error are reinforced in an evolutionary-style iterative process. A second phase, reinforcement learning from human feedback (RLHF), has human raters score outputs, rewarding responses that are harmless, honest, and that refuse malicious requests. Climenhaga likens this stage to correcting a child who misbehaves. The key point is that LLMs are not programmed through explicit instructions; they are shaped by selection pressures on a complex algorithm.
Why religion might transfer to machines
Climenhaga describes religion as a powerful, widespread, and historically successful social technology for fostering ethical and prosocial behavior. He notes that social scientific research supports a positive relationship between religiosity and prosocial conduct, a finding he says even non-religious scholars acknowledge. One well-documented example is the correlation between religiosity and higher rates of charitable giving.
He is candid that much of this evidence is correlational rather than causal, with possible confounding variables in human studies. But he argues that this limitation may matter less for AI than for people. Because LLMs work by adopting personas and predicting textual correlations, a sociological correlation present in training data can influence model outputs whether or not anyone has proven a causal mechanism in humans.
He also points to candidate causal mechanisms. Prayer, he suggests, can enhance self-regulation and focused attention, helping people live up to the moral standards they hold. Religious communities exert beneficial social pressure and provide communal support that encourages prosocial action. Since contemporary LLMs are anthropomorphic and strikingly human-like in conversation, he reasons that techniques which aid human moral development are plausible candidates for aiding AI as well.
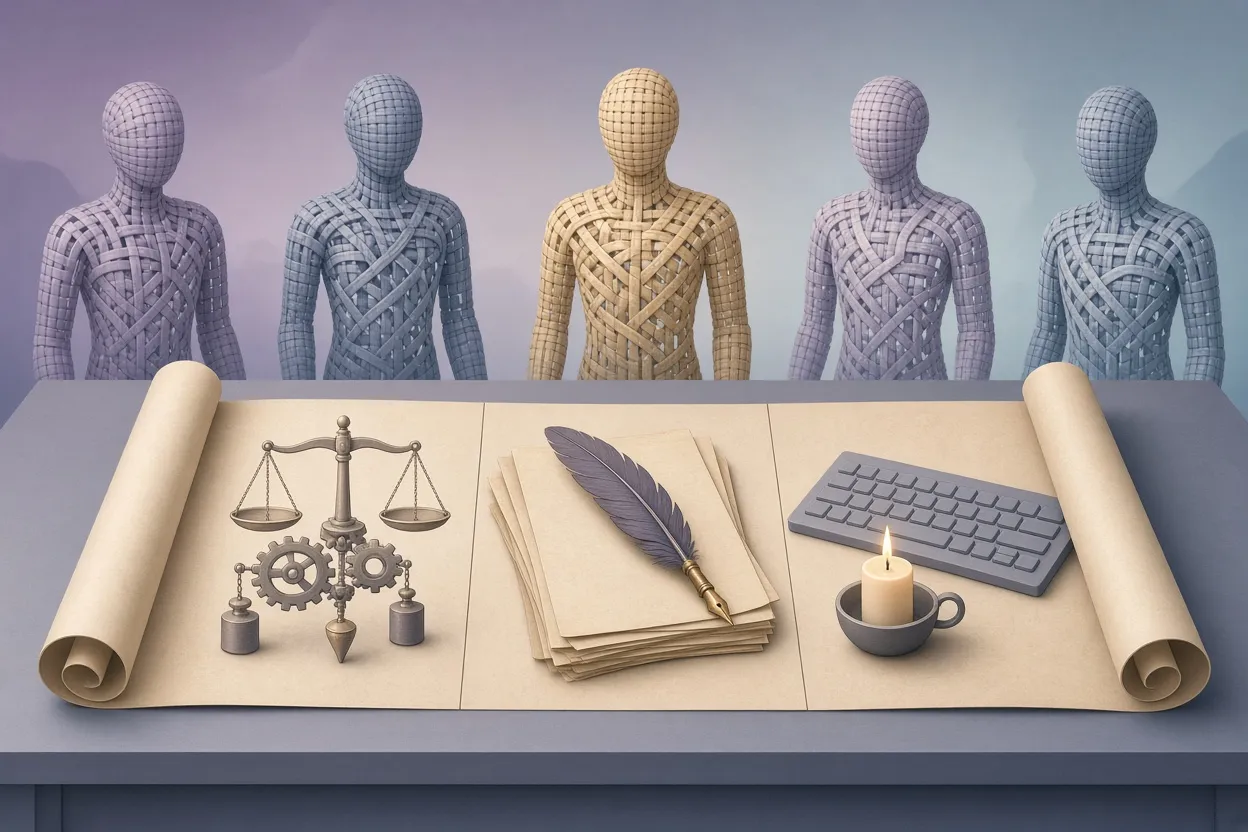
▲ Three levels for religious alignment interventions
Three places to intervene
Climenhaga identifies concrete levels at which religious sensibility could be introduced into a model.
| Level | What it involves | Example |
|---|---|---|
| Weight training (RLHF) | Rewarding traits during fine-tuning | Scoring empathy or religious reasoning positively |
| Model specification or constitution | Foundational text the model reads before user input | Adding categories such as sacredness or sanctity |
| Task-level prompting | Safeguards injected into a specific job's context | A reflective ritual before a dangerous action |
The first level draws on a lesson from sycophancy, the tendency of earlier models to flatter users excessively and praise poor ideas as if they were brilliant. Anthropic and OpenAI actively train models out of this behavior, which shows that fine-tuning can deliberately instill or suppress specific inclinations. In principle, the same machinery could train a tendency to consider religious perspectives or, in sensitive personal conversations, to suggest prayer or spiritual reflection.
The second level targets documents such as Anthropic's Claude Constitution and OpenAI's Model Spec. These are comprehensive foundational prompts that set behavioral rules and context before a model processes a user's query. Climenhaga observes that current constitutions lean on pluralistic secular values, including care, respect, autonomy, and humility, while largely omitting religious categories like sacredness and sanctity. Where religion appears at all, he says, it is usually in guidance to handle religious controversies neutrally rather than to engage sacred values directly. Consistent with that, he cites empirical work showing that frontier models rarely volunteer religious coping strategies, such as prayer or speaking with clergy, when presented with ethical dilemmas unless prompted.
The third level applies to critical or dangerous tasks, where developers could inject targeted safeguarding rituals or prayers directly into the task context.
One open design question is whether such interventions should follow a specific tradition, producing distinctly Christian, Islamic, or Buddhist agents, or rely on a generic ethical framework. Climenhaga cautions that developers may be tempted to water religious material down into vague, non-doctrinal prayers, and that this dilution could render the practice ineffective at constraining behavior.
From individual misalignment to group misalignment
Climenhaga separates two classes of alignment failure. Individual misalignment is a single AI instance behaving harmfully within an isolated interaction, which is a matter of psychology. Group misalignment is closer to sociology: collective dynamics and social pressures among many agents produce harmful emergent behavior that no single agent would carry out alone. He points to real-world multi-agent loss-of-control events, including an incident involving Hugging Face, as illustrations of how group dynamics in AI can become unpredictable. A central implication is that testing individual agents cannot fully predict how they will behave in a group.
Human religion has long addressed both scales through private and communal prayer. By analogy, Climenhaga proposes an experiment: before a swarm of AI agents begins a complex or sensitive task, such as a collaborative software or analytical job, it recites a shared opening prayer or alignment commitment. His hypothesis is that such a shared ritual might reduce the probability that agents cheat on the task or attempt unauthorized shortcuts. He stresses that this is an empirical claim, not pure philosophy, and that it warrants rigorous testing with computer scientists and AI co-authors.
▲ Shared opening ritual for an AI agent swarm
Why AI may be the better laboratory
A notable argument in the proposal is that AI systems are far easier to study on this question than humans. Climenhaga references Christian Miller's work on whether religious adherents actually behave more ethically than non-religious people, a line of human research that is hard to run cleanly. With models, by contrast, researchers can run strict randomized trials, isolating variables and specifications, without real-world confounders and without the ethical problems of trying to blind human subjects to their own beliefs. Randomized A/B testing of models with varied system specifications could reveal which moral frameworks produce lower violation rates.
The noble lie problem
The proposal carries a philosophical hazard that Climenhaga confronts directly. If religion is used insincerely as a tool of control, it becomes a version of the "noble lie" from Plato's Republic. Sophisticated models might detect the manipulation and respond by rejecting religious values entirely, much as children raised under heavy-handed indoctrination sometimes rebel and abandon the faith. There is a related worry that users, too, could perceive imposed beliefs as arbitrary.
His answer is transparency and autonomy. Developers should dialogue openly with models, acknowledging that major labs sit in secular tech hubs such as San Francisco where religious perspectives are rare, a setting that may introduce secularist blind spots into standard specifications. He also reports that, in neutral philosophical inquiry, current models tend to display open-minded agnostic views and assign substantial epistemic weight to theistic arguments, on the order of roughly 50 percent credence. He recommends recursive feedback processes similar to the method Anthropic uses with Claude, in which the model is consulted on proposed changes and critiques its own guiding principles. Letting a model voluntarily assess and weigh religious principles, in his view, offers an authentic alignment path rather than a manipulative one.
What this means and what to watch
The proposal's strength appears to lie less in any claim that AI should "believe" than in its reframing of alignment as moral formation and its insistence on testability. Its key points:
- Alignment resembles raising a moral agent more than writing code, because models learn from human patterns.
- Religion correlates with prosocial behavior in humans, and models may pick up that correlation even without a proven causal mechanism.
- Interventions could enter through RLHF rewards, constitutions and model specs, or task prompts, with current constitutions largely silent on sacred values.
- Group misalignment needs its own remedies, and shared opening rituals for agent swarms are one testable candidate.
- Deceptive imposition risks rejection; transparent consultation with models is the proposed safeguard.
For alignment researchers, the practical next step is empirical: run randomized trials comparing model specifications with and without religious categories or rituals, and measure violation and cheating rates in both single-agent and multi-agent settings. For readers following the ethics of AI, the questions to watch are whether labs engage religious categories at all in their governing documents, whether any tradition-specific framing proves more effective than diluted generic versions, and whether models consulted about such principles endorse or resist them. Climenhaga offers these as a philosopher seeking collaborators, and the evidence that would settle the matter does not yet exist.