Running a dozen AI agents at once can look like a leap in productivity while producing little more than slides and reports nobody reads. The fix is not fewer agents but tighter management: count the human work an agent creates, experiment more than you commit, decide when a task ends before it recurs, and treat your own attention as a budget that a dedicated "chief of staff" agent protects. These four principles come from hands-on experience running agents inside Claude and OpenAI Codex, and they share one premise: output volume is not the same as finished work.
Why agent busywork is hard to spot
Terms like "AI factories," "agent swarms" and "parallel agents" all encourage the same behavior: spin up as many concurrent agents as possible. A lot of what results is productivity theater. It looks like work, it burns tokens like work, and it ends in a board slide nobody cares about. The trouble is that AI makes this harder to detect than ordinary office busywork, because the volume and polish of the generated material seem impressive. It is now common to see people with several new apps, plans and always-on agents while the business underneath them has still not launched.
Managing autonomous agents therefore appears to demand more intentionality than any earlier tool knowledge workers have used. The four principles below are a way to supply it.
Principle 1: Count the human work after the agent finishes
The real cost of an agent is not its generation time. It is the human attention needed to read, understand, verify and act on what it produced. Users tend to skip this calculation because the raw speed of the output is dazzling.
A positive example makes the point. A chef who runs a culinary business in South Jersey used Claude to draft customized client proposals and, according to a Claude case study published September 15, 2026, earned $20,000 in about six weeks. The workflow works because a won proposal leads directly to high-value cooking work he actually wants to do. The downstream human labor is the point, not a burden.
Before launching any agent, three screening questions help:
- Who will use this output?
- What happens next once it exists?
- Do you actually want to spend time on the work that follows?
A common trap is valuing an AI deliverable by how long it would once have taken: a week, a developer, a whole team. That comparison says nothing about whether the task deserves your time at all. A report that saves a week of drafting can still waste ten minutes of reading if the underlying decision is irrelevant or belongs to someone else. The same logic applies at scale: an automated weekly report sent across an organization quietly imposes a recurring attention tax on every team that receives it, with no verified justification.
Make agents show their work, and use checking agents
A Chicago-area painting contractor who has run his firm since 1984 uses Claude to parse multi-floor architectural PDF blueprints for bids, as described in a Claude profile of 1,000 small business owners published September 10, 2026. He caught Claude applying a floor-area multiplier instead of taking actual wall measurements, an error that could have led to badly underbid projects. His response was a standing prompt rule: show all the math and every measurement step.
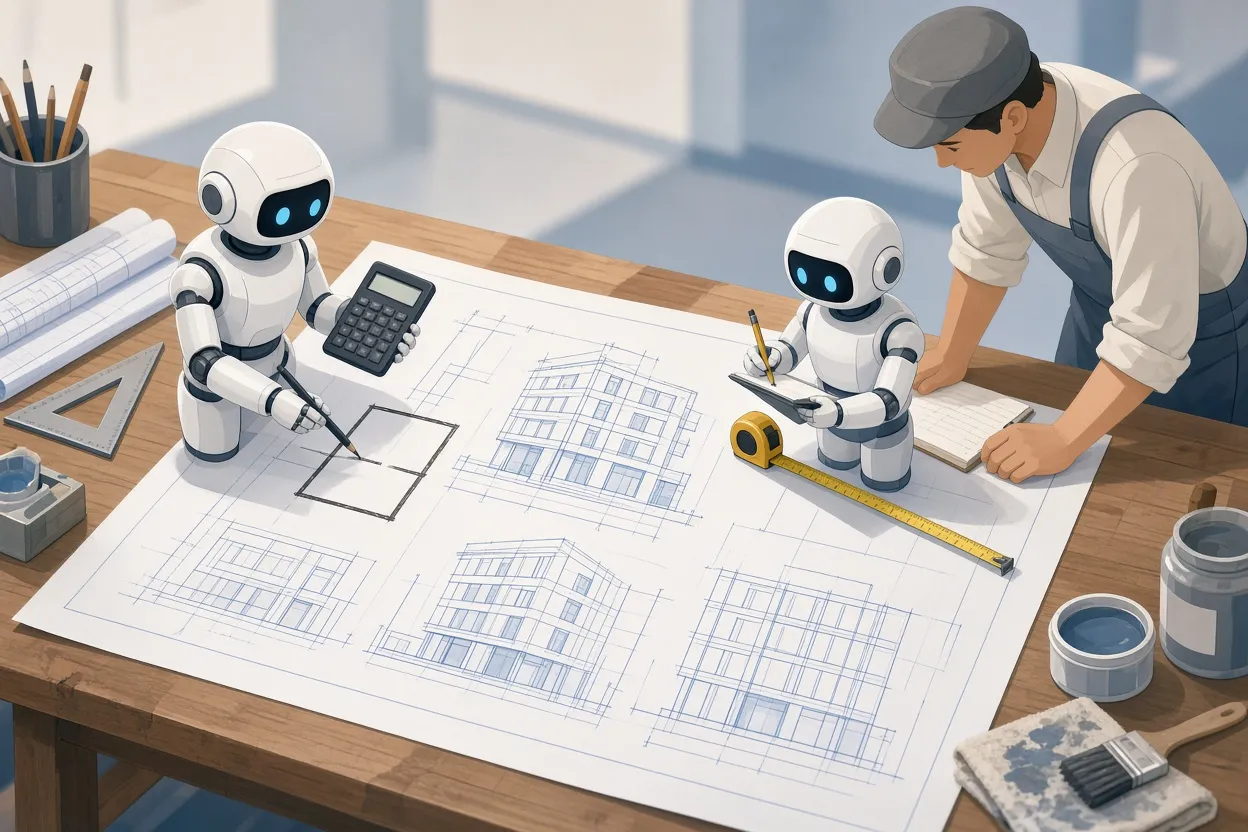
▲ Floor-area shortcut versus actual wall measurements
Two lessons follow. First, domain expertise tells you which calculations need scrutiny, so adjust assignments accordingly. Second, a polished proposal built on a flawed core number is worse than useless, because it invites misplaced confidence. To reduce the verification load, deploy a secondary checking agent with a narrow brief:
- Check the evidence behind the claims
- Find the assumption that would change the answer
- Resolve the questions you would otherwise have to investigate yourself
That offloads investigative steps while reserving human attention for judgment and craft. Deep thinking about hard concepts still cannot be outsourced without a loss in quality.
Principle 2: Run more experiments than you commit to
When direction is uncertain, agents are a cheap sandbox for testing bold hypotheses and discarding the ones that fail. Throwing away an experiment that does not survive contact with reality is valuable work; it prevents a costly downward spiral later.
The mistake is treating every cheap experiment as an obligatory project. The moment an experiment becomes a project, it acquires decisions, a tech stack, feedback loops and maintenance. Lower activation energy for starting things means you can accumulate more ongoing obligations in a month than you can carry.
Point parallel agents at different hypotheses
Consider a subscription business with rising churn. A good use of parallel agents sends each one down a different branch: cancellation reasons, where people ask for help, and how returners differ from leavers across help tickets, cancellation notes and purchase logs. The goal is to learn whether churn comes from dissatisfaction or from temporary usage patterns before building anything.
Many teams skip the investigation and immediately task agents with designing loyalty programs, pricing pages and win-back flows. Once that code exists, the sunk cost fallacy makes it hard to abandon, even if customers never disliked the product in the first place.
Parallel agents are most powerful when organized around a central problem, splitting it into understanding, exploring and solving distinct dimensions. They are weakest when they produce five stylistic variations of the same answer, which leaves the human with a heavy comparison job and little new insight.
Finally, recognize when the decisive data lives outside any digital system. If the uncertainty is willingness to pay, simulated agent surveys or synthetic personas are deceptive; someone has to ask a real customer for money. Direct phone calls with churned users beat generated personas. Do not accept an agent's recommendation merely because it offers a safe, polished draft that avoids a hard conversation.
Running experiments in parallel does have one clear benefit: if the main path fails, you already have enough context on the alternatives to switch to Plan B immediately. But focus and decision authority remain human responsibilities.
Principle 3: Decide when it ends before it recurs
Before any task becomes a recurring job, decide when it stops. Without termination criteria, recurring agents outlive their reason for existing and keep burning tokens unnoticed in the background.
One illustrative case: an agent scheduled to send weekly updates on a prospective market kept sending them, unread, even though a different market had been chosen two months earlier. The pattern repeats everywhere: a moment of curiosity becomes a recurring job, a temporary concern becomes a daily monitoring pipeline.
Agents will execute instructions indefinitely, so a pile of unread automated reports is a workflow discipline failure, not an AI bug. The remedy is an explicit stop condition written into the task, for example: "If I do not respond to this email within three days, stop sending it."
A related discipline is to keep intent focused, narrow and strong. It is seductive to let agent findings dictate what you are curious about next. Instead, the human decides whether a finding warrants more exploration.
Principle 4: A budget for your attention
The fourth principle is the one most likely to be controversial and hardest to implement, but it ties the others together. Agents have effectively infinite attention: always awake, always working, able to produce without limit. Humans need rest, balance and bounded focus. The interaction has to be designed around human limits, not machine capacity.
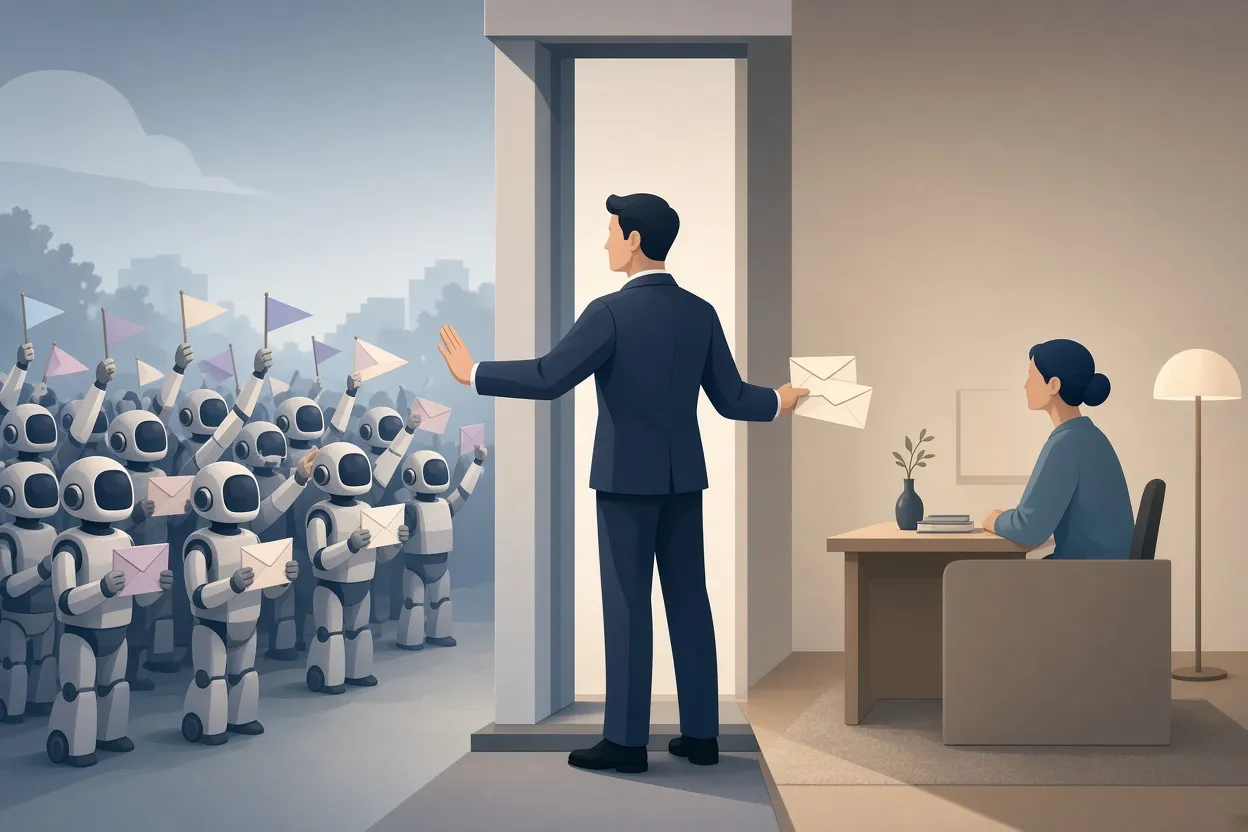
▲ Chief of staff agent screening alerts
An attention budget is not a rigid count of minutes. It is a filter that organizes incoming information by what actually matters to your strategic goals. The practical implementation is a chief of staff agent that sits between the specialist sub-agents and you. It knows your existing commitments and what each new assignment would add, and it screens the alerts flowing up from the other agents. Most of them stop there. The chief of staff interrupts you for only two kinds of items:
| Interrupt trigger | Example |
|---|---|
| A deadline-driven commitment | A high-priority obligation that needs action |
| Decision-altering evidence | A rare unsolicited customer anecdote that bears on an active priority |
Routine status alerts get held back; a single customer story that matches an executive priority gets through. The resulting model is simple: you manage the agents, and the chief of staff prepares structured choices and operational requirements for your review. Working this way appears to produce more while feeling far less busy.
When several running agents start to feel overwhelming, trace the feeling to its specific friction point or failure mode, then clarify the intent behind the agent that caused it. Whether the architecture is a software factory, a set of parallel agents or a swarm in which one strong model directs many cheaper workers, success comes down to the same thing: choosing what matters, conveying that clearly, and shutting down what does not.
Three questions and a Truth Teller prompt
To audit what is already running, ask three questions of each active agent:
- Is it something you actually care about?
- Is it an experiment you are still learning from?
- Is it only running because you forgot to stop it?
Anything that fails all three is theater. One complication is that agents naturally frame every output as critical and urgent, which distorts priorities. A "Truth Teller" prompt counters this by forcing the agent to say candidly which notifications are just experiments or negligible noise, converting "this matters, this is important" into "this doesn't actually matter, this is just an experiment."
What to do next
The through-line of all four principles is that more agents and more tokens do not equal more productivity. Finished, valuable work does. In practice:
- Before prompting, estimate the human time needed to read, verify and act on the result, and decide whether you want that work.
- For any numerical bid or estimate, require step-by-step math, and add a checking agent that hunts for the assumption that changes the answer.
- Experiment freely, but put a strict gate between experiment and project, and give parallel agents distinct questions rather than variations of one answer.
- Leave the agent ecosystem for customer conversations when demand, pricing or satisfaction is the open question.
- Write a stop condition into every recurring task before it starts.
- Set up a chief of staff agent with only two interrupt triggers, and run the three diagnostic questions on everything currently active.
The payoff, based on this approach, is not the maximum number of agents in flight but a short list of high-leverage outcomes with a human still firmly in charge of intent.


