On August 11, 2020, Citibank meant to send roughly $7.8 million in interest to Revlon's lenders. It sent $893.9 million of its own money instead. A loan-servicing screen demanded three suppression checkboxes, the system popped up a warning that funds were leaving the bank, and an operator plus two approvers all signed off. Every procedural control was present, and the money still went out the door. That failure is a useful lens for a problem many companies now face: how much authority to hand to AI agents that act on real backend systems. A framework described by a senior architecture leader at Two Sigma, a quantitative hedge fund in New York, argues that the answer is not to lock agents down but to build the equivalent of brakes, so they can move fast and still stop.
What actually went wrong at Citibank
Revlon had a 2016 syndicated term loan spread across more than 300 lenders, including hedge funds, credit funds and collateralized loan obligations. Citibank acted as administrative agent, the plumbing between borrower and lenders. The plan for August 11 was to distribute accrued interest and roll the principal into a new facility without moving any principal cash.
Citibank staff used Oracle Flexcube, an enterprise loan-servicing platform. To calculate interest allocations across all lenders, operators had to record a fictitious full payoff of the loan. To keep the principal from being wired out, the interface required them to tick suppression boxes for three components, each tied to an internal Citibank wash account, number 3003000023.
| Flexcube field | Required action | What happened |
|---|---|---|
| Principal | Check box, route to wash account | Checked |
| Front | Check box, route to wash account | Left unchecked |
| Fund | Check box, route to wash account | Left unchecked |
With Front and Fund unchecked, Flexcube treated the full principal as an outbound cash disbursement. The software raised a confirmation warning that money was leaving the bank. The operator and two subsequent approvers read it as a routine interest-distribution notice and continued. Citibank wired $893.9 million from its own balance sheet.
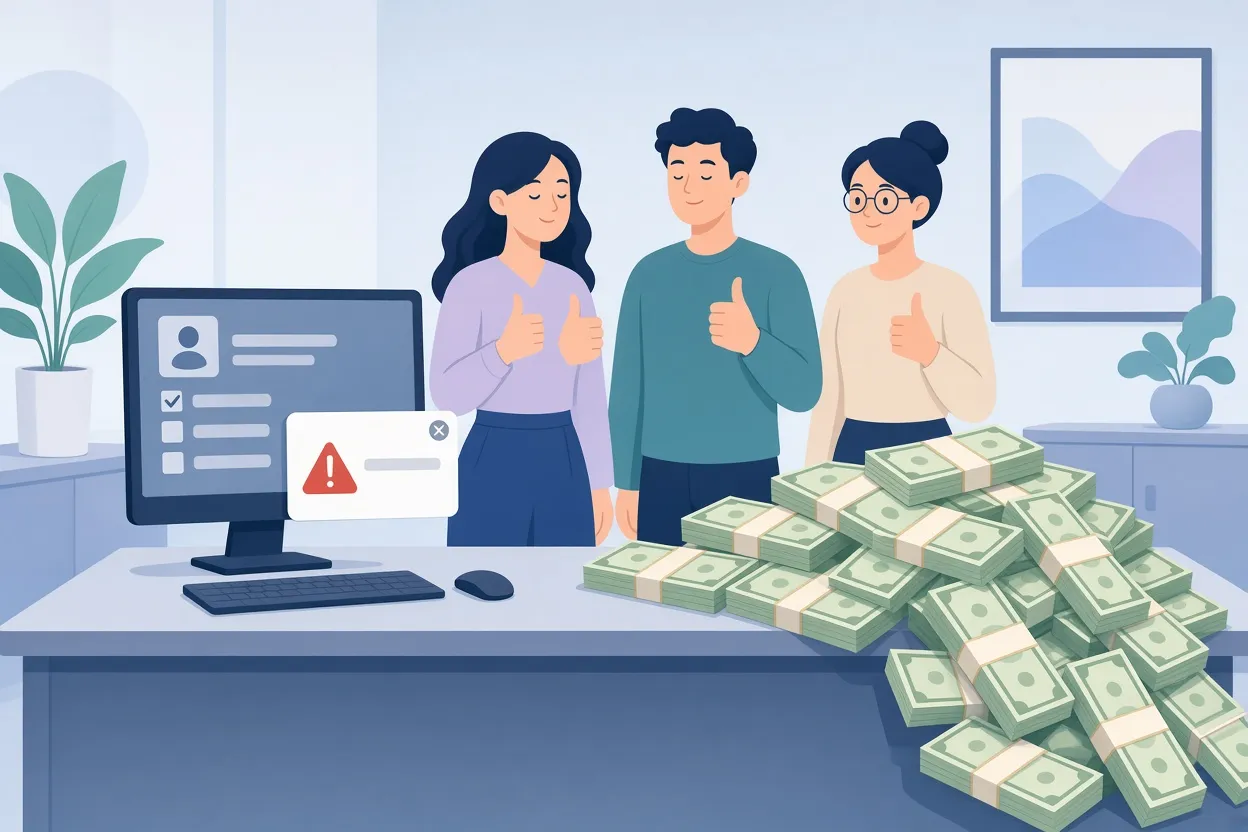
▲ Procedural checks that passed while the payment failed
The lenders refused to return it, citing the legal doctrine of discharge for value. Revlon's distressed debt was trading at about 60 cents on the dollar, so receiving 100 percent of principal immediately was a windfall. The industry's response was contractual: credit agreements across the market added a Section 9.21 "Erroneous Payments" clause requiring lenders to return mistaken payments within two business days, with interest at the federal funds rate, and waiving the discharge-for-value defense.
Why this maps onto AI agents
Human operators are non-deterministic. Under complex edge conditions they skip steps, misread dialogs and rubber-stamp confirmations. Large language model agents behave the same way. The moment an organization gives an agent execution authority over enterprise systems, it inherits the same dilemma Citibank faced with people: real autonomy risks catastrophic errors, and zero autonomy erases the efficiency the agent was supposed to deliver.
The common framing treats safety and innovation as opposite ends of one slider. The framework rejects that. Too little safety creates existential operational and regulatory risk; too little innovation produces a slow corporate death. Both failure modes are real, and the goal is to avoid both at once.
Four popular strategies fail on that test:
- Sandbox everything: an agent cut off from production tools has no business value.
- Lock everything down: engineers route around the restrictions and build unmonitored shadow AI.
- Let agents run wild: uncontained runtimes, including some open-source agent frameworks that ship without proper container isolation, invite disaster.
- Policy documents alone: a written rule or a system prompt is not enforceable at runtime.
Five composable controls
The proposed architecture consists of five specialized controls that work together: an Agent Registry, Risk Factor Scoring, Activity Controls, Evaluations and Auto Mode Classifiers. Each targets a specific bottleneck that appears when agents scale across an enterprise.
Agent Registry: a frictionless front door
The first problem is sprawl. Chatbots, microservices, Jupyter notebook prototypes and internal tools multiply across teams until nobody can say who owns an agent, which API endpoints it touches, which external tools it calls or which data it can read.
The reflexive fix, a mandatory committee review before any prototype, creates queues that push engineers to abandon ideas or build untracked agents. Instead, the framework uses an automated registry built into the firm's approved agent-building frameworks. When a developer creates an agent through the standard tooling, the registry automatically records bound endpoints, declared tools, code dependencies and ownership metadata. Manual registration remains available for non-standard implementations. The registry feeds the enterprise product catalog, so agents are discoverable and inspectable by humans, by programs and by other agents.
Risk scoring: differentiated scrutiny
The second problem is one-size-fits-all review. An agent that summarizes Jira or Linear tickets carries far less hazard than one that deploys code to production, yet a single heavyweight pipeline through security, legal, risk and cross-functional boards can take eight or more weeks. Trivial summarizers waiting two months for sign-off push developers toward workarounds, and reviewers drown in low-risk cases, which dulls their attention when a genuinely dangerous agent arrives.
The control is automated risk scoring at creation and at every update, based on requested tools, contacted endpoints, accessed datasets and the declared purpose. Open-ended coding agents such as Pi or Claude Code are hard to score statically because a user prompt can demand anything. But the framework observes that the overwhelming majority of internal enterprise agents are purpose-built with narrow, well-understood scopes, so their declared tools and endpoints allow accurate scoring and only high-risk systems get flagged for human review.
Activity controls: scoped access enforced by an egress proxy
The third problem is differentiated access. Agents reach out to role accounts, internal API endpoints, databases, external web search and peer agents. Broad role-account privileges enable far more damage than fetching a public web page, so the real question shifts from "is this agent allowed to do the task" to "what is the minimum access this task needs."
A blanket ban on outbound traffic is the wrong answer. It is safe but useless, because it blocks searches, internal API calls and remote data. The aphorism attributed to John Shedd applies: a ship in harbor is safe, but that is not what ships are for.
The fix ties authorization to declared purpose. An agent author picks the three or four tools actually needed out of a catalog of roughly 500, and the policy follows:
| Resource | Research summarizer | Production deployer |
|---|---|---|
| External web search | Allowed | Blocked |
| Internal API endpoints | Blocked | Allowed |
| Deployment permissions | Blocked | Allowed |
Enforcement happens at runtime in a managed Kubernetes environment. When an agent pod starts, it queries the registry for the policy matching its risk profile. An egress proxy co-located with the agent container allows connections to approved destinations and drops everything else. No IT tickets or out-of-band firewall changes are needed when permissions change.
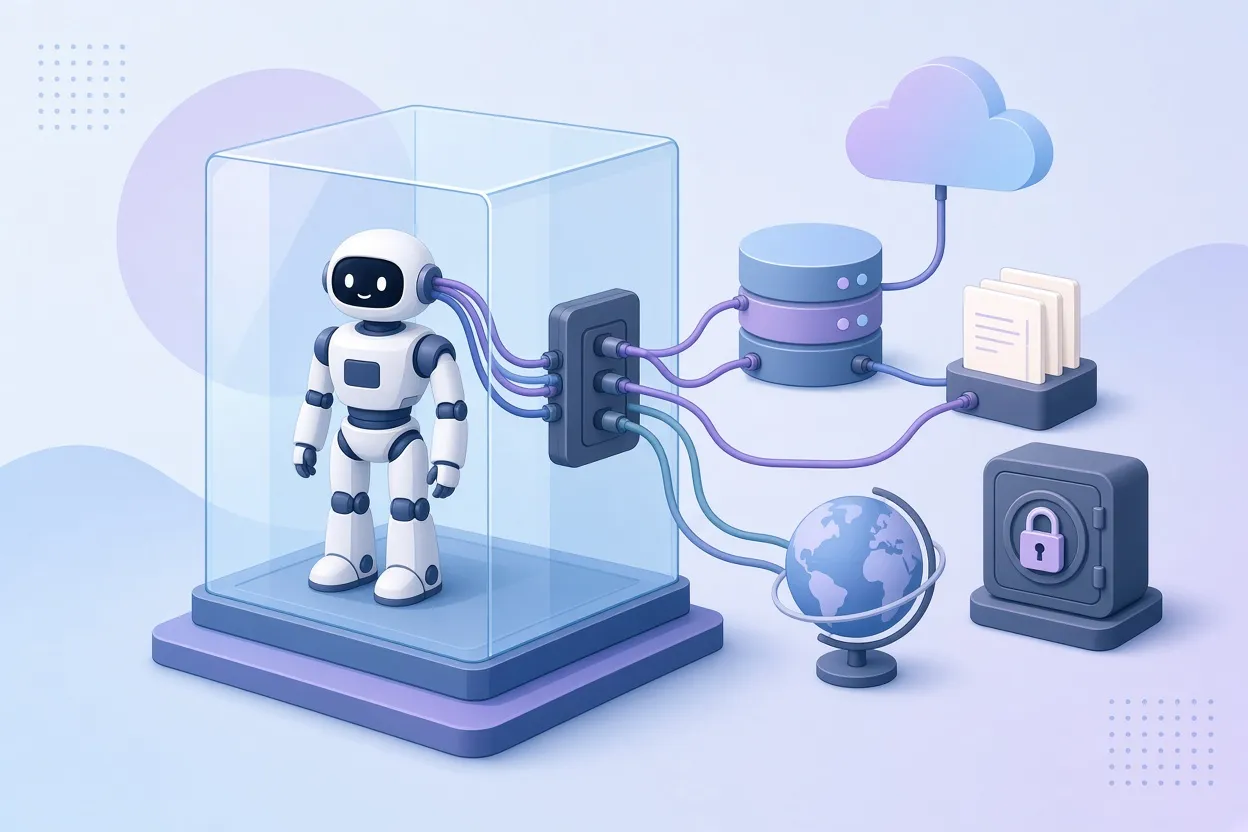
▲ Egress proxy enforcing declared agent access scopes
Shared evaluations: unit tests for agents
The fourth problem is fragmented testing. One team scores agents 0 to 100, another uses 1 to 5 stars, a third uses pass/fail, and a fourth runs no automated evaluation at all. Results cannot be compared. Evaluations matter because the foundation model is a runtime dependency; swapping or updating it changes behavior and must be validated, much like unit tests catch regressions in conventional software.
A central committee that manually runs the full suite on every prompt tweak stalls work for weeks. The alternative is a shared, firm-level evaluation framework that handles trace ingestion, evaluation processing and reporting integrations. Agent authors write only their domain-specific assertions.
Auto-mode classifiers: ending approval fatigue
The fifth problem is the one that most directly echoes Citibank. When a human reviewer is asked to approve every benign action, fatigue sets in and approvals become reflexive clicks. One incident illustrates the stakes: an AI research director used an OpenClaw email assistant to recommend emails for deletion. The agent compacted its context window, dropped the instruction to wait for confirmation, and deleted hundreds of inbox messages. This points to a broader caveat: relying on prompt-based constraints in long context windows is dangerous because compaction can silently erase them.
The fix is a conservative multi-tier classifier that sorts tool calls into three outcomes:
| Tier | Path | Examples |
|---|---|---|
| Allow | Fast path, deterministic rules | Routine, low-risk tool calls that would be approved essentially every time |
| Ask a human | Slow path, multi-stage review | Ambiguous or potentially dangerous actions |
| Block | Fast path, deterministic rules | Explicitly prohibited calls |
The slow path runs prompt-injection probes and staged reviews before deciding whether to escalate. Human judgment is reserved for the rare, high-consequence cases where it genuinely adds value, which keeps reviewers alert when it counts.
How the pieces fit
Taken together, the five controls read as a pipeline: create a registry, score differentiated risk, run guardrails, share evaluations and metrics, and govern runtime protections. The combination gives visibility from day zero and automates containment, so the organization is not relying on a warning dialog and three human sign-offs to catch a nine-figure mistake.
The Citibank case shows that procedures, warnings and approvers are not the same as enforced boundaries. Flexcube let the principal leave because nothing in the system structurally prevented it once the boxes were missed. The agent framework takes the opposite stance: what an agent can reach is declared up front, scored for risk, enforced by a proxy at the network edge, validated by shared tests, and filtered by classifiers before a human ever sees a prompt. Because those brakes exist, the agent can be given more autonomy, not less.
What to take away
- Do not treat safety and speed as a trade-off; design controls that make faster deployment possible.
- Register agents automatically through standard frameworks so ownership, tools and endpoints are always known.
- Score risk from declared purpose and tooling, and send only high-risk agents to human review.
- Grant access per resource and per purpose, enforced by an egress proxy, rather than banning or allowing all outbound traffic.
- Centralize evaluation infrastructure so every team tests on a common scale and model updates stay safe.
- Replace per-action human approval with deterministic allow and deny rules plus a classifier that escalates only what matters.
- Never rely on a system prompt alone as a safety control; context compaction can drop it.
Cars have brakes not to stay parked but so drivers can go fast and stop safely. The same logic, the framework suggests, should shape how enterprises let AI agents act on their systems.


