GPT-6 Sol’s most consistent advantage over GPT-5.6 Sol in a set of interactive 3D generation tests was speed. Given the same prompts at maximum reasoning effort, the newer model finished every compared scene sooner and generally produced stronger visuals. It did not always use fewer tokens, however, and the tests do not establish its cost per task. For anyone considering a model switch, elapsed time and actual spending deserve a place beside output quality.
What the comparisons measure
OpenAI positions GPT-6 Sol below its flagship GPT-6 Astra tier. To compare it with GPT-5.6 Sol, both models received identical prompts for code-driven 3D scenes with requirements such as camera views, moving objects and adjustable controls. Both ran at maximum reasoning effort, a setting that allows more work on a response. The reported token totals count units of processed text, including cached tokens; wall-clock time measures how long each run took from start to finish.
These are demanding coding tasks, not a complete measure of software development ability. A scene can look plausible while an on-page slider fails to change the live WebGL rendering—the browser-based 3D graphics—so the comparisons also consider whether interactive elements work.
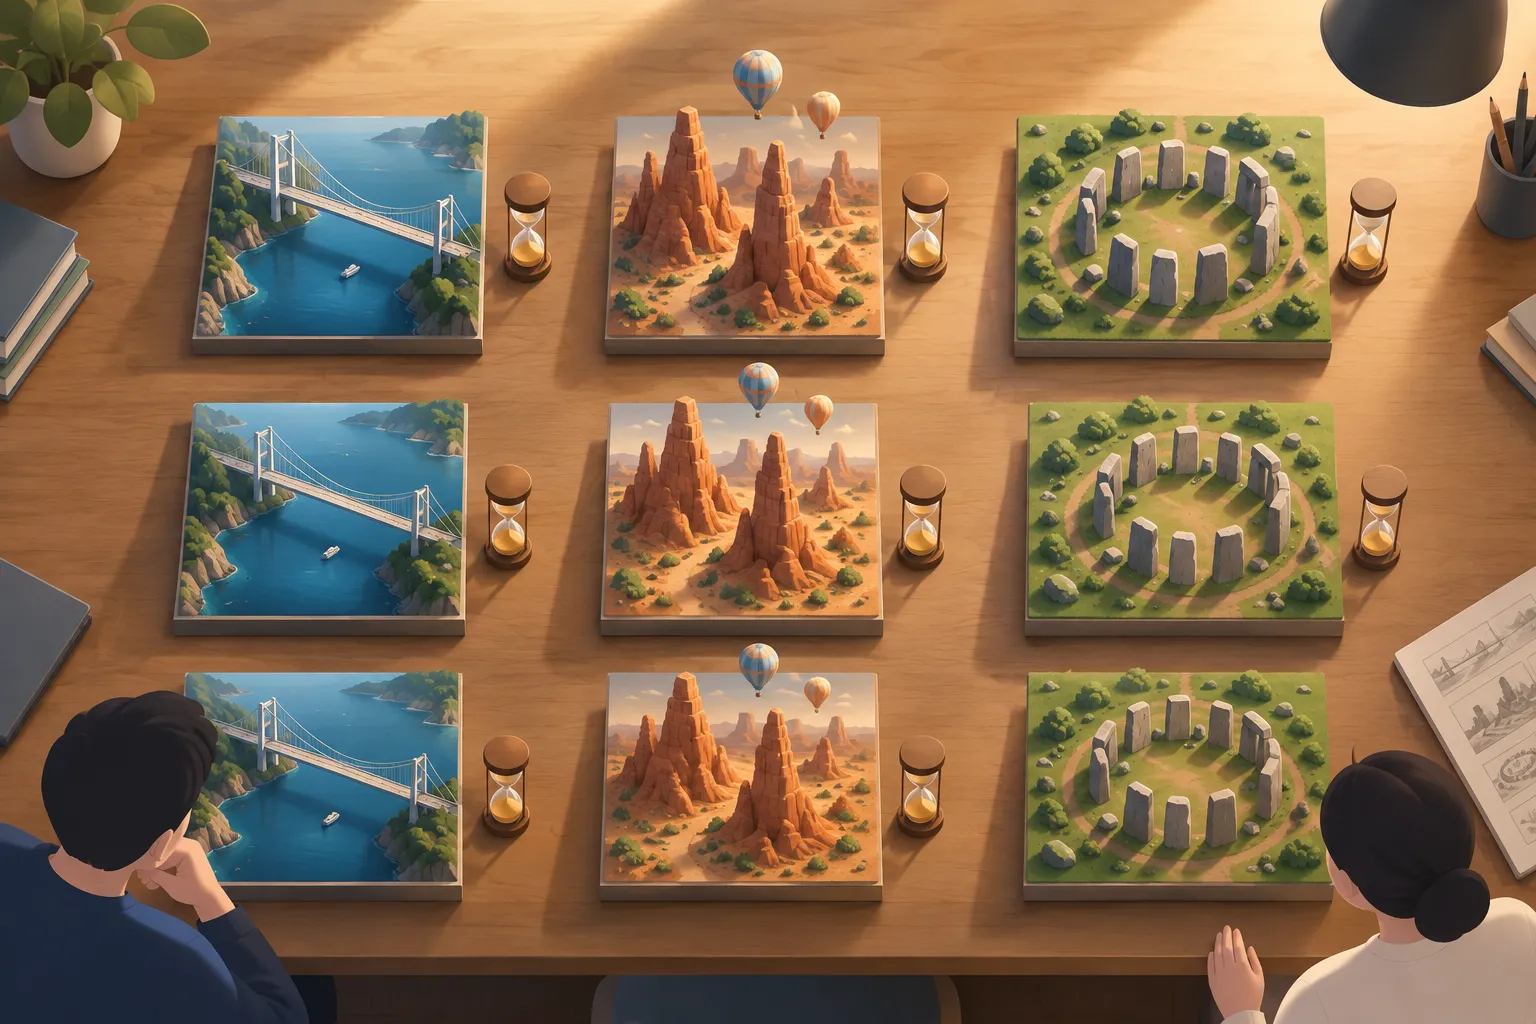
▲ Timed comparisons across 3D scenes
The timing and token figures show why speed and token use should be tracked separately. M means million tokens in the table below.
| Scene | GPT-5.6 Sol: tokens; time | GPT-6 Sol: tokens; time |
|---|---|---|
| Golden Gate Bridge | 9.4M; 1h 04m | 4.7M; 11m 35s |
| Cappadocia balloons | 13.1M; 53m 52s | 4.0M; 9m 58s |
| Stonehenge | 9.5M; 53m 49s | 3.5M; 11m 42s |
| Giant Pacific Octopus | 7.8M; 48m 39s | 6.6M; 9m 51s |
| Monet’s Water Lilies | 9.4M; 47m 15s | 17.1M; 25m 26s |
| Tower of Babel | 9.3M; 50m 10s | 20.3M; 24m 28s |
| Garden in the Rain | 4.6M; 48m 46s | 6.9M; 14m 16s |
| Manhattan aerial scene | 7.0M; 1h 41m | 24.2M; 44m 24s |
The Golden Gate Bridge prompt called for atmospheric controls and adjustable vehicle traffic. GPT-6 Sol took less than one-fifth as long and used half as many tokens. Its result had cleaner bridge geometry, stronger water reflections and more responsive controls; GPT-5.6 Sol produced an acceptable but flatter scene. The Cappadocia and Stonehenge runs likewise combined lower token counts with substantially shorter waits and more convincing terrain or stone arrangements.
Faster does not always mean fewer tokens
The octopus task offers a particularly clear warning against using token totals as a proxy for waiting time. GPT-5.6 Sol used 7.8 million tokens and took 48 minutes 39 seconds; GPT-6 Sol used a relatively close 6.6 million yet finished in 9 minutes 51 seconds. The newer result showed more natural tentacle curling and dynamic mantle movement, while the older one had stiffer arms.
One possible explanation for the timing gap is that GPT-5.6 Sol spent time repeatedly testing and rechecking parts of its code without making comparable progress on the final scene. That account is an interpretation of the runs, not a timing breakdown that assigns each minute to a specific activity. It does explain why monitoring elapsed time matters even when a token total does not rise proportionally.
Several prompts reversed the token-saving pattern altogether. GPT-6 Sol used 17.1 million tokens on the Water Lilies scene, against 9.4 million for GPT-5.6 Sol, but finished in 25 minutes 26 seconds rather than 47 minutes 15 seconds. It produced a navigable, painterly pond with lily pads and bridge reflections, where the older output had flat, incoherent tiles. The Tower of Babel and Manhattan runs also took more tokens on GPT-6 Sol while finishing sooner. In those cases, the extra tokens accompanied more detailed scenes; they were not evidence of lower token consumption.
The size of the time advantage varied. Some runs cut the wait by roughly four-fifths, while Water Lilies and Tower of Babel finished in about half the previous time. That variation makes the tested workload important: a single percentage cannot describe every prompt.
Cost remains a separate question
A separate agent-task comparison—covering AI systems that carry out multi-step work—reports the following median costs and net task improvement scores. It covers different tasks and mixes Max and High reasoning settings, so these figures are context for model selection, not prices measured for the scenes above.
| Model and setting | Median cost per task | Net task improvement |
|---|---|---|
| Claude Fable 5.1 (Max) | $4.40 | +13.7% |
| GPT-6 Astra (Max) | $3.94 | +12.7% |
| Claude Opus 5 (High) | $2.07 | +10.3% |
| GPT-5.6 Sol (High) | $1.03 | +8.0% |
▲ Agent task cost versus performance
A cost of roughly $0.40 per task for GPT-6 Sol has been proposed as a possibility if it approaches Claude Opus 5’s performance at a lower price. It is an estimate, not a measured entry in this comparison. Likewise, the scene tests’ token totals and completion times cannot establish what another user will pay for a different task. The practical question is whether a model produces an acceptable result within the time and cost limits of the work at hand.
How to decide whether to switch
GPT-6 Sol appears to offer a substantial improvement in waiting time for these complex 3D coding prompts, with visible quality gains in the compared outputs. Its token savings are inconsistent, and its projected cost advantage still needs measurement. Rather than defaulting to maximum reasoning, test a representative task at Low or Medium reasoning effort and compare it with the setting you use now. Record total tokens, elapsed time, actual task cost and whether the interactive controls work. Keep the model and setting that meet your quality needs without adding unnecessary wait or expense.