Once AI agents run on your computer all day, you are no longer its only user. Agents open browsers, start development servers and write piles of files, then often leave everything running when the task ends. When the machine slows down, the instinct is to price out a Mac mini, a Mac Studio or an NVIDIA system. But agent workloads tend to expand into whatever headroom you add, so a faster chip or more memory rarely fixes the problem for long. The cheaper first step is to find out what is consuming memory and disk on the machine you already own.
The model runs in the cloud, but the clutter lands on your desk
When you hand work to an agent such as Claude or Codex, the language model usually answers from the vendor’s data center. Much of the surrounding work runs locally, though: development servers, headless browsers (browsers without a visible window), compilers and test suites. Using Claude inside Google Chrome while browsing in the Zen browser, sending tasks to Codex and running a local transcription model can quickly push memory pressure up, and so can letting Claude Code render video in Blender while Codex works on separate code.
▲ Cloud inference, local workload
Young agent software can also eat disk space quietly, as public GitHub bug reports for Codex show:
| Reported problem | Scale |
|---|---|
| Crashpad crash-report folder with no cleanup on macOS | More than 50 GB |
| Git checkpoint data saved for each turn of a session | More than 100 GB |
| Data written to the SSD by one Codex setup | About 37 TB in 21 days |
Write volume like that can also physically wear out a solid-state drive. OpenAI has responded: Codex updates in June and October 2026 targeted log writes, Codex 0.160.0 added a way to reclaim unused log database space, and on October 13 OpenAI announced optimizations that cut disk usage by 60% for the ChatGPT and Codex desktop apps. Fixes from one vendor cannot clean up a setup that runs Qwen, Claude and Codex side by side, however.
Git worktrees, which give an agent a separate working folder for the same repository, each carry their own build caches and dependencies, so set an explicit policy for their disk use. As in the 1980s, memory and storage once again need careful budgeting.
Run a checkup before you go shopping
Read memory pressure, not memory used
On a Mac, open Activity Monitor and select the Memory tab. Watch the Memory Pressure graph: green means memory is used efficiently, yellow means you may need more, and red means the system is starved for RAM. On Windows, press Ctrl+Shift+Esc to open Task Manager and check the Performance tab. A high memory-used figure does not prove you need a new computer. Treat it as a cue to audit the software that is running.
Check storage and swap
Open the Apple menu, then System Settings, General and Storage. RAM is the workbench for active work, while storage is the warehouse for files and application code. When RAM runs out, macOS borrows part of the drive as swap memory, much like the temporary authorization hold a card issuer places to bridge a purchase.
Let an agent run a read-only audit
An agent can do the investigation, as long as the first pass changes nothing. Give it a prompt with three parts:
- Inspect the computer without modifying anything.
- Find the processes using the most memory and the storage paths taking the most space.
- Explain where each one comes from and propose specific fixes.
Run this before buying hardware or unleashing any automated cleanup script. It may turn up forgotten local development servers from past or abandoned side projects. Before stopping one, confirm which app it serves, whether the project is finished, and what can be regenerated. After that, check git worktrees and agent temporary folders regularly for stale build caches, checkpoints and crash logs.
Four house rules for sharing a computer with agents
Sharing a machine with agents is like sharing a house with roommates, and four rules keep it livable.
| Rule | What it means in practice |
|---|---|
| Know where the work happens | Separate cloud inference from the servers, browsers and builds running locally |
| Give every agent a stop sign | Define when a task is done so its processes shut down cleanly |
| Manage simultaneous demand | Queue heavy jobs and run only one or two at a time |
| Keep a maintenance plan | Schedule recurring checkups, often carried out by an agent |
Give every agent a stop sign
Unattended agent work often stalls halfway, leaving Chrome tabs, chat sessions and dev servers running. Modern agents are trained heavily with reinforcement learning with verifiable rewards (RLVR), which rewards a model when its result can be checked and pushes it to keep going until a task is complete. Without a boundary, that persistence becomes open-ended use of your machine. State the deliverable or milestone that ends each task, and tell the agent to shut its processes down there. Extra hardware buys only temporary room if orphaned processes keep piling up.
Queue the heavy work
If an agent has twelve documents to process, queue them and let only one or two run at a time. Ask the agent to profile the load: start with one active task, step up to two, and compare memory use and completion speed. Agents can watch utilization from inside the machine and warn you near the limit; if things slow down, tell them to scale back.
Core counts are a poor guide to capacity. Two agents waiting on a cloud model barely touch the processor, while two agents rendering video or running large builds can saturate every core. More cores and unified memory help only when the software can split the work in parallel, so profiling keeps you from paying for hardware that sits idle during API calls. Splitting work into stages also helps:
- Lightweight agents research and plan using cloud models.
- Heavy local jobs go into a queue.
- One big local build runs at a time.
Have agents reuse existing projects, browser sessions and folder layouts instead of rebuilding them.
Tune the local runtimes
- Docker Desktop: set a memory limit for its virtual machine and turn on Resource Saver mode to release idle resources.
- Ollama and LM Studio: adjust context length (how much text a model handles at once), parallel requests, and how long a model stays loaded.
A model kept in memory answers the next prompt quickly, but that RAM is unavailable to other apps. If you rotate between several models, weigh the unload timeout against the reload time.
Keep a maintenance plan
A machine you actively use needs immediate alerts when resources run short, while a background machine can follow a slower schedule. Today’s models handle file systems and terminal tools well enough to run recurring health checks, disk cleanup and performance monitoring, for example as a dedicated agent that looks after a Linux virtual machine. A regular checkup should track directories and flag unauthorized changes, preserve active unsaved work, and put people first with agent tasks in the background.
If you do need new hardware
Buy only after auditing and profiling your current setup, with an eye on how your agent work may grow in the coming years:
| Component | Baseline |
|---|---|
| Memory | 24 to 32 GB for typical agent work; 16 GB works but needs aggressive manual tuning |
| Storage | 512 GB to start; 1 TB or more for large datasets, high-resolution media and several local models |
Running a large language model locally adds its own fixed memory cost on top of the agents’ work. A high-memory workstation makes sense mainly if you rely on local open-weight models, whose trained parameters are publicly released, or need to load large data files and tools at once.
Why the Mac often comes first
AI agent tools tend to reach macOS six to eight months before Windows, and major AI labs largely develop on Macs first. The ChatGPT desktop app came to Mac in May 2024 and to Windows that October, and Cowork reached macOS in January 2026, a month before Windows. Apple Silicon’s unified memory also gives local models an edge over typical Windows setups.
At Apple’s retail prices as of October 16, 2026, the entry-level Mac mini with the M6 chip costs $899 with 16 GB of memory and 256 GB of storage, configurable up to 32 GB of memory. The Mac mini with M5 Pro starts at $1,699 and goes up to 64 GB for larger models. The base 16 GB and 256 GB configuration is tight and demands disciplined hygiene, and Apple does not allow memory upgrades later, so you must decide, and pay, at purchase. Let your own workflow, not isolated benchmark figures, drive the choice.
NPUs are not a shortcut
Neural processing units (NPUs), chips built for AI calculations, are specialized silicon, not a cure for multi-agent workloads. Performance depends on the whole system working together, from memory bandwidth to fast SSD storage and the processor pipeline. For local inference, the memory available to the accelerator is the most important limit.
Apple, NVIDIA or AMD
Picking a platform resembles choosing between an automatic and a manual transmission.
| Platform | Experience | Best fit |
|---|---|---|
| Apple Silicon, such as a high-memory Mac Studio | Least technical | Local open-weight models alongside everyday Mac apps on one machine |
| NVIDIA GeForce RTX with CUDA | Middle ground | Model fine-tuning and GPU developer tools |
| AMD Ryzen AI Halo or Omarchy | Most control | Up to 192 GB of unified memory for large models on Linux or Windows |
CUDA, NVIDIA’s platform for accelerated computing, is the standard ecosystem for serious local fine-tuning, meaning further training of an existing model for a specific task. The NVIDIA DGX Spark, running the Ubuntu-based NVIDIA DGX OS, and Omarchy, an agent-first operating system, suit people building their own agent-native infrastructure. Few people run AMD setups for AI today, but they are a viable option for very large memory pools.
Put your old computer to work
You have three paths: keep your current machine and profile it, upgrade parts where the hardware allows, or buy a new machine and hand the old one to your agents. Think of your computer as a house: the operating system is the building, CPU cores are the rooms, and memory and storage are the shared living space. Before paying for a bigger house, tidy the one you have and use the backyard shed: your old computer. Background agent jobs sent to the shed keep the main house from getting cluttered and slow.
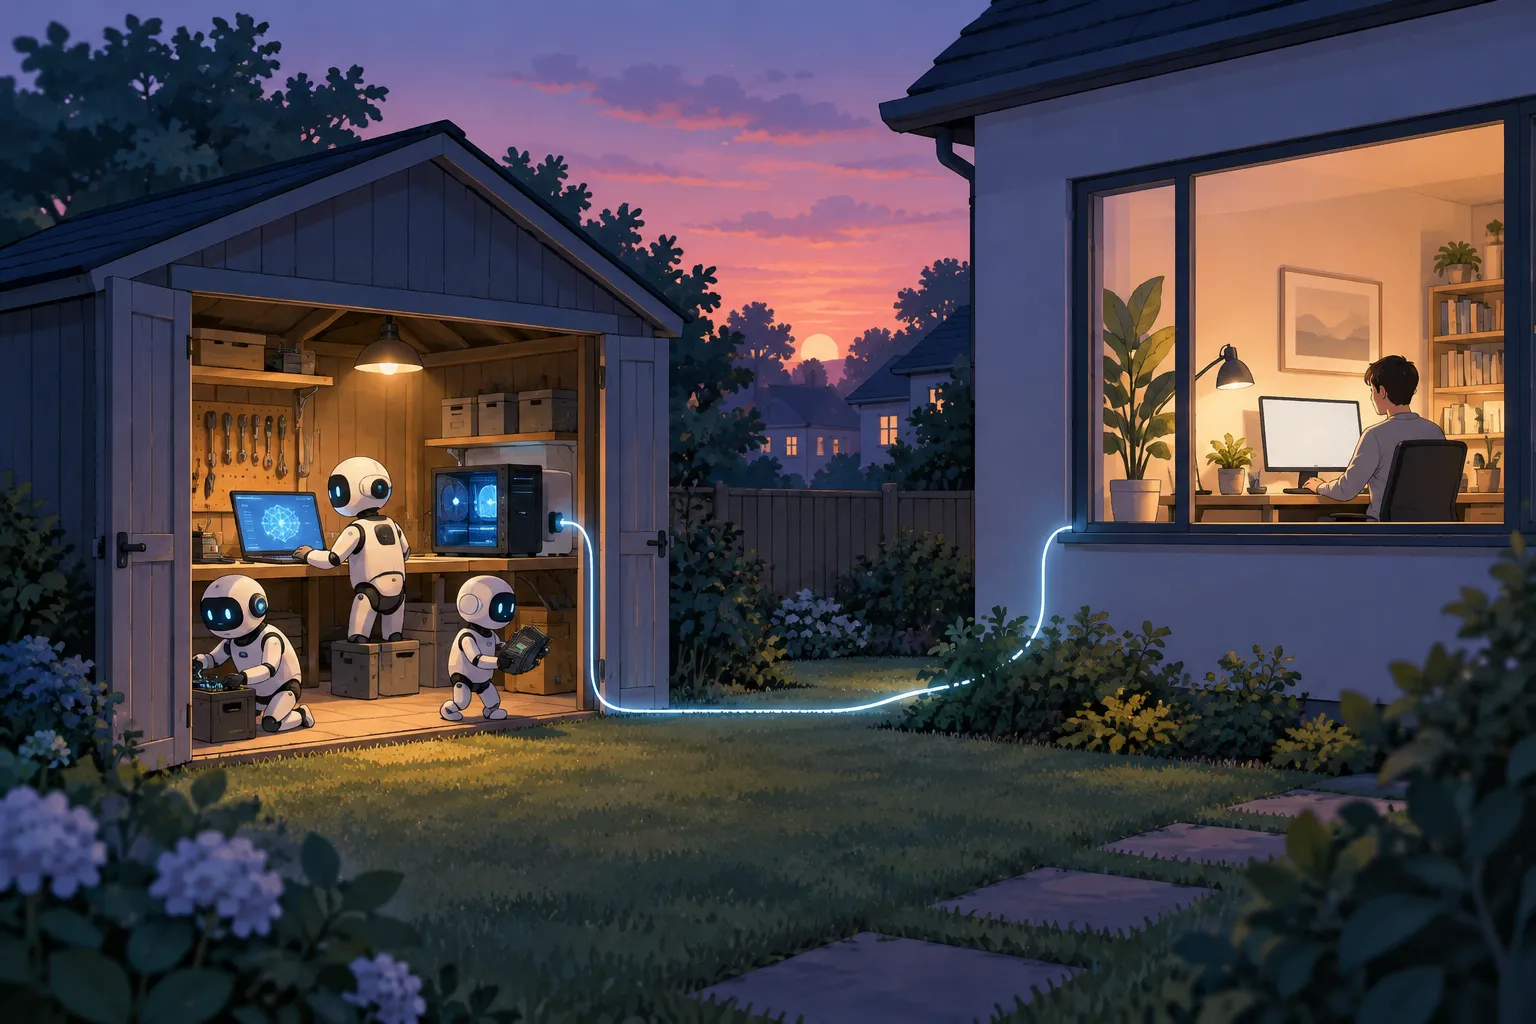
▲ An old computer turned agent worker
Tailscale links the house and the shed. It builds an encrypted private mesh network between your home computers and your devices anywhere, without exposing open ports. An unused Intel or M-series Mac mini, an old Windows laptop or an older MacBook can become a headless agent worker that runs heavy jobs around the clock, and a travel laptop can send heavy tasks back home. Even a Raspberry Pi can handle light tasks, small local APIs or an e-ink status display. Compared with a top-tier workstation, this can save hundreds or thousands of dollars.
The bottom line: diagnose first, buy second
You cannot simply spend your way out of agent slowdowns. A bigger machine without process hygiene just gives runaway processes more room, and once background jobs fill memory, opening one ordinary application can freeze the whole system. Start here:
- Check memory pressure, swap, storage and per-core CPU load.
- Ask an agent for a read-only audit before stopping anything.
- Give every agent task a stopping point and run heavy jobs one or two at a time.
- Tune Docker Desktop, Ollama and LM Studio, and schedule a recurring checkup.
- If you still need more, aim for 24 to 32 GB of memory and at least 512 GB of storage, and turn the old machine into an agent worker over Tailscale.