Plenty of Claude Code users try to shrink their bills by installing third-party GitHub repositories, add-ons or elaborate tricks. Most of that effort is likely unnecessary. Anthropic built Claude Code to keep usage down from the ground up, and each new release adds more of that behavior automatically. When the bill still runs high, the usual cause is a handful of everyday habits that quietly undo those savings, and most of them lead to the same expensive event: Claude rereading your entire conversation at full price.
Why each message costs more than the last
A token is the basic unit Claude bills for, roughly the size of a short word. You pay for tokens in one of two ways: by drawing down the fixed quota of a monthly Claude subscription, or by paying per token through an API key.
It helps to picture Claude as a brilliant contractor with total amnesia. It remembers nothing between messages, so every new message carries the whole conversation, from your first prompt onward, back to the model. Everything Claude takes in on a turn is its context, and you pay for the tokens it reads across that context. That is why a long thread costs more per prompt than a short one, and why a file loaded early keeps adding reading charges on every later turn. A fresh chat, by contrast, starts at zero tokens and costs nothing.
Prompt caching softens the blow
Claude Code counters this with prompt caching, a short-term memory that stores the part of the conversation that has not changed. Reading cached context costs roughly a tenth of the normal input price or less, and only new material is charged at full price.
The cache has two weak spots. A change partway through, such as switching between Claude’s Sonnet and Opus models mid-thread, invalidates it, and Claude Code then rereads the whole thread at full price. It also expires when you stop working:
| How you pay | Cache lifetime while idle |
|---|---|
| Monthly subscription | About 1 hour |
| API key or extra credits | 5 minutes |
Anthropic takes this seriously. An Anthropic Engineering write-up on building Claude Code describes engineers watching alerts on the cache hit rate, the share of input read from the cache, and declaring a SEV, a formal incident, when that rate drops too low. For users, the lesson is the same: a warm cache is the cheapest way to work.
What Claude Code already does for you
Beyond caching, three built-in behaviors keep the context from bloating:
- Connectors load lazily. Connectors plug Claude into apps such as Slack and GitHub, and each one comes with long usage instructions and schema definitions. Claude Code loads only the connector’s name up front and pulls in the details when the tool actually runs. To browse connectors for email, notes, calendars, tasks or code hosts, click the plus icon and open the connectors menu.
- Long output gets trimmed. When a terminal command or tool returns a huge block of text, Claude Code trims what enters the context window, the amount of text the model can hold at once, and saves the full output to a separate file. Claude opens that file only if it needs to inspect it.
- Subagents handle the heavy lifting. For large, messy tasks, Claude Code can spin up helper subagents in separate chats that return only a short summary to the main thread. Subagents burn tokens of their own, so they pay off on big, complex jobs rather than small scripts or quick questions.
Claude Code also compacts a conversation on its own when the context window nears capacity, a feature called auto-compact. What drives bills up is not a missing feature but habits that undercut these built-in savings.
Habit 1: Treating /compact as a diet
Running /compact to shrink a long chat feels like it should lower the bill. Picture someone who has spent 90 minutes and 60 messages building a landing page, notices responses slowing down, and compacts.
To write the summary that replaces the thread, Claude first has to read the entire conversation from start to finish one more time, much like an assistant who must go through a full meeting transcript before drafting the minutes. If the cache is still warm, that read is cheap. If it has expired, you pay full price for the whole history. Either way, the new summary starts a brand-new cache from scratch.
▲ A full reread behind every compacted summary
Compaction exists to free up room in the context window when you are near the limit or moving between major milestones. It is not a money saver, and auto-compact already handles the near-full case for you. If you do compact by hand, tell Claude what to keep, for example /compact keep the plan and the file names, and then confirm which requirements survived, because compaction can drop subtle instructions you gave early on.
Better moves than compacting
| Situation | What to do | What it does |
|---|---|---|
| You finished a task | Run /clear and start fresh |
Context drops back to zero |
| Claude took a wrong turn | Run /rewind instead of arguing |
Rolls the chat back to before the mistake |
| Long, ongoing work | Have Claude write a handoff doc, then /clear |
A new chat reads only what you chose to keep |
A handoff document should record the goal, what is done, what is left, the decisions made and what did not work. Because you can read and edit it before the next session starts, it gives you more control over what carries forward than a compacted summary, which appears to make it the better choice for complex projects. If you might want to revisit a conversation later, run /rename before /clear so you can reopen it from the sidebar.
Habit 2: Letting the cache go cold
Every conversation has an invisible timer running behind it. Spend the morning on a landing page, step out for an hour-long lunch, and the cache is gone when you return. Ask one tiny question and Claude Code rereads the entire conversation at full price before it builds a fresh cache for the messages that follow.
Recent Claude Code releases ease this. When a large chat has sat idle for close to an hour, Claude Code compacts it just before the cache expires, so on your return it reads a short summary instead of the raw history. The feature gets better with each release, but it still needs one full read to create the summary, and it can lose fine details along the way.
On pay-per-use API plans, where the cache lasts only five minutes, take breaks between finished tasks rather than in the middle of one.
Habit 3: Switching models mid-task
Each model keeps its own cache, and Opus and Sonnet do not share. Switching from Opus to Sonnet halfway through a session to save money backfires, because Sonnet cannot read the Opus cache and has to reread the conversation at full price. Pick one model before the job starts and stay with it.
The /model opusplan setting calls for the same care. It runs Opus in Plan Mode, where Claude works out the architecture and steps before touching any files, then switches to Sonnet automatically for the build. The split can be useful for planning, but every switch between the two models forces a full reread of the context.
Habit 4: Loading too much before you type
Open a new chat, type “hi,” and Claude Code has already loaded files before your prompt runs. The main one is CLAUDE.md, the project instruction file Claude Code reads at the start of every session and sends along with every turn after that. A 600-line CLAUDE.md is cheap while the cache is warm, but it gets reread at full cost every time the cache expires. Anthropic’s documentation recommends keeping the file under 200 lines and limiting it to the essentials.
A tree structure helps. Treat CLAUDE.md as the trunk that holds only top-level guidance, and move detailed rules for areas like design, testing or deployment into separate branch files. CLAUDE.md then works as an index that points Claude to those files, which load only when a job calls for them.
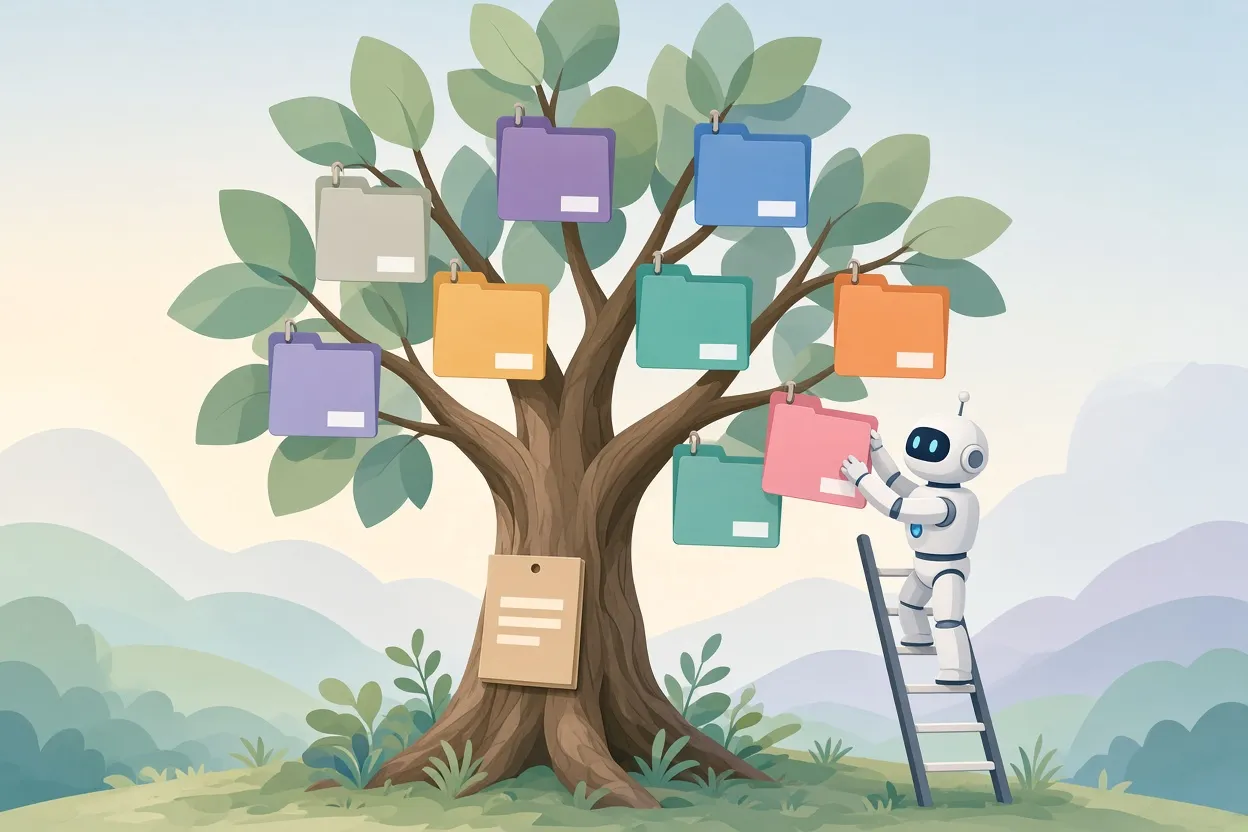
▲ CLAUDE.md as a trunk with task-specific branch files
The same thinking applies to other overhead:
- Skills with scripts. A skill, a packaged set of instructions Claude can call on, adds only a one-line description to the context until it is invoked. If the skill runs a local script for deterministic work, Claude never has to read the raw data. A weekly sales skill, for instance, can have a script total the spreadsheet rows on your machine and hand Claude a single line such as “42 sales, up from 38.” When a workflow keeps working, ask Claude to “turn this into a skill.”
- Idle connectors. Every connector you attach through MCP (Model Context Protocol, a standard for linking AI tools to outside apps and data) adds tokens to every session, and so does every skill. Run
/mcpand switch off the ones you are not using, such as calendar, notes, email or tasks. - Visibility.
/contextshows how much space user messages, files read, Claude’s answers and tools take up, and how much room is left./doctorchecks your setup, confirms that Claude Code is up to date and flags connectors you do not need. - Test output. Automated test suites can print hundreds of lines that say little more than “PASSED.” Claude Code trims only exceptionally long output, so those lines land in the conversation and get reread on every later turn. The fix is a hook, a filter that intercepts test output and cuts it down before Claude reads it. You do not have to write it yourself: ask Claude to “write me a hook that trims test results down to just the failures.”
Expensive defaults and vague prompts
On paid plans, Claude Code starts on Opus with thinking turned on. Thinking means Claude produces internal reasoning before its visible answer, and those reasoning tokens are billed as output, which costs five times as much as input. Running Opus with thinking on routine chores is like sending a top surgeon to take someone’s temperature.
- Use Sonnet for everyday coding and building.
- Use
/effortto set reasoning depth. The options run from low (“fast, for easy jobs”) through medium and high to max (“slowest, deepest”). Choose low for simple jobs such as renaming files. - Switch to Plan Mode before Claude edits files, so the two of you agree on the steps first.
Prompts matter too, though not in the way many people assume. The words you type are a tiny fraction of the context; what drives cost is where the prompt sends Claude’s attention:
| Prompt | Files Claude pulls into the chat |
|---|---|
| “Fix the bug” | Six: cart, checkout, header, footer, login and search |
| “Fix the date bug in the checkout file” | One: checkout |
Trimming words from a prompt saves almost nothing. Naming the exact file keeps Claude from scanning everything else.
Bottom line: three rules and a one-week check
Most surprise charges trace back to avoidable rereads: compacting, switching models, an oversized CLAUDE.md and a cache that went cold over lunch. Three rules keep the cache working for you:
- Use one model per job.
- Work steadily while the cache is fresh, and take breaks between tasks.
- Run
/clearwhen a job is done and start the next one in a new chat.
Beyond those, save /compact for when the context window is nearly full, keep CLAUDE.md under 200 lines, switch off idle connectors, and use Sonnet with low effort for simple work.
Then measure the result. /usage shows token consumption for today and the last seven days across skills, subagents and connectors. Record your numbers now, apply the changes, and check again in a week. Lower usage means more headroom on a subscription and a smaller bill on an API key. In the end, the cheapest tokens are the ones Claude can read from a warm cache.