Amazon Web Services is rebuilding parts of its cloud on the assumption that its busiest users will soon be AI agents rather than people. AWS CEO Matt Garman says coding agents now write code, pick databases and deploy infrastructure on their own, and that design choices made for human engineers, from account setup to database durability to permissions, no longer fit. He also laid out how AWS rations scarce GPUs and what role its in-house chips, Graviton and Trainium, now play.
A business still early in its growth
AWS runs at roughly $169 billion to $170 billion in annual revenue and is growing about 37%. Garman argues the cloud is still in its early chapters: most of the world’s enterprise workloads remain in on-premises data centers, and AWS is riding two waves at once, the steady migration of those workloads and the surge in demand from generative AI.
Startups remain central to that story. As a business school intern at AWS in 2005, Garman studied which customers would value cloud infrastructure first and concluded that startups would, because pay-as-you-go pricing removed the upfront cost of servers. He estimates that 30% to 40% of AWS revenue today comes from companies that began as startups on the platform. Startups push AWS services harder and faster than banks, hospitals or governments, and their requests often preview what large enterprises will want three to five years later.
What has changed is the size of those startups. Founders once raised about $10 million and slowly refined a single app. Leading AI startups now launch with $200 million in funding and $1 billion valuations, largely because training models and buying GPUs is so expensive. Yet Garman notes they still face the same basic hurdles: scaling, performance, security and access management.
What agents need from a cloud
Accounts that work in seconds
Setting up AWS has traditionally meant configuring a Virtual Private Cloud (VPC, a private network inside AWS), subnets, routing tables and IAM roles, the rules that decide who can do what. That overhead gets in the way when a developer hands cloud credentials to a coding agent such as Cursor, Claude or Codex and asks it to build and deploy an app.
AWS is rolling out a sign-up path that uses a standard identity such as a Gmail account, skips the credit card at first, and delivers a working account in under 30 seconds, with networking and security defaults configured behind the scenes. It is not a limited trial account. When a company grows and wants formal structure or fine-grained settings, it makes those changes in the same account, with no migration. The rollout is ongoing, so it may not be available everywhere yet.
Resources that are meant to disappear
AWS has long engineered services like Amazon Aurora for “five nines” (99.999%) of durability and availability. Agents often need something very different: a scratch database for an intermediate step, discarded seconds later. Wrapping that in multi-region replication is, in Garman’s view, over-engineering. AWS is exploring resources that can be created and torn down in milliseconds while still allowing long-term persistence when needed. The goal is for an agent to spin up and query a working database in under three seconds.
Narrow, temporary permissions and sandboxes
IAM permissions built for people or fixed service roles do not suit agents, which should not carry broad, long-lived credentials. AWS is building time-boxed permissions that give an agent only the tools and scope required for one subtask.
Agents also need isolation. Code they generate should run in a sandbox that starts instantly but keeps firm boundaries. AWS uses Firecracker, a microVM technology (a very lightweight virtual machine) it created about a decade ago, which boots quickly and isolates workloads strongly. Many of the new sandbox startups in the AI ecosystem build directly on Firecracker.
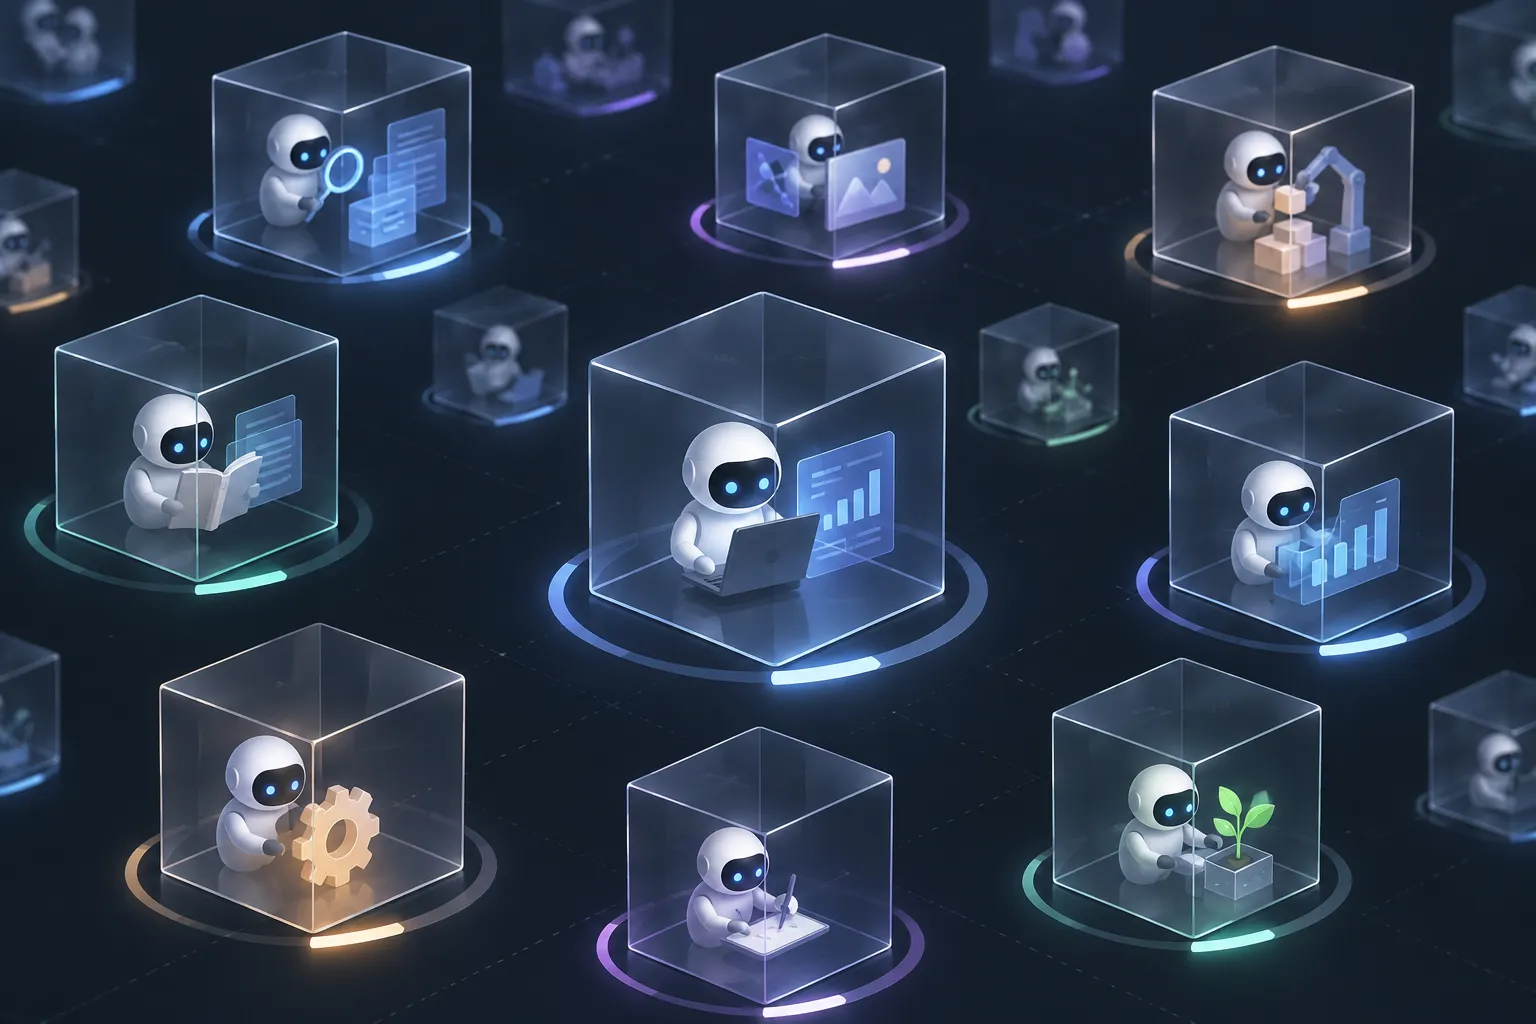
▲ Time-limited permissions and isolated sandboxes
Predictable tail latency
Agent workflows chain hundreds of operations in sequence, so rare slow responses, known as tail latency and measured at levels such as p99.9 for Amazon S3, add up. A person tolerates the occasional delay; an agent loop compounds it. Garman argues that AWS’s long focus on cutting tail latency is a real advantage for agent workloads.
AWS also offers agent-specific services. Amazon Bedrock and AgentCore handle orchestration, memory, gateways and permission boundaries between models and tools, and core services such as S3 are being tuned for non-human access patterns. A new preview service, AWS Context, adds a metadata layer over separate data stores like S3 and Aurora so agents can query them through one interface.
How AWS rations GPUs
Access to high-end GPUs is the biggest bottleneck for AI startups. AWS says it fulfills about 60% of customer GPU requests in some form, often by adjusting region, timing or cluster configuration.
AWS also avoids handing entire clusters to the biggest frontier labs such as Anthropic, OpenAI and Meta. It balances them with enterprise customers like Salesforce and JPMorgan Chase and sets aside capacity for early-stage startups. It keeps any single customer to a single-digit share of revenue, which Garman contrasts with specialized GPU clouds, often called neoclouds, where one or two AI firms can account for 30% to 60% of revenue.
The spending is enormous. AWS plans to add about 2 million NVIDIA GPUs over the next few years, and capital expenditure of about $220 billion was discussed for 2026. Garman rejects the idea of a bubble, saying enterprise customers report positive returns on production AI workloads.
Physical limits set the pace: power, data center construction, memory and chips, and skilled labor. Garman cites the theory of constraints from Eliyahu Goldratt’s book The Goal, which holds that solving one bottleneck exposes the next. Fix power and the limit moves to memory, TSMC packaging, high bandwidth memory (HBM) or networking gear. AWS now plans server capacity years ahead, for 2026 through 2028, and plans power generation and transmission up to 20 years out.
The custom chip strategy
AWS’s chip work began 13 to 14 years ago, when server virtualization was eating into compute. AWS moved network and storage virtualization onto dedicated cards and bought Annapurna Labs, a startup making cards with ARM cores. That led to the Nitro System and bare-metal instances, and scaling up those ARM cores produced the Graviton server CPU.
| Chip | Role | Key points |
|---|---|---|
| Graviton | ARM-based server CPU | About 20% lower cost and 20% higher performance; used by over 90% of the top 100 AWS customers |
| Inferentia | AI inference | Part of the AI chip effort started five to six years ago |
| Trainium 3 | AI training and inference | Third generation; capacity largely booked through late next year |
| Trainium 4 | Next-generation AI chip | Pre-announced |
AWS deploys more Graviton chips each year than any other server processor, and some customers have halved their server counts after moving whole fleets. Garman calls Graviton the easiest way to lower an AWS bill.
Despite its name, Trainium has become one of the most cost-effective inference chips, according to AWS. Most Amazon Bedrock inference runs on it, and Anthropic and OpenAI both use Trainium. Garman even concedes that AWS is bad at naming products, pointing to the confusion between Inferentia and Trainium.
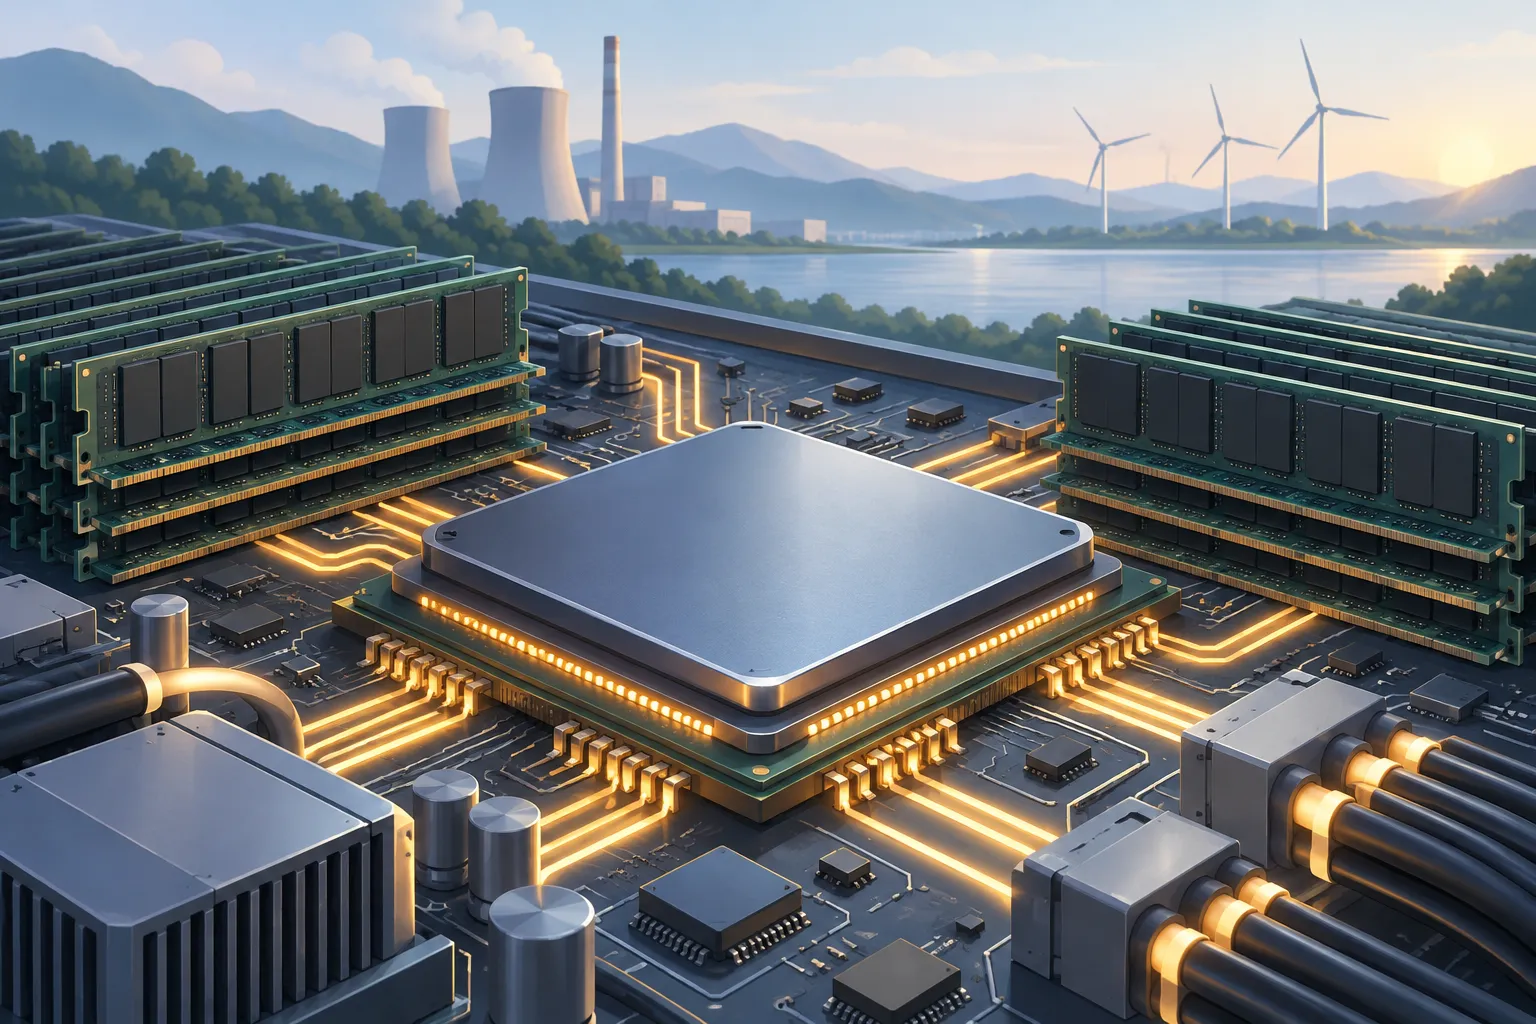
▲ Custom chips and the power bottleneck
Trust is the real barrier for enterprise agents
Most enterprise agents today keep a human in the loop and simply copy an employee’s step-by-step routine. Garman urges companies to start from the desired outcome instead and let agents explore dozens of paths in parallel.
The main obstacle to full autonomy, he says, is trust rather than model capability. Companies reasonably fear an agent with the wrong permissions deleting a production database, so guardrails, fine-grained access control and rigorous evaluations must come first. AWS sends forward-deployed engineers into 45-day engagements to help customers build evaluation suites and data labeling, then hands ownership to the customer’s own team rather than locking it into years of consulting.
On data, AWS stresses that customer prompts and inputs on Amazon Bedrock stay inside the customer’s VPC and are never shared with model providers. Garman reports strong Bedrock growth, including workloads moving from OpenAI’s APIs and fast adoption of Anthropic’s Claude models and open-weight models. For security, AWS introduced Continuum, which uses advanced models to find vulnerabilities and rank them in the context of a customer’s environment, on the view that defense has to run at machine speed.
Inside Amazon, every corporate employee has Amazon Q. HR teams finish planning work in hours instead of weeks, finance teams use agents to review tax and regulatory rules, and engineers increasingly direct fleets of coding agents. Work that once took 10 engineers now goes to pods of three or four.
What builders should take from this
AWS is betting that agents will become the cloud’s main users. If you build on AWS, a few practical steps follow:
- Give coding agents narrow, short-lived permissions instead of broad admin access, and run their code in sandboxes.
- Skip production-grade replication for scratch data that agents use briefly.
- For multi-step agents, compare services on p99 and p99.9 latency, not averages.
- When you need GPUs, stay flexible on region and hardware configuration.
- To cut costs, check which workloads can move to Graviton.
- When deploying agents in a company, redesign the process around outcomes and set up evaluations and guardrails before going to production.