Claude Sonnet 5.5 leads Claude Opus 5.5 on one coding benchmark, and its input and output token prices are half as high. Those two facts do not mean every coding task costs half as much. Cache reads carry the same price for both models, while the amount of computation used for a task can change its total cost dramatically. The practical comparison is therefore about both accuracy and spending at the effort setting a team actually uses.
Anthropic released Claude Sonnet 5.5 on September 28, 2026, a week after Claude Opus 5.5. The new model is presented as roughly 30% faster and 30% less costly than Claude Sonnet 5 on typical workloads. That comparison with the previous Sonnet model is separate from the per-token price comparison with Claude Opus 5.5.
Coding results depend on the test
Agentic coding benchmarks test how an AI system handles software tasks that require multiple steps. Claude Sonnet 5.5 reaches 70.6% at maximum effort on Terminal-Bench 4.0, compared with a reported 54.4% for Claude Opus 5.5. It also improves sharply on Claude Sonnet 5, which scores 10.2% on that test. But Claude Opus 5.5 leads on the other two coding benchmarks in the comparison.
▲ Different outcomes across coding tests
The results do not support a blanket claim that either model is better at coding. They show different outcomes across tests, and Claude Sonnet 5.5’s own score changes with its effort setting—the amount of computation it uses for a request.
| Coding benchmark | Claude Sonnet 5.5 | Claude Opus 5.5 |
|---|---|---|
| Terminal-Bench 4.0 | 70.6% at max effort | 54.4% |
| CursorBench 4.0 | 52.9% at high effort; 51.5% at max | 57.8% |
| FrontierCode v1.1 | 49.4% at high effort; 46.2% at max | 54.4% |
Terminal-Bench 4.0 shows Claude Sonnet 5.5 improving as effort rises from medium to maximum. CursorBench 4.0 and FrontierCode v1.1 show why that pattern should not be assumed for every coding task: both report a lower Sonnet score at max effort than at high effort. The Terminal-Bench lead is notable, but a single benchmark cannot establish how the models will rank across a team’s own software work.
Half-price tokens are not half-price tasks
An API charges for tokens, the units of text a model processes or generates. Claude Sonnet 5.5’s listed rates are exactly half of Claude Opus 5.5’s for cache writes, input tokens and output tokens. Cache reads—reuse of stored input—cost the same for both.
| API category | Claude Sonnet 5.5 per million tokens | Claude Opus 5.5 per million tokens |
|---|---|---|
| Cache reads | $0.20 | $0.20 |
| Cache writes | $2.50 | $5.00 |
| Input | $2.00 | $4.00 |
| Output | $10.00 | $20.00 |
These rates make the “half the cost” description accurate for three token categories, not for the full bill in every workload. If cache reads form part of a task’s usage, that part does not get cheaper. If a setting causes the model to consume substantially more tokens, a lower rate may not translate into a lower cost per completed attempt.
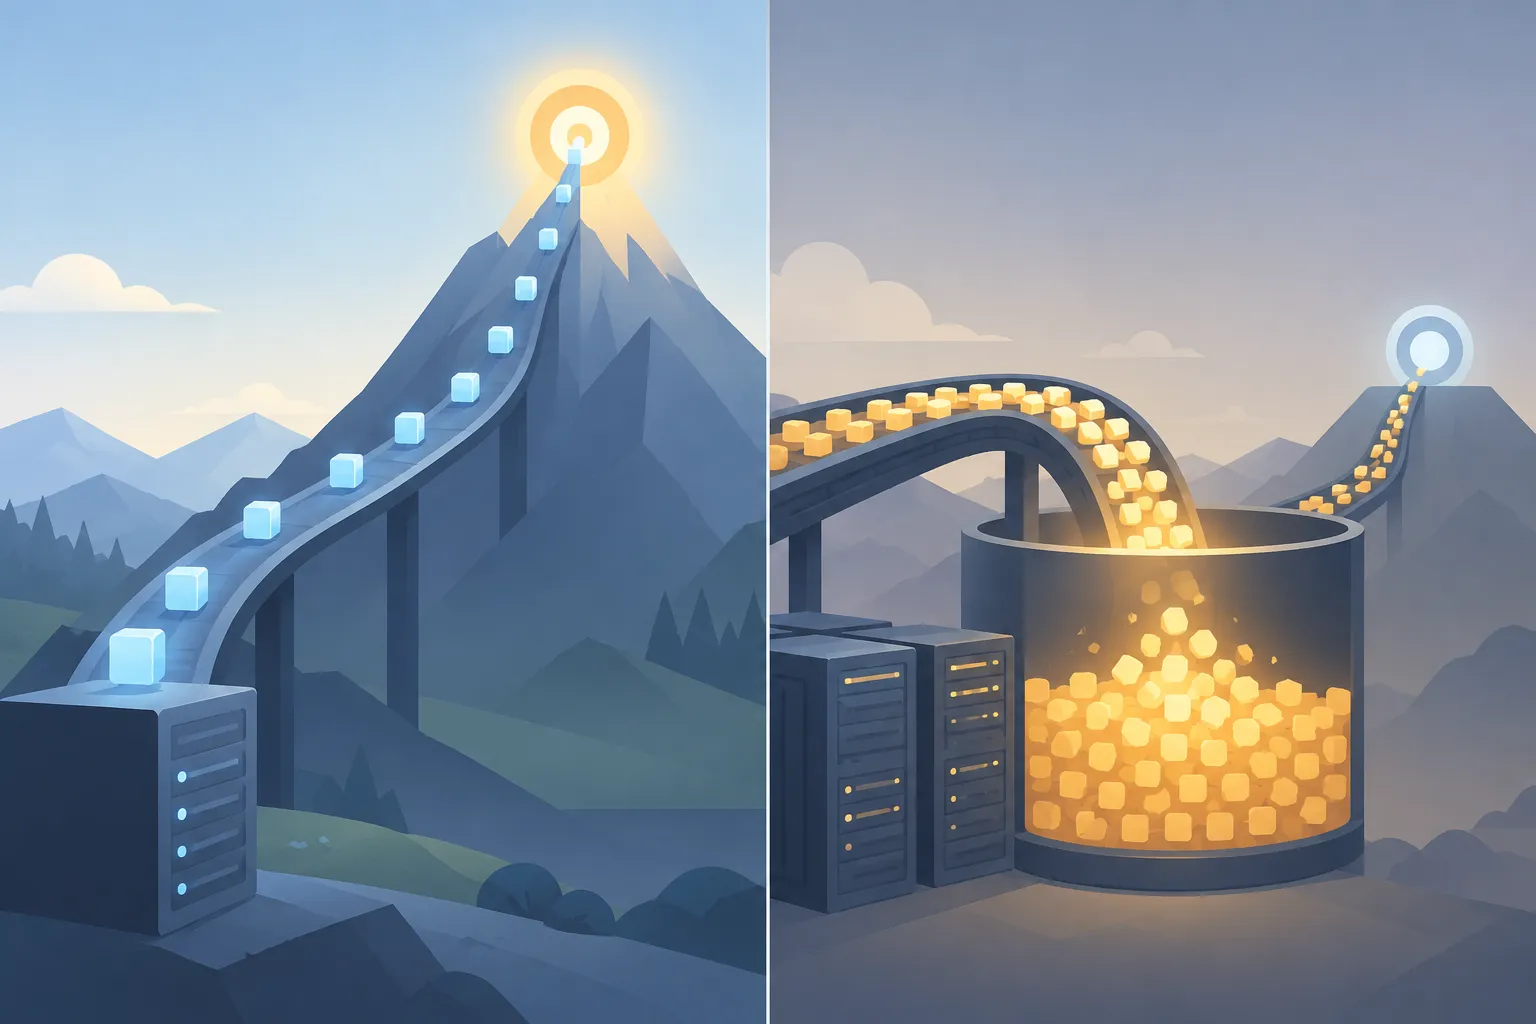
▲ Effort, accuracy and task cost
The benchmark costs make that distinction concrete. At maximum effort on Terminal-Bench 4.0, Claude Sonnet 5.5 averages $12.54 per attempt, slightly more than Claude Opus 5.5’s $11.24 at its maximum setting, despite Sonnet’s lower listed token rates. On FrontierCode v1.1, Claude Sonnet 5.5 costs $0.42 per task at high effort and scores 49.4%. At max effort, its cost rises to $21 per task while its score falls to 46.2%. That is a 50-fold cost increase for a worse result on that test—not a general price forecast for coding work.
High effort is consequently a more useful starting point than max for evaluating Claude Sonnet 5.5 on coding tasks. Extra-high effort is another option worth testing, but the reported FrontierCode cost and score comparison is between high and max. Teams need their own task results before treating either setting as the best choice for production.
Where the broader value case stands
Coding is not the only relevant workload. On GDPval-AA, a knowledge-work evaluation spanning 44 occupations, Claude Sonnet 5.5 scores 1844, close to Claude Opus 5.5’s 1846 and above Claude Sonnet 5’s 1449. That result may make the lower token rates attractive for daily work, but it does not resolve the coding-benchmark differences or establish a task-level cost saving.
Safety settings can also affect which model handles a request. When a request triggers high-risk cybersecurity or biological safeguards, Anthropic’s system falls back from Claude Sonnet 5.5 to Claude Sonnet 5. Organizations evaluating permitted work in those areas should account for that possibility when interpreting results.
What to check before switching
Claude Sonnet 5.5 offers a strong Terminal-Bench 4.0 result and lower prices for most token categories, while Claude Opus 5.5 leads the other reported coding tests. For a coding workflow, start by comparing the models on representative tasks at a stated effort setting. Record accuracy, tokens used and total cost per attempt—not just the published per-token rate. Test high effort before assuming max will help, and include cache-read usage when estimating savings. That is the way to tell whether the lower API rates produce a lower bill for the work that matters.