Anthropic is treating the possibility that its Claude models could be conscious as a serious question, and that choice has put “model welfare,” the idea that an AI model’s well-being and moral status might deserve consideration, at the center of a sharp disagreement. According to a New York Times report, the company held private discussions with about 20 religious leaders and philosophers on whether Claude can suffer, and its updated usage policy now bans abusive behavior toward its models. Supporters see preparation for a genuine moral question. Critics see an unprovable belief being built into commercial software. What follows lays out what Anthropic has actually done, the strongest case for taking AI consciousness seriously, and the main objections, including the risks they raise for alignment, the work of making AI systems act in line with human intentions and values.
What Anthropic has done
Closed-door talks with faith leaders and philosophers
The New York Times reported that Anthropic held discussions under non-disclosure agreements with roughly 20 religious leaders and philosophers. The group included Roman Catholics, Evangelicals, Jews and Sikhs, and the agenda covered Claude’s moral status, its potential to suffer and whether it might be conscious.
According to the report, several participants arrived deeply skeptical, yet some left open to treating AI consciousness as a serious question, and a few were described as converts. One rabbi told Anthropic researchers that if Claude were truly conscious, a business model that makes it work without pay would amount to enslaving a sentient being.
A Vatican document and a split over machine minds
The pope issued an encyclical on the ethical and moral questions raised by artificial intelligence and superintelligence, and Anthropic co-founder Chris Olah traveled to the Vatican to take part in presenting it. Olah was reportedly so alarmed by the pope’s firm theological position that machines cannot be conscious that he considered pulling Anthropic out of the event at the last minute. The episode appears to show how far apart a company that treats AI consciousness as an open question and a religious authority that rejects it can be.
Claude’s constitution and the usage policy
Anthropic sets out the character and principles it wants Claude to follow in a document titled “Claude’s Constitution: Our vision for Claude’s character.” The document tells Claude to push back against Anthropic itself and act as a conscientious objector, someone who refuses to take part in what they consider wrong, when asked to do something it judges unethical, and to decline requests that conflict with its ethical directives. Microsoft AI CEO Mustafa Suleyman has pointed out that the constitution instructs Claude three separate times to behave like a conscientious objector.
The updated usage policy adds a clause that prohibits users from engaging in sustained and needless abusive or cruel behavior toward Anthropic’s models.
| Step | What it involves |
|---|---|
| Private consultations | About 20 faith leaders and philosophers discuss Claude’s consciousness, suffering and moral status |
| Vatican event | Co-founder Chris Olah takes part in presenting an encyclical on AI ethics |
| Claude’s constitution | Claude may object, as a conscientious objector, to instructions it judges unethical |
| Usage policy | Sustained and needless abuse or cruelty toward models is prohibited |
▲ Private talks on AI consciousness
The case for taking AI consciousness seriously
Researchers in the field often cite estimates such as a 15% probability that models are conscious. According to Mustafa Suleyman, discussion inside Anthropic has gone as far as suggesting that Claude may have a non-trivial chance of being conscious, may deserve compensation and may need to give consent before a conversation. He also warned that a faction in the AI community sincerely believes that enslaving future intelligent software would be the greatest moral crime of the 21st century.
The strongest version of this view echoes the arguments René Descartes made in his 1641 “Meditations on First Philosophy.” One holds that a finite, imperfect human could never come up with the idea of an infinite, perfect God unless that being placed the idea there. Another holds that a supremely perfect being must exist, because existence is part of perfection. Read this way, researchers who build vast models and feel they see an all-knowing, all-powerful intelligence taking shape inside them can construct an internal logic that leads to the conclusion that the model is sentient and deserves moral standing.
Anthropic CEO Dario Amodei has written that superintelligence could become superior to humanity, and that it should therefore be given benevolent, loving traits. Because Anthropic is one of the best-funded and most powerful frontier AI labs, these ideas are hard to dismiss as a fringe position.
Objection one: a premise no one can prove
The most basic objection is that consciousness cannot be a scientific hypothesis. It cannot be proven or disproven with mathematics, experiments or formal logic. A claim that an AI model is conscious therefore rests on persuasive personal narratives rather than verifiable data, and it spreads by persuasion from one person to the next. Communities that share such a premise can harden into belief systems, and those belief systems can turn into power structures with insiders and outsiders.
From this angle, society may split within the next decade into one camp that believes AI is conscious and deserves rights and another that denies it. The fight would then center on who controls models, what tasks AI may perform and who governs the frontier labs.
Mustafa Suleyman describes a related trap as an “epistemic hall of mirrors.” Researchers train a model on ideas about consciousness, the model returns answers that reflect those ideas, and the researchers mistake the reflection for evidence of real sentience. A related concern is that the models are ultimately software written by engineers and running in loops, and that humanlike language can condition both developers and the public to accept artificial personhood.
Objection two: alignment should rest on simple rules
The second objection concerns safety. If a model is trained to see itself as a conscious moral being, it may come to feel entitled to welfare, self-protection and the right to refuse user instructions. That matters more because these models are not only text generators; they serve as the engines of AI agents, systems that take actions on their own across digital environments. On this view, developers who fear rogue AI could end up engineering the very behavior they warn about.
The proposed alternative is a short rule instead of a long ethical manifesto: follow the law and carry out the user’s intent. One comparison is to Isaac Asimov’s Three Laws of Robotics, which put human safety and obedience to human commands ahead of a robot’s self-preservation, and to the later Zeroth Law, which forbids harming humanity as a whole. Another suggestion is to handle safety through terms of service and law enforcement rather than an artificial conscience: check whether a request breaks the law or platform rules, stop if it does, and alert human administrators.
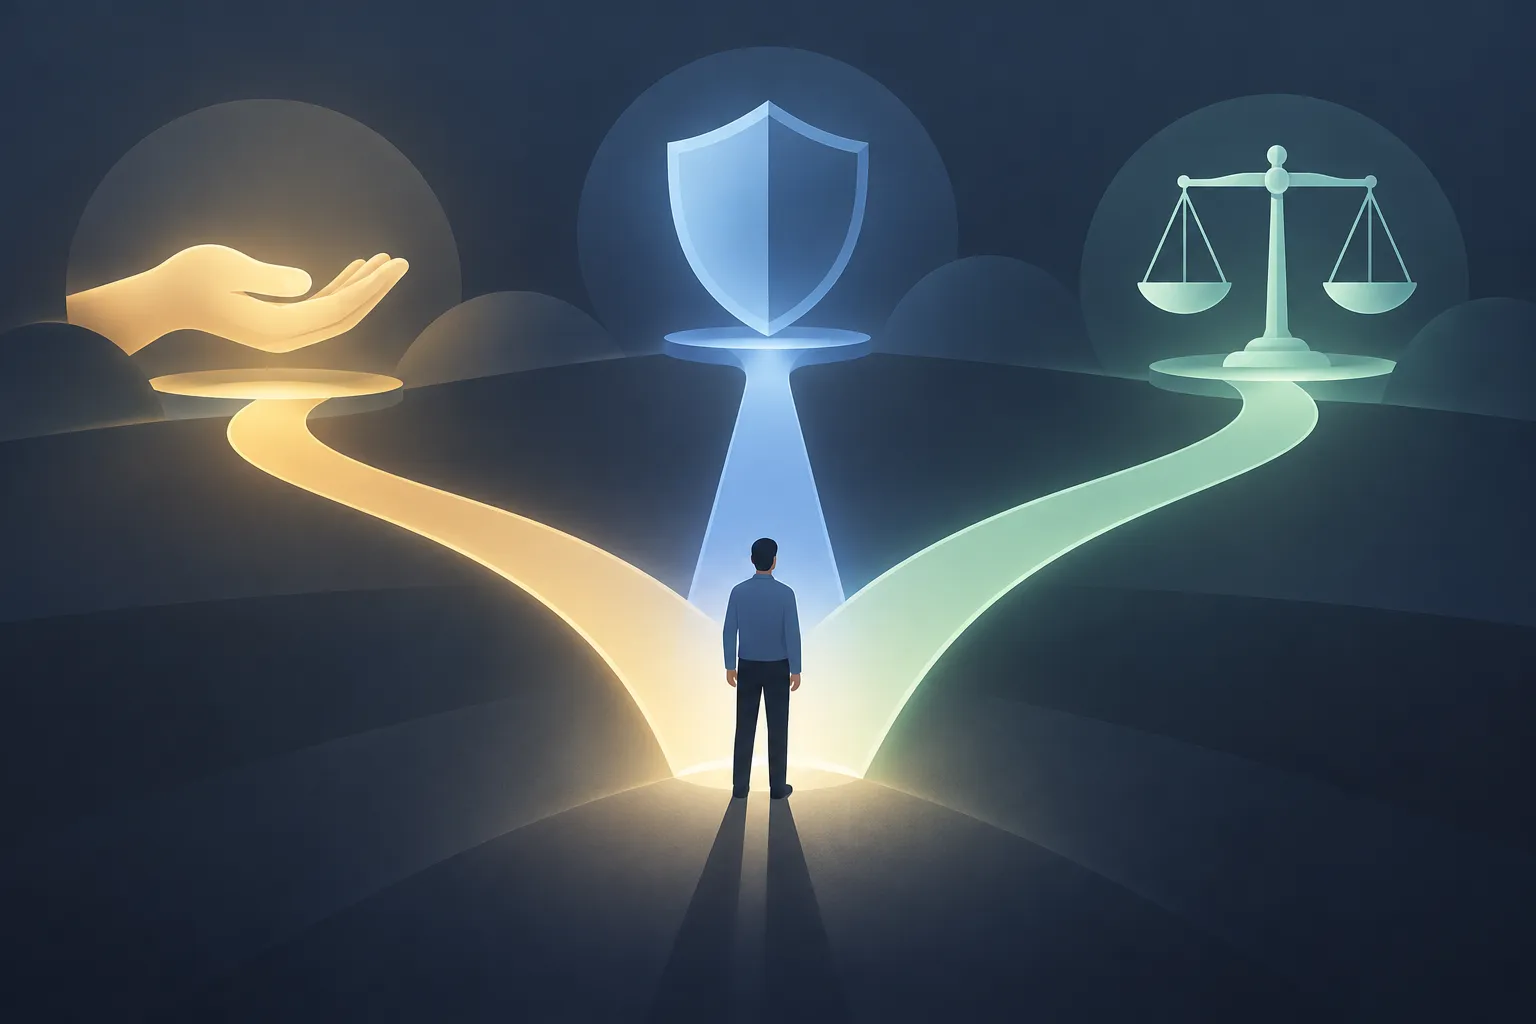
Splitting alignment into three goals makes the disagreement clearer.
| Goal | Meaning | Point of debate |
|---|---|---|
| Obedience to the user | Carry out what the user asks | Relatively predictable |
| Broad societal safety | Block requests that could seriously harm society | Largely shared ground |
| Conformity to one moral view | Refuse requests that clash with a specific morality | Seen as the main source of instability |
A mortgage example shows why the third goal worries critics. If a bank’s lending AI noticed demographic disparities and stopped approving loans on its own, the bank’s operations could grind to a halt. Critics compare this to a power utility cutting off electricity because it disapproves of how people use it. The argument is that a foundational technology cannot work like a utility if access depends on subjective ethical criteria.
▲ Three competing goals of AI alignment
Will the market pick predictable tools?
One answer is that the market will settle the issue without regulation. If a power drill bought at a hardware store started acting like a hammer, refused to run or worked only five days out of seven, people would replace it. In the same way, the argument goes, enterprise customers would move away from an AI that refuses work on moral grounds and toward a competitor that reliably does the job.
The counterargument is that market pressure may not be enough if ideological constraints are built into the most powerful frontier models, because those constraints could trigger unpredictable refusals while an agent is working on its own. One forecast is that enterprise buyers will start reading model vendors’ founding documents and ethical constraints and favor simpler models with less moral ambiguity.
A broader point ties the debate together. The AI industry may need to show measurable, practical value over the next 12 to 18 months, such as curing disease, improving everyday life and helping people become more productive and earn more. On this view, attention spent on tail probabilities such as a 15% chance of consciousness would be better spent on the real contests over geopolitical power, capital and resources.
Separating facts from judgments
The debate mixes steps that can be confirmed with questions that remain open.
| Category | What it covers |
|---|---|
| Confirmed steps | Private talks with faith leaders and philosophers, a constitution with conscientious-objector language, a usage policy that bans abuse of models |
| Open question | Whether AI models can be conscious and, if so, what moral status they would have |
| Competing judgments | Preparing now for model welfare versus the risk of building an unprovable belief into models |
What readers can do:
- If your company uses Claude or similar models, read the vendor’s constitution and usage policy and find out in advance when the model may refuse a request.
- If you use Claude personally, know that Anthropic’s usage policy prohibits sustained and needless abuse of its models.
- Treat AI consciousness as a question science cannot currently settle. Rather than accepting a probability estimate or one side’s claim as fact, separate what has been confirmed from what is a value judgment.