A capable model is only one part of an enterprise AI agent. An agent—an AI system that carries out tasks—also needs to understand a company’s decisions, work within limited permissions and prove that it performs its assigned job. Salesforce President and Chief Platform and Engineering Officer Rohan Kumar identifies business context as the hardest part: companies may store vast amounts of data without recording the reasoning that makes the data useful.
A decision record is not the whole decision
Consider an employee who asks a manager to approve an exception to a policy. A business system may save the approval, but not the circumstances or judgment behind it. If an agent later encounters a similar case, the recorded outcome alone may not explain what it should do.
The same gap can arise when decisions happen in calls, chats or meetings. A transcript may exist, yet the relevant rationale can remain difficult to retrieve and use. Turning that tacit knowledge into information an agent can work with requires more than giving it access to another database.
▲ Reasoning missing from a decision record
Kumar divides an enterprise agent’s capabilities into three parts: its code, the general intelligence of its underlying model and its knowledge of the specific business. The third part cannot come from general reasoning alone. Salesforce has announced Cora, a CRM reasoning model that draws on 28 years of CRM experience and about a decade of data and AI research. Even a model built for that domain still needs the particular company’s operations and decision history.
Capture judgment where the work happens
Software engineers leave behind source code that records many of their design choices. Business teams often leave less structured evidence of why they chose one exception or response over another. That difference helps explain why improving a model’s coding ability does not automatically give it sound business judgment.
Kumar argues that engineers should work directly with operational staff: observe decisions as they happen, learn which details matter and express that knowledge in software. This could include an API, a defined interface through which an agent can use business information or functions. The aim is not to pretend every judgment follows a rigid rule. It is to make relevant context and decision logic available for testing and use, rather than relying only on a record of the final action.
Give agents a harness, not unrestricted access
An agent harness is the surrounding system used to build, run, test and govern an agent. In an enterprise, it needs to do more than execute code or connect to an API. Kumar’s proposed controls include:
- Evaluation: Test the agent against a golden set, a curated collection of trusted questions and expected answers, to check its behavior.
- A central registry: Keep track of agents across the organization, including which are active and which should be deactivated.
- Agent-specific identity: Give an agent permissions limited to its task instead of automatically passing along every privilege held by the employee who invoked it.
- Data policies: Classify information so the agent can distinguish confidential material from public or less restricted data.
The permission distinction matters because an agent operating under a person’s broad credentials could expose information outside its intended task if it behaves unexpectedly. Scoped access limits what the agent can reach; evaluation checks what it does with the access it has. Neither substitutes for the other.
Prepare context before an agent asks for it
Connecting an agent to every data lake, warehouse and software service, then placing raw material into its prompt, is not the same as providing useful context. A token is a unit of text a model processes. This brute-force approach, sometimes called token maxing, can consume large numbers of tokens without producing reliable answers.
Kumar proposes preparing a trusted context layer in advance. Background processes could organize data during lower-use hours, such as 11:00 p.m. to 5:00 a.m., rather than doing all that work when an agent receives a request. They could build semantic models, which give business data consistent meanings, and ontologies, which organize business concepts and their relationships. Data classification still determines what the agent may use.
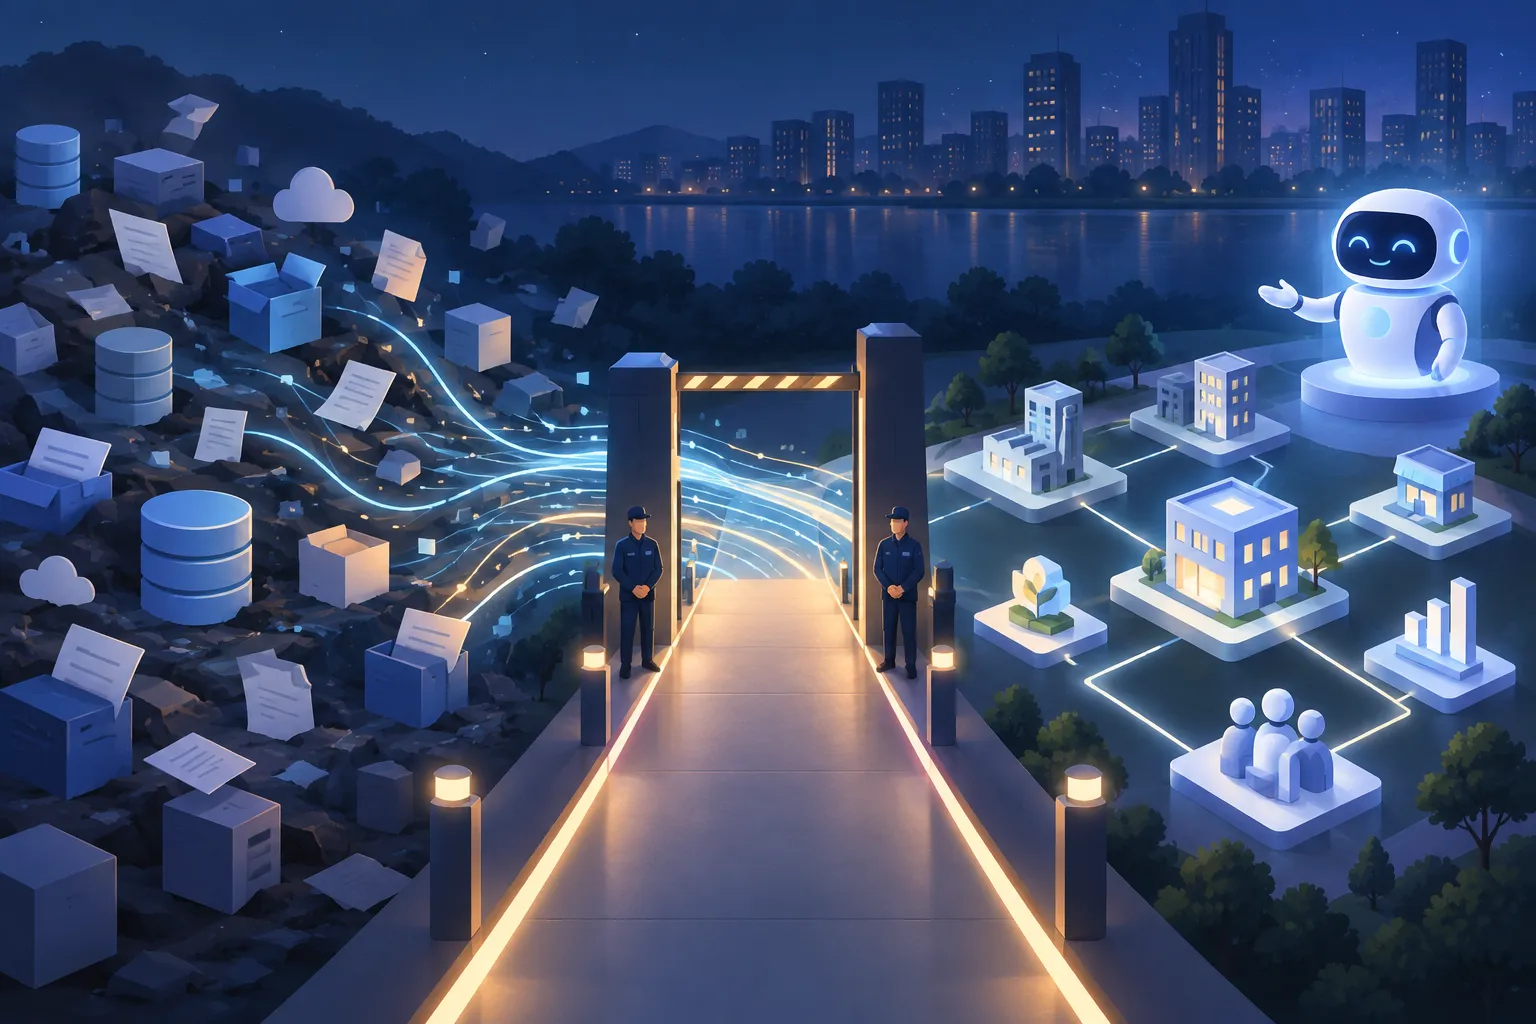
▲ Curated business context for an agent
That preparation is difficult because enterprise information sits in different storage systems and formats. A knowledge graph offers one way to connect it: entities become nodes, and their relationships become queryable links. For example, a Customer can have a Case that follows a Policy. Organizing those connections may help an agent find the business relationship it needs without receiving a raw dump of every source.
Match model cost to the task
The harness also needs model routing: choosing an AI model for a task based on the performance required and the price of using it. A more capable model may be worthwhile for some work, but Kumar argues that using one for every routine request can make enterprise deployment too costly.
The practical question is whether an improvement in the result matters enough to justify its added cost. When extra capability brings no practical business gain, the harness should send the work to a lighter, less expensive model. In this view, model choice is part of the same harness as context preparation and access control rather than a separate decision made later.
What to do before expanding agent use
A stronger model cannot recover reasoning that an organization never captured, and a well-organized data layer cannot make excessive permissions safe. The work is to develop these parts together:
- Review a workflow that logs approvals or exceptions and ask whether it also records why they happened.
- Have engineers observe the people making those decisions and translate relevant context into agent-readable software.
- Test the agent with a golden set, register it centrally and limit its credentials to the assigned task.
- Curate permitted data before queries arrive, then compare model performance and cost for the work the agent actually performs.
These steps make the agent’s business knowledge, behavior, access and expense visible. They also give people a clearer basis for deciding which tasks an agent is ready to handle.