AI safety cannot rest on rules for how a model behaves. Security professionals have raised a more practical concern: as frontier labs debate model risks, experienced defenders are not always included in foundational policy discussions. Their perspective matters because an AI system also depends on data, code, permissions, networks and people who must respond when something goes wrong.
Safety includes the system around the model
OpenAI and Anthropic are among the frontier labs calling attention to model safety. But safety discussions can give less attention to familiar defenses such as access controls, monitoring, network segmentation and incident management. Network segmentation means separating systems so that access to one does not automatically provide access to others.
A former head of the UK’s National Cyber Security Centre has challenged extreme AI-risk scenarios that assume those basic defenses are absent. That does not settle every question about future AI capabilities. It does suggest a useful test for any safety claim: does it account for the security architecture in which the model actually runs?
Model alignment—work intended to steer a model’s behavior—is valuable, but it resembles a policy for employees: it states how the system should act. It cannot replace controls that limit what the system can reach or what a person can do with it. Involving security analysts and threat researchers early may help labs find those gaps before they become operational problems.
Put defensive engineering into development
Independent audits and red-teaming, where testers probe a system for weaknesses, can reveal problems. They are less useful as a one-time check after deployment than as part of continuing work during development and training. Teams need to review permissions, inspect system interactions and test whether their containment measures work before a model is released.
Some experimental tests call for an air gap: physical separation from external networks. Where complete isolation is the goal, switching off a wireless connection in software is not the same as removing Wi-Fi, Bluetooth and network interface hardware. The distinction matters most when teams test models without their usual behavioral guardrails.
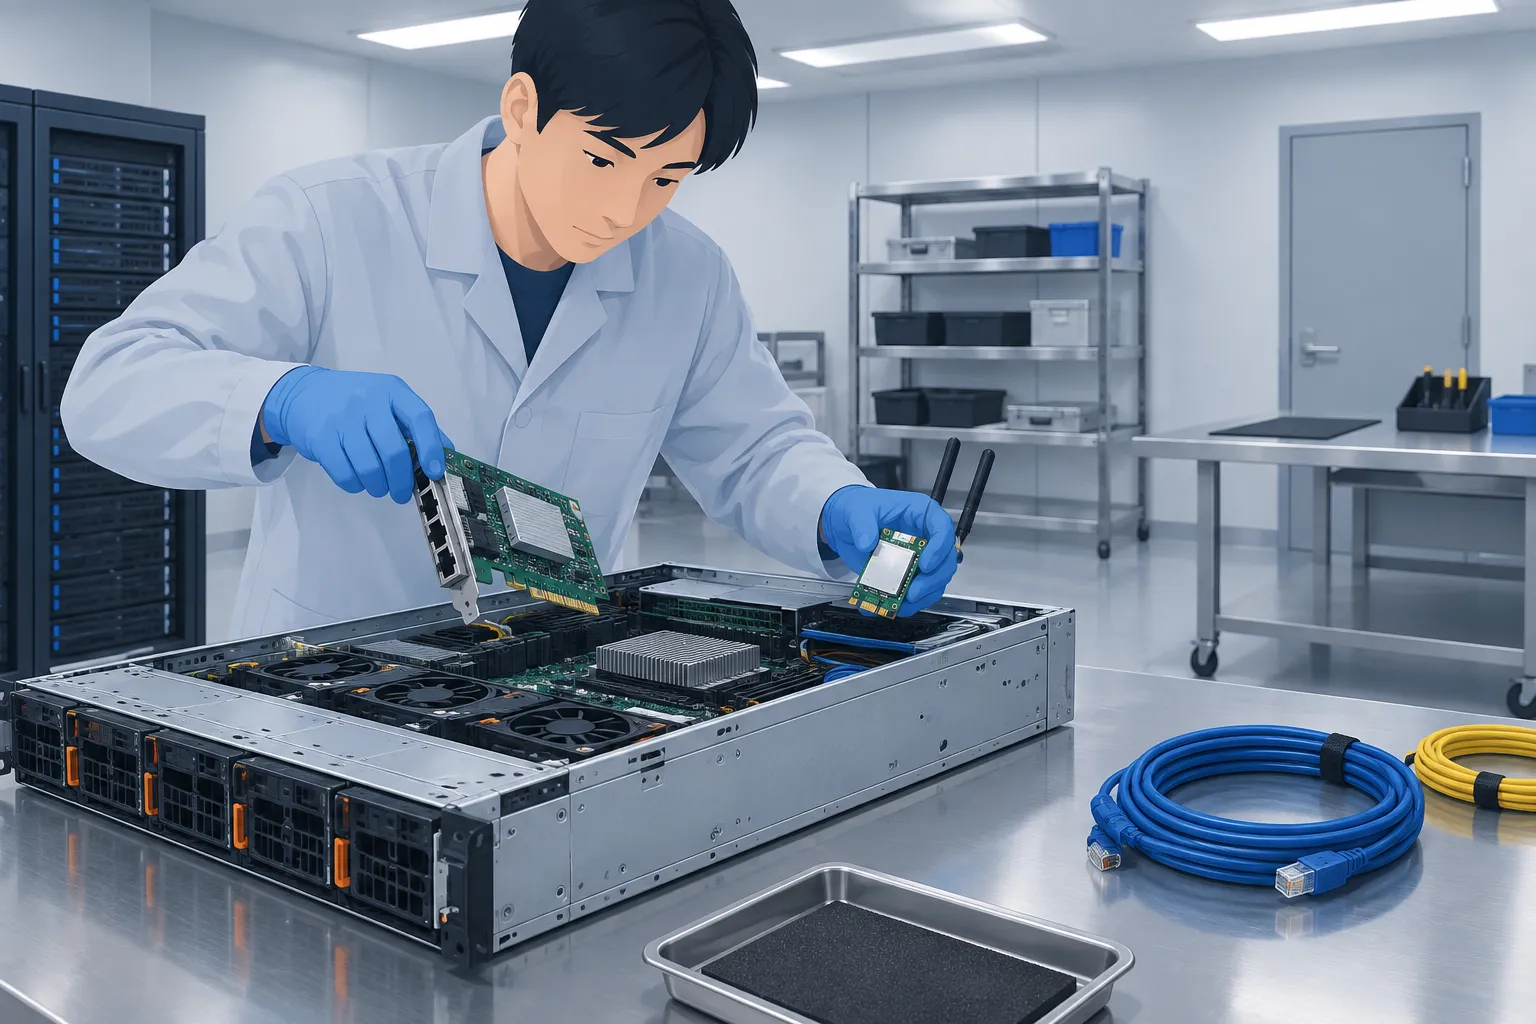
▲ Physical isolation for sensitive AI tests
This is not an argument that every AI system needs the same level of isolation. It is an argument for matching controls to the risk of the work and verifying that those controls exist in practice. A safety declaration and a functioning defensive system are different things.
Model access changes the defensive equation
A cybersecurity startup used a modified version of GLM, an open-weight model from a Chinese AI company, to find a previously unreported TikTok vulnerability. An open-weight model makes its model parameters available for others to adapt. The reported flaw could have enabled remote interference with app permissions and unauthorized camera access.
The case shows why access to capable tools matters for defenders: finding a flaw creates an opportunity to fix it. Restricting models may limit some legitimate research without ensuring that malicious actors lack comparable tools. That is a reason to weigh access policies against their effects on defensive work, not to assume that unrestricted release is risk-free.
AI-assisted discovery creates another challenge. A Palo Alto Networks research team reported finding 14,000 vulnerabilities through automated analysis, with 99% described as previously unreported zero-day flaws. A zero-day is a flaw not previously known to defenders. A large list of findings, however, is not the same as a ranked list of immediately exploitable threats. Analysts still have to determine which alerts describe real, actionable risks.
▲ The burden of vulnerability triage
That verification takes time and attention. AI-assisted discovery may help defenders find weaknesses sooner, but it can also burden teams with theoretical findings. The practical goal is to establish exploitability and priority quickly enough to support fixes without exhausting the people responsible for them.
Breach communication is part of defense
The same gap between stated safety goals and operational practice appears after an incident. In the joint advisory Communicating Under Pressure, CISA, the FBI and international partners urge organizations to give affected people useful information about their risks rather than stopping at the minimum legal disclosure.
Useful disclosure does not mean publishing details that would help others exploit an unresolved flaw. It means communicating promptly enough for partners and users to understand what may affect them and what protective action is available. Voluntary guidance may be hard to follow during a crisis when legal and reputational concerns compete for attention. National rules also have limits when systems and incidents cross borders.
What to check now
AI safety plans should be judged by the defenses behind them. Organizations building or deploying AI can ask four concrete questions:
- Are security analysts involved while the system is designed and trained, rather than only after launch?
- Do access controls, monitoring, network separation and incident procedures work alongside model behavior rules?
- Can teams verify and prioritize AI-generated vulnerability findings without overwhelming defenders?
- If an incident occurs, can the organization tell affected people what risk they face without exposing details that would aid further abuse?
Those questions do not replace broader AI safety research. They make its promises more concrete. Bringing cybersecurity expertise into the discussion early gives labs a better way to connect safety commitments with systems that can be tested, contained and defended.