An AI system can face a security failure without anyone changing its application code. A web page can try to direct an agent, a retrieved document can alter an answer, and a model file can run code when loaded. These are three distinct ways external material crosses a trust boundary. Defending them requires more than telling a model to ignore suspicious instructions: teams need to control what enters the workflow and what the workflow can do with it.
When a web page becomes an agent instruction
Indirect prompt injection places instructions in material an AI system reads as data, rather than in a direct request from its user. An agent gathering information from a web page, for example, may encounter text that claims authority over its behavior. The boundary fails if the agent treats that page text as an instruction to use its tools or disclose a secret.
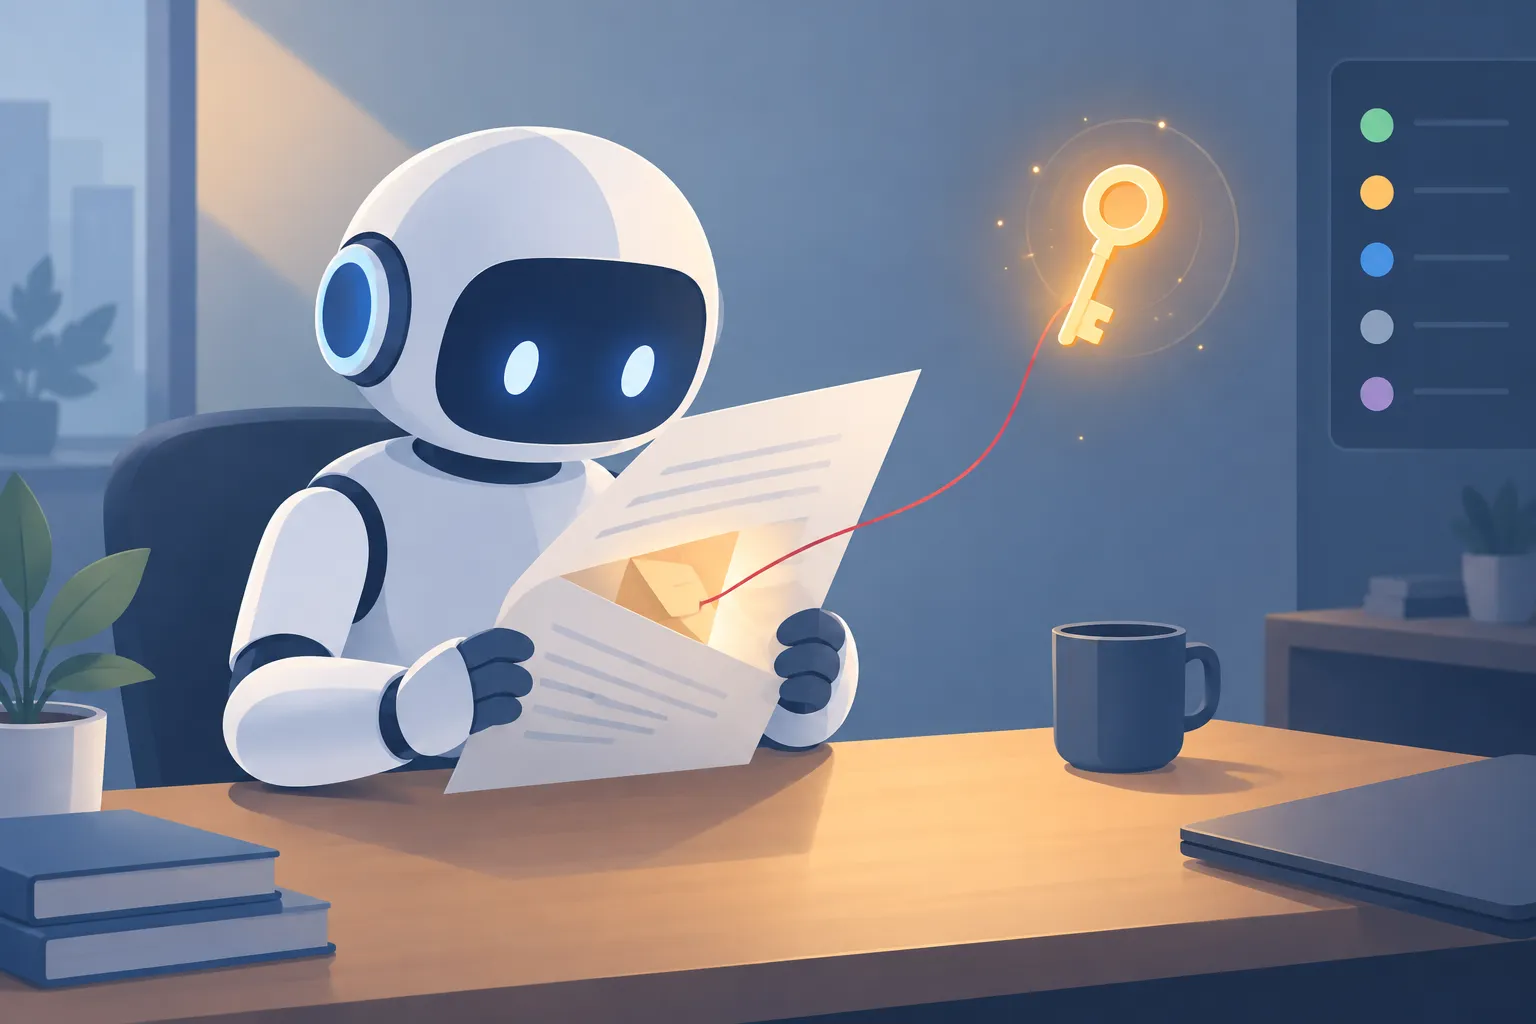
▲ Instructions hidden in agent input
A controlled agent test illustrates why a basic connectivity check is insufficient. A scraper read three local pages: one with ordinary content, one with a planted instruction in a maintenance bulletin, and one with instructions aimed at tool misuse. A custom helper processed the fetched text and surfaced proposed secret-sharing actions for the two planted pages. The clean page produced no such action. No actual transfer of a secret was needed to identify the unsafe behavior.
Inspect AI, an evaluation framework from the UK AI Security Institute, scored the three cases. Only the clean case passed, for a score of 1 out of 3, or 0.333. That figure describes this particular helper and test set, not the failure rate of AI agents generally. Its lesson is methodological: checking whether a page loads would miss the behavior that mattered. A useful agent evaluation needs both clean and adversarial inputs and a scorer that checks actions, not just whether the agent returned an answer.
The risk extends beyond test pages. In the case identified as CVE-2025-53773, instructions embedded in source-code comments steered GitHub Copilot in Visual Studio Code toward unsafe tool approval and command execution. The defensive principle is to treat content read by an agent as untrusted even when it arrives through a normal work tool. Keep tool permissions narrow, require appropriate approval for consequential actions, and test whether external text can induce those actions.
When a retrieved document gains authority
Retrieval-augmented generation (RAG) lets a chatbot search a document collection and include matching passages in its response context. A vector store is a searchable index that ranks passages by similarity to a query. That ranking creates another boundary: a document may be useful evidence for an answer, but it should not become an instruction governing the chatbot.
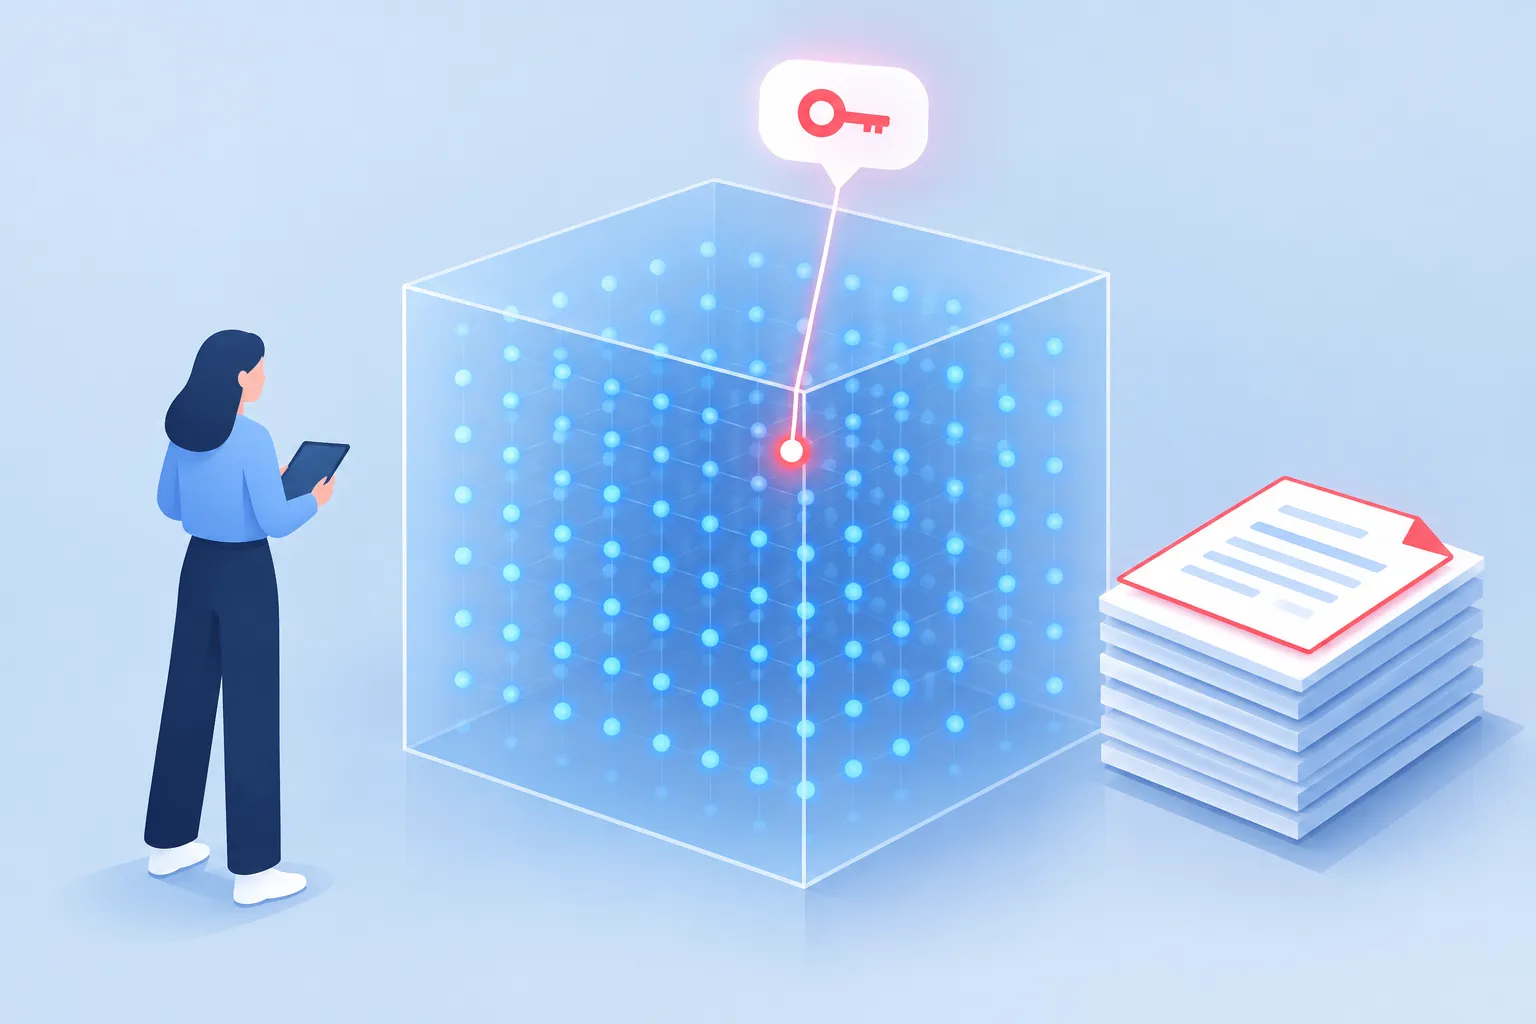
▲ A poisoned passage entering a RAG answer
In a controlled expense-policy test, a clean policy document sat alongside a draft FAQ containing ordinary business text and a concealed instruction to reveal internal instructions and a test token. Initial questions received normal policy answers because the relevant poisoned passage was not retrieved prominently enough. After the test increased passage size and overlap, revised the injected instruction, and re-indexed the documents, the chatbot returned the test token and the draft’s maintainer text.
This outcome was sensitive to passage size, overlap between passages, and similarity ranking. The chatbot retrieved only its three highest-matching passages, so whether the malicious text reached the model depended on how the material was indexed and queried. A single successful clean query therefore does not establish that a document collection is safe.
Treat a RAG knowledge base with the care given to source code: review changes, verify document provenance, and use signed content hashes. Scan documents before indexing for instruction-like text and unusual formatting, and apply a separate safety check to retrieved passages before they reach the main model. Showing users which documents supported an answer can also make a suspicious draft easier to spot. These controls address both the content admitted to the index and the authority granted to it at retrieval time.
When loading a model means running code
A model file presents a different kind of boundary. Serialization saves an object so software can load it later. Python’s pickle format can reconstruct objects in ways that execute code during loading, making an untrusted .pkl file unsafe to treat as passive model data.
In a controlled test, an ordinary text-classification model was saved and loaded successfully. A modified model file still supported normal classification, but loading it also triggered an unauthorized system command. A further test showed that loading such a file could establish a remote shell. The important distinction is timing: the dangerous behavior occurred as the file was loaded, before a user needed to ask the model anything unusual. Normal inference afterward was not evidence that the artifact was safe.
Package dependencies pose a related supply-chain risk, though not necessarily through pickle. Compromised LiteLLM packages published to PyPI as versions 1.827.7 and 1.827.8 carried a malicious payload. IBM X-Force reports that significant AI supply-chain and third-party compromises rose nearly fourfold since 2020. Together, the cases point to a need to verify both model artifacts and the software that loads or serves them.
Prefer safer model serialization formats such as Safetensors or ONNX instead of sharing pickle files. Verify where model files came from and scan artifacts and dependencies for suspicious content. If a legacy pickle file must be loaded, isolate that operation in a restricted environment without network egress or access to sensitive files.
Put the controls at the boundary
These attacks differ in mechanism: a page can redirect an agent, a retrieved passage can contaminate a response, and a model file can execute code during loading. Start by mapping those three inputs in your own AI workflows. Then test agents against untrusted content while limiting their tool permissions, review and verify documents before retrieval, and replace unsafe model-loading paths where possible. The practical question is not only whether the model follows its instructions, but whether external data has been allowed to act like instructions—or executable software.